Single aggregation
This guide shows you how to compute summary information on groups of data using single (dedicated) aggregations.
Often when working with data, you want to break the data into subgroups and then perform calculations on the grouped data. For example, a multinational corporation might want to know its average employee salary by country, or a teacher might want to calculate grade information for groups of students or in certain subject areas.
The process of breaking a table into subgroups and then performing a single type of calculation on each subgroup is known as "single aggregation" or "dedicated aggregation." "Aggregation" refers to creating a summary of the data within each group. "Single" or "dedicated" means that only one type of calculation runs at a time.
To compare single aggregations with the other ways Deephaven summarizes data, and to choose between them, see Aggregations in Deephaven.
Deephaven provides many dedicated aggregations, such as maxBy and minBy. These aggregations are good options when you need only one type of aggregation. If you need more than one type of aggregation or have a custom aggregation, multi-aggregation, also called combined aggregation, is a more efficient and more flexible solution.
Syntax
The general syntax is:
Replace DEDICATED_AGG with one of the aggregators listed in Single aggregators. The groupByColumns parameter determines the column(s) by which to group data:
- Passing no grouping columns (for example,
source.lastBy()orsource.countBy("Count")) uses the whole table as a single group. "X"outputs the desired value for each group in columnX."X", "Y"outputs the desired value for each group designated from theXandYcolumns.
Some aggregators take a required argument before the grouping columns:
headByandtailBytake the number of rows.countBytakes the name of the count column.wavgByandwsumBytake the weight column.
Single aggregators
Each dedicated aggregator performs one calculation at a time:
absSumBy- Sum of absolute values of each group.avgBy- Average (mean) of each group.countBy- Number of rows in each group.firstBy- First row of each group.groupBy- Group column content into vectors, one row per group.headBy- Firstnrows of each group.lastBy- Last row of each group.maxBy- Maximum value of each group.medianBy- Median of each group.minBy- Minimum value of each group.stdBy- Sample standard deviation of each group.sumBy- Sum of each group.tailBy- Lastnrows of each group.varBy- Sample variance of each group.wavgBy- Weighted average of each group.wsumBy- Weighted sum of each group.
The examples on this page cover every aggregator in this list except absSumBy, groupBy, wavgBy, and wsumBy. For those four, see the examples on their reference pages.
Select and count rows in each group
In the following examples, we have test results in various subjects for some students. We want to summarize each student's results.
firstBy and lastBy
In this example, we want to know the first and the last test results for each student. To achieve this, we can use firstBy to return the first test value and lastBy to return the last test value. The example groups the results by Name.
For how lastBy decides which row is last, and how to get the last row after sorting by a column, see Find the last row for each key.
headBy and tailBy
In this example, we want to know the first two and the last two test results for each student. To achieve this, we can use headBy to return the first two test values and tailBy to return the last two test values. The example groups the results by Name.
countBy
In this example, we want to know the number of tests each student completed. countBy returns the number of rows in the table as grouped by Name and stores that in a new column, NumTests.
Summary statistics aggregators
The following examples use the source table of student test results created in Select and count rows in each group. It has a Name column, a string Subject column, and an integer Number column of scores. Because of the type restrictions below, the examples remove the string column Subject with dropColumns, so each result contains only score statistics.
Caution
sumBy, avgBy, stdBy, and varBy throw an error on a column of an unsupported type, such as a string column. These aggregators accept string columns:
medianByreturns the middle value in sort order.minByreturns the smallest value in sort order.maxByreturns the largest value in sort order.
In sort order, uppercase letters come before lowercase letters.
sumBy
In this example, sumBy calculates the sum of test scores for each Name.
avgBy
In this example, avgBy calculates the average (mean) of test scores for each Name.
stdBy
In this example, stdBy calculates the sample standard deviation of test scores for each Name.
varBy
In this example, varBy calculates the sample variance of test scores for each Name.
medianBy
In this example, medianBy calculates the median of test scores for each Name.
minBy
In this example, minBy calculates the minimum of test scores for each Name.
maxBy
In this example, maxBy calculates the maximum of test scores for each Name.
Find the last row for each key with lastBy
The lastBy operation creates a new table that contains the last row of the input table for each key. The key columns are the grouping columns you pass to lastBy. A key is one unique value or combination of values in those columns. firstBy follows the same rules but returns the first row for each key.
The "last" row is the row closest to the bottom of the table. It depends only on the order of rows in the source table. It does not depend on values in the data, such as timestamps or sequence numbers. In a live-updating table, it is not necessarily the row that most recently arrived.
When you pass no key columns, lastBy returns the last row in the table:
When you pass key columns (such as MyKey in the example below), lastBy returns the last row for each key:
You can use multiple key columns:
You often use lastBy with time series data to get a table that shows the current state of each key. When data is out of order, sort it before applying lastBy. For example, the data below is naturally ordered by Timestamp1. To find the latest rows based on Timestamp2, sort the data before running lastBy:
If the query doesn't use the sorted table anywhere else, use AggSortedLast instead of sorting first. It avoids sorting the whole table:
- It splits the rows into groups by the key columns.
- Within each group, it finds the row with the largest sort-column value.
- It doesn't build a sorted copy of the whole table, so it typically uses less memory and processing than
sortfollowed bylastBy.
To use it, pass AggSortedLast to aggBy with the sort column as its first argument, followed by the columns to return. The example below reuses t from the previous example and picks the same row for each key as that example's t2, without creating an intermediate sorted table. The key column comes first and rows can appear in a different order. Unlike lastBy, it returns only the key columns and the columns you list after the sort column, so the example lists Timestamp2 too.
Aggregate columns in the UI
You can also aggregate a column in the UI with the Aggregate Columns feature. Unlike the programmatic examples above, it doesn't create a new table with one row per group. Instead, it adds a row at the top or bottom of the table that applies the operation you choose to each column. Use it to quickly see the sum, average, or another aggregate of a column.
In the example below, we add an Average row and a Minimum row to the top of the table:
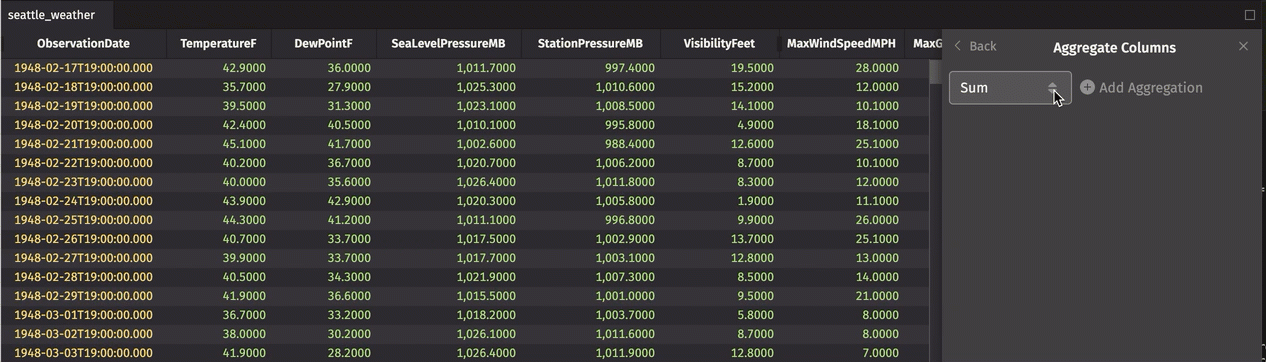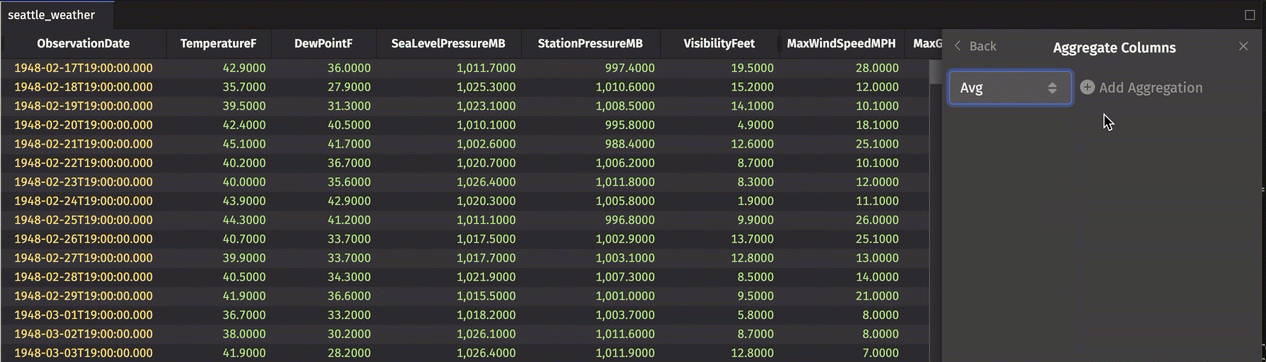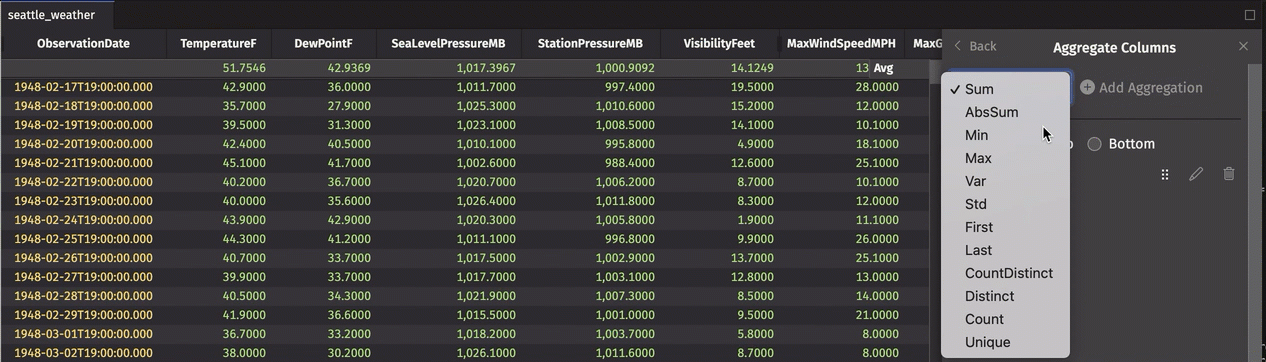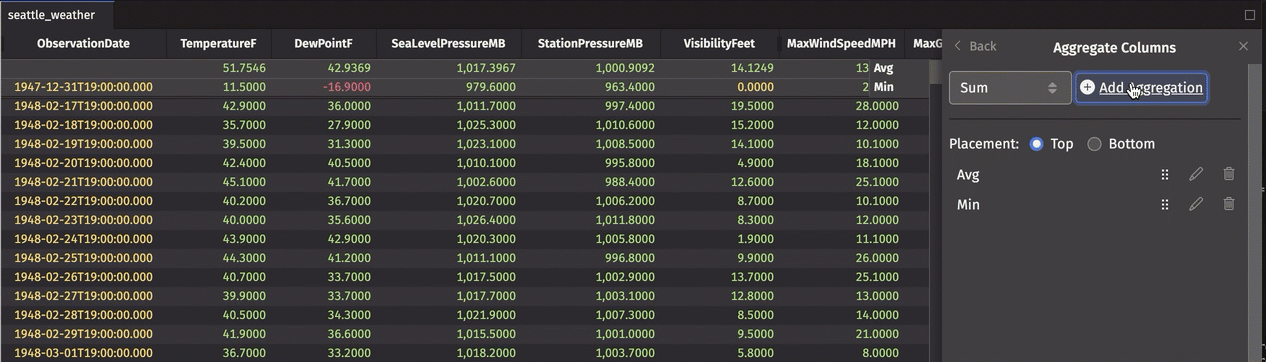
You can reorder, edit, or delete these aggregations in the Aggregate Columns dialog.