Deephaven Community Core Quickstart
This guide shows you how to install and launch Deephaven Community Core, then takes you on a short tour of the Deephaven IDE: importing static and streaming data, transforming and aggregating tables, plotting, and exporting results.
You can install Deephaven Community Core with Docker, pip, or the production application, which runs Deephaven natively on your machine. If you don't have a preference, we recommend starting with Docker.
1. Install and launch Deephaven
With Docker
Docker-installed Deephaven runs in a Docker container, so you need Docker installed on your machine. Install and launch Deephaven with a one-line command:
Caution
Replace YOUR_PASSWORD_HERE with a secure password of your own. The -Dauthentication.psk option sets the password (a pre-shared key) that you use to log in to Deephaven.
The -v option mounts the data folder in your current directory at /data inside the container, so files that Deephaven writes to /data appear in that folder on your machine. Docker creates the folder if it doesn't exist.
For additional configuration options, see the install guide for Docker.
With pip
To install Deephaven with pip, you need Java 17 or later and Python 3.9 or later, and your JAVA_HOME environment variable must point to your Java installation. On Windows, pip-installed Deephaven also requires WSL 2. See the pip install prerequisites for details.
Note
For pip-installed Deephaven, we recommend using a Python virtual environment to decouple and isolate Python installs and associated packages.
To install Deephaven, install the deephaven-server Python package. This guide's plotting example also uses Deephaven Express, so install its plugin at the same time:
Then, launch Deephaven:
If you use an M2 Mac, add -Dprocess.info.system-info.enabled=false to --jvm-args, as described in Start a Deephaven server.
Caution
Replace YOUR_PASSWORD_HERE with a secure password of your own. The -Dauthentication.psk option sets the password (a pre-shared key) that you use to log in to Deephaven.
For more advanced configuration options, see the pip installation guide.
With the production application
To run Deephaven without Docker or pip, follow the production application guide. This guide's plotting example uses Deephaven Express, so after you create the virtual environment, also run pip install deephaven-plugin-plotly-express in the activated virtual environment before you start the server.
2. The Deephaven IDE
If you started pip-installed Deephaven with the deephaven server command, by default it opens the IDE in your browser and logs you in automatically. Otherwise, navigate to http://localhost:10000/ and enter your password in the token field.
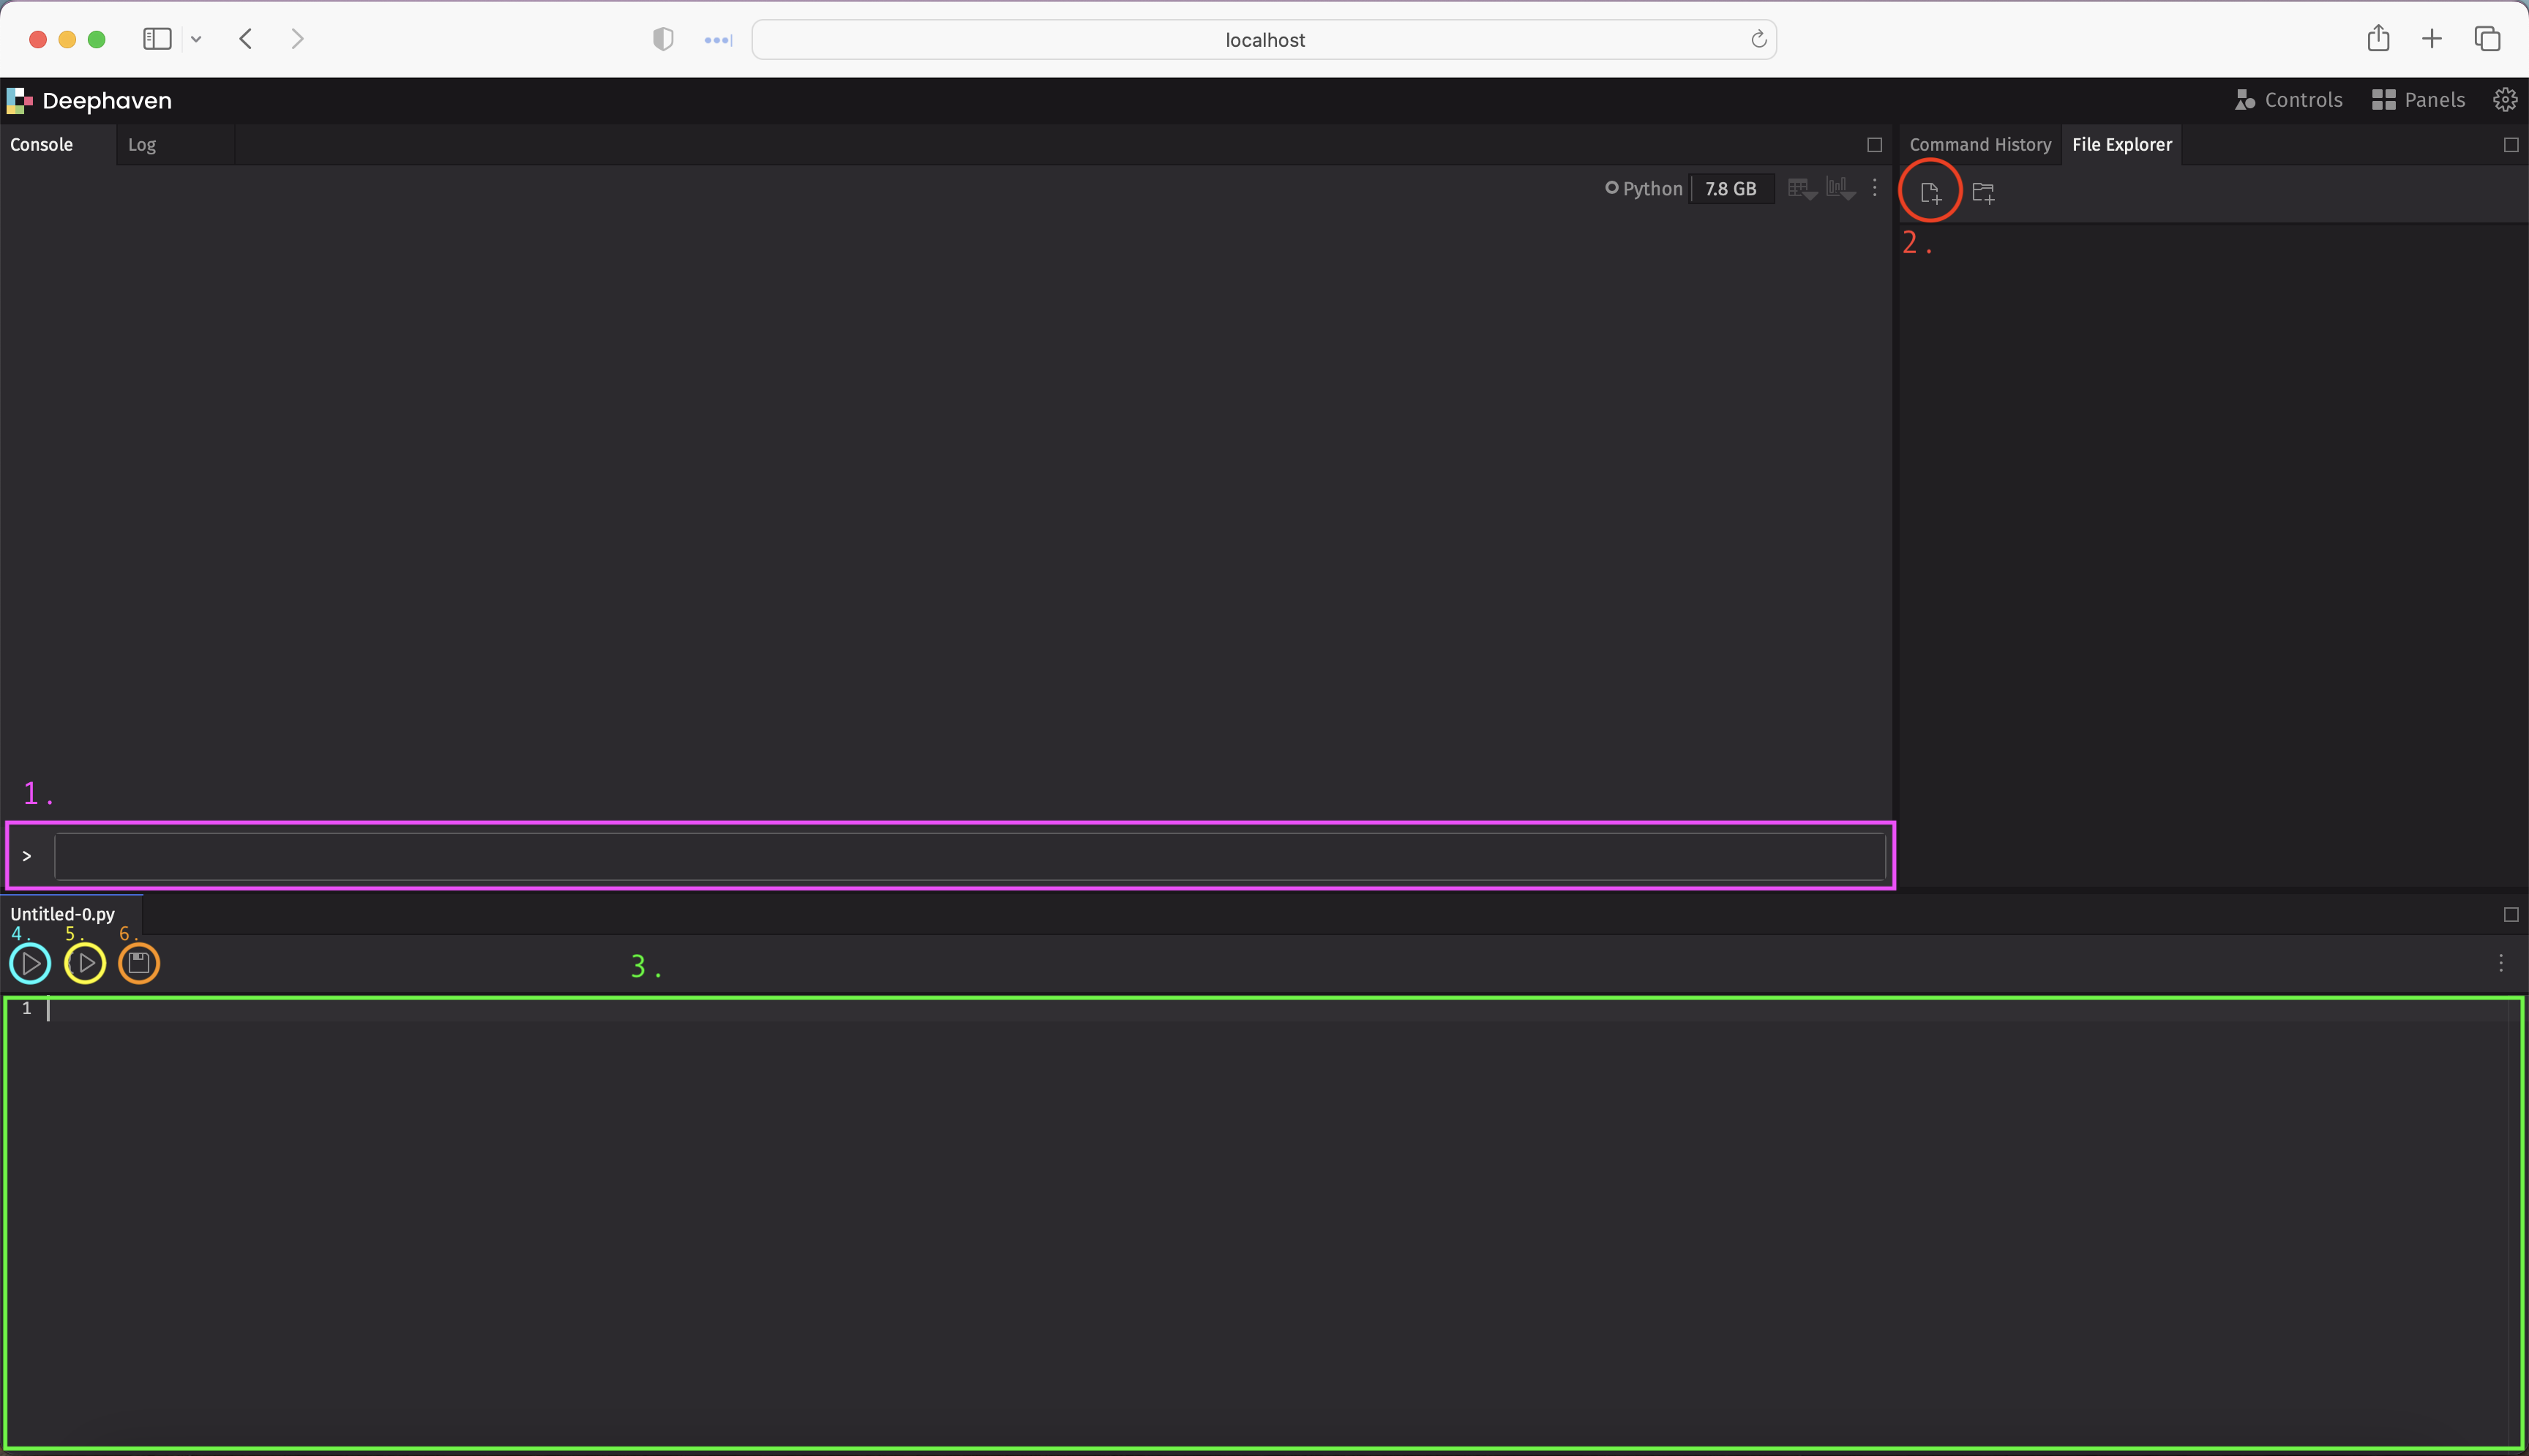
You're ready to go. The Deephaven IDE is a full scripting environment. Here's a brief overview of its basic features.
-
Write and execute commands
Use this console to write and execute Python and Deephaven commands.
-
Create new notebooks
Click this button to create new notebooks where you can write scripts.
-
Edit active notebook
Edit the currently active notebook.
-
Run entire notebook
Click this button to execute all of the code in the active notebook, from top to bottom.
-
Run selected code
Click this button to run only the selected code in the active notebook.
-
Save your work
Save your work in the active notebook. Do this often!
Now that you have Deephaven installed and open, you can explore some of its key features in the rest of this guide.
3. Import static and streaming data
Deephaven works with both static and streaming data, and it can ingest data from CSV files, Parquet files, Kafka streams, and more. This section loads a static CSV file, then replays historical data to simulate a stream.
Load a CSV
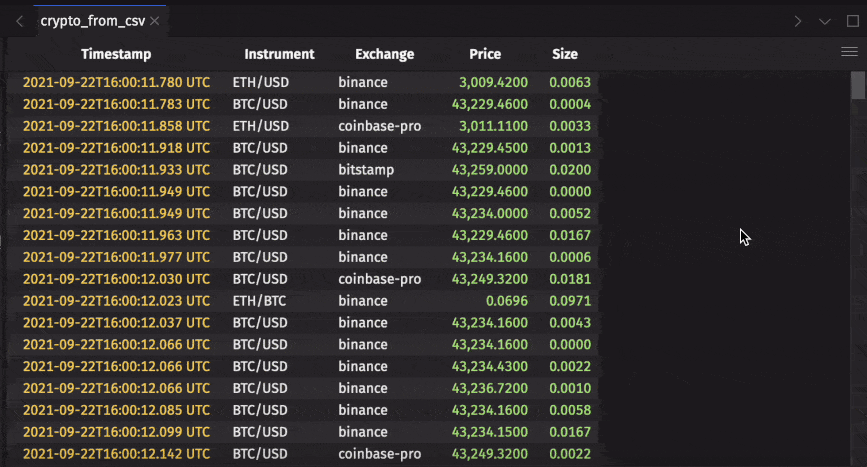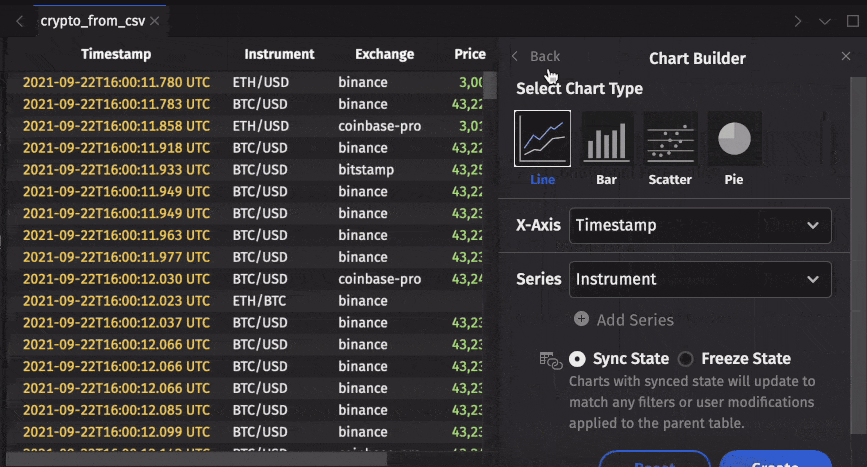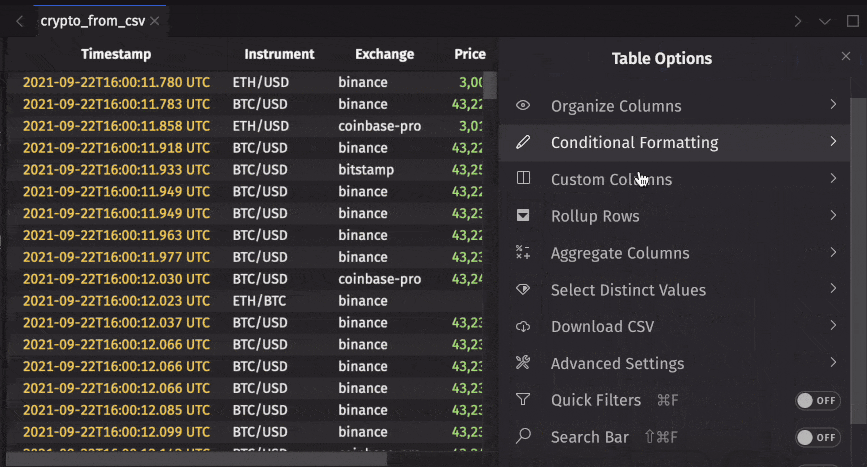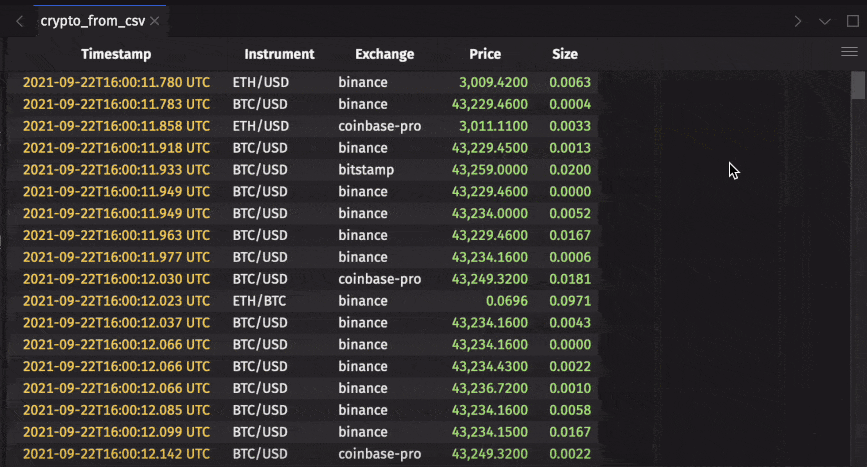
Run the command below inside a Deephaven console to ingest a million-row CSV of crypto trades with read_csv. All you need is a path or URL for the data:
The table widget now in view is highly interactive:
- Click on a table and press Ctrl + F (Windows/Linux) or ⌘ + F (Mac) to open the Quick Filters bar, a filter row above the column headers.
- Click the funnel icon in a quick filter field to open the Advanced Filters panel and build more detailed filters.
- Hover over column headers to see data types.
- Right-click headers to access more options, like adding or changing sorts.
- Click the Table Options hamburger menu at right to plot from the UI, create and manage columns, and download CSVs.
Replay historical data
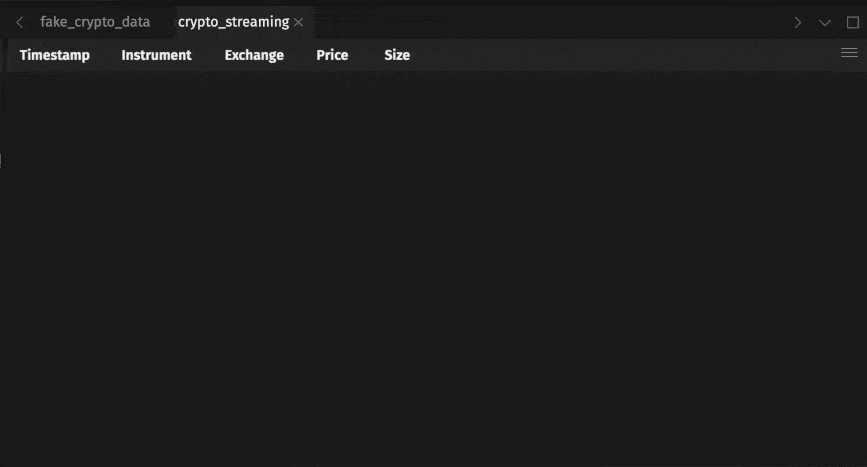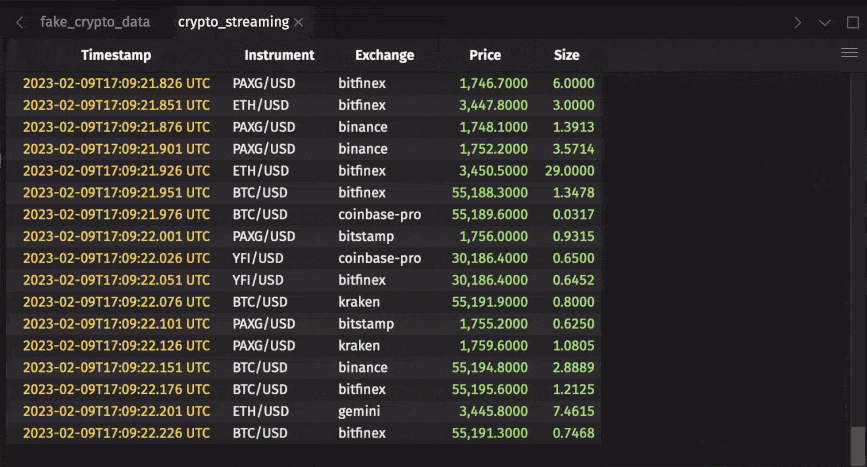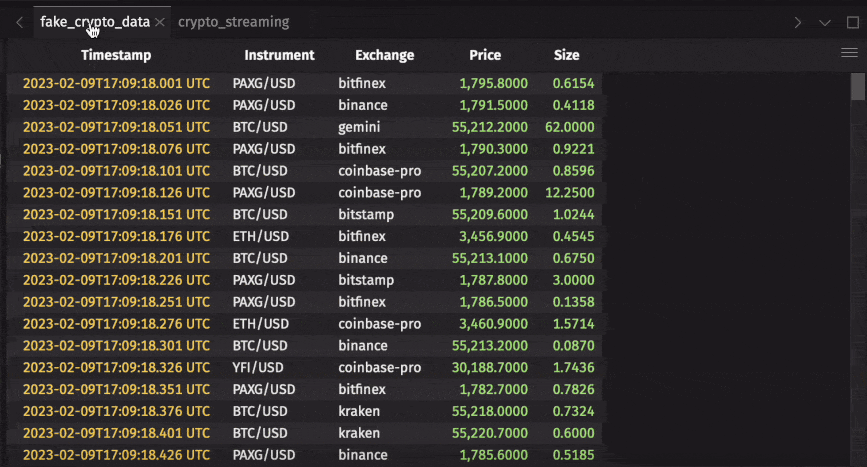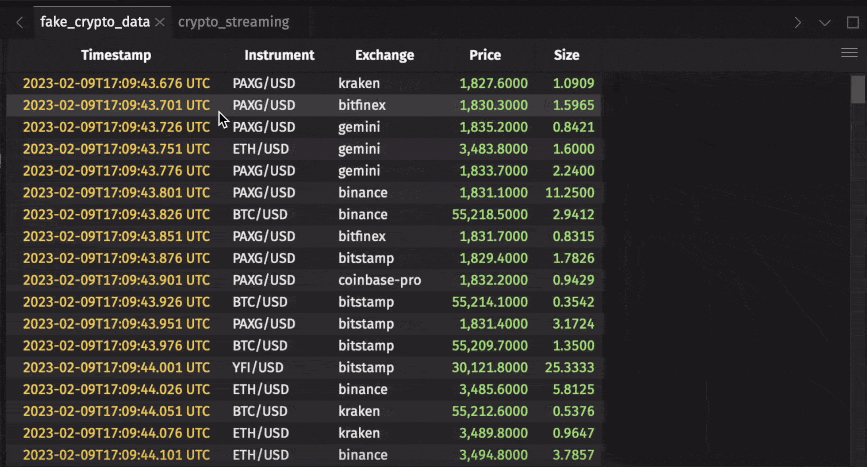
Ingesting real-time data is one of Deephaven's core strengths. However, streaming pipelines can be complicated to set up and are outside the scope of this guide. For a streaming data example, this guide uses Deephaven's TableReplayer to replay historical cryptocurrency data in real time.
The following code takes fake historical crypto trade data from a CSV file and replays it in real time based on timestamps. This is only one of multiple ways to create real-time data in just a few lines of code. Replaying historical data is a great way to test real-time algorithms before deployment into production.
4. Work with Deephaven tables
Deephaven represents both static and streaming data as tables. You can derive new tables from parent tables, and data flows efficiently from parents to their dependents. See the concept guide on the table update model if you're interested in what's under the hood.
Deephaven represents data transformations as operations on tables. This is a familiar paradigm for data scientists using pandas, Polars, R, MATLAB, and more. Deephaven's table operations have one key difference — they work the same way whether the underlying data is static or streaming. This means that code written for static data generally also works on streaming data. A few formulas are exceptions, such as those that use the special variables i, ii, and k.
There are many table operations to cover, so this guide keeps it short and covers the highlights.
Manipulate data
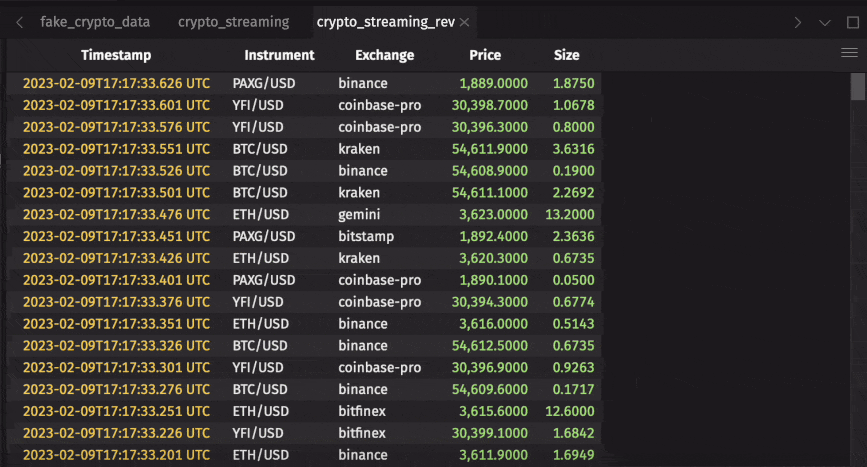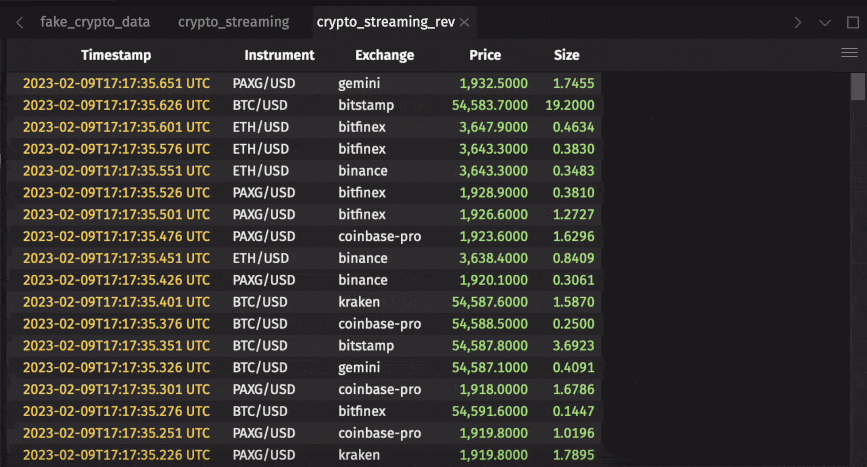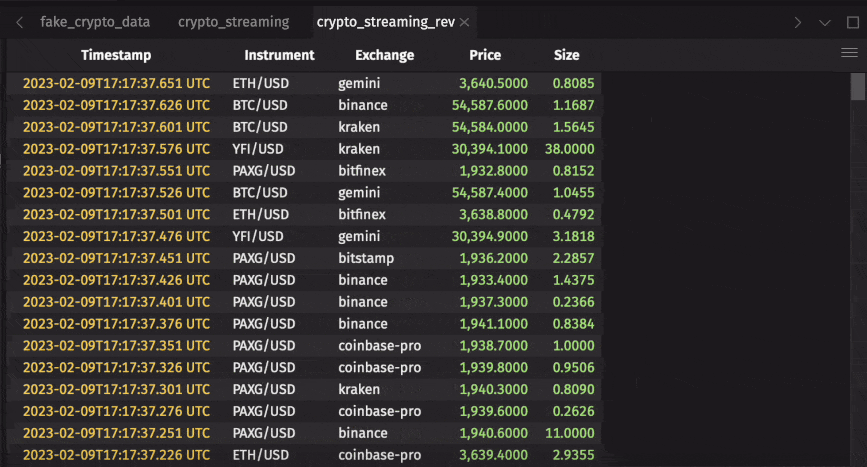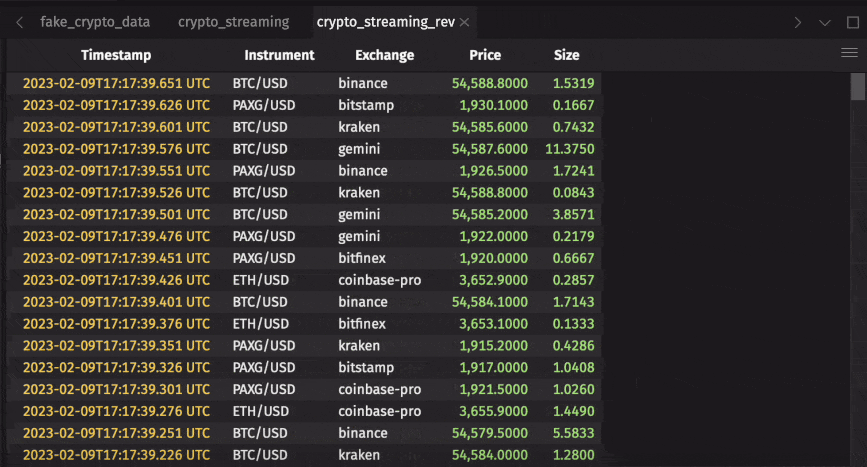
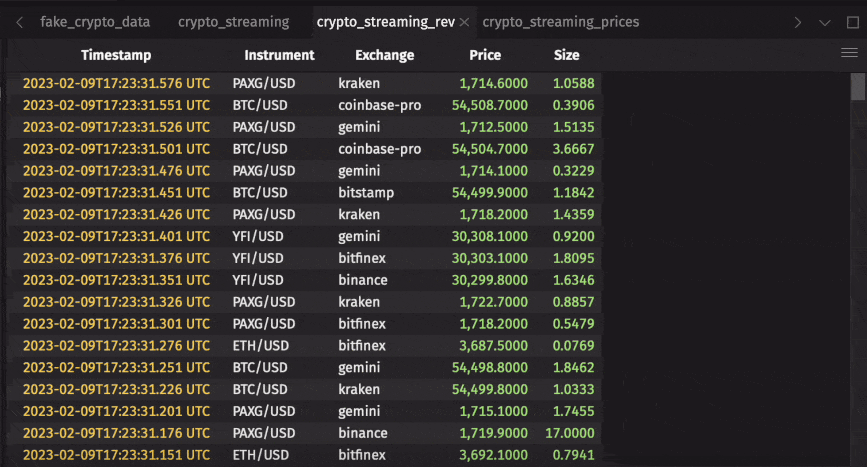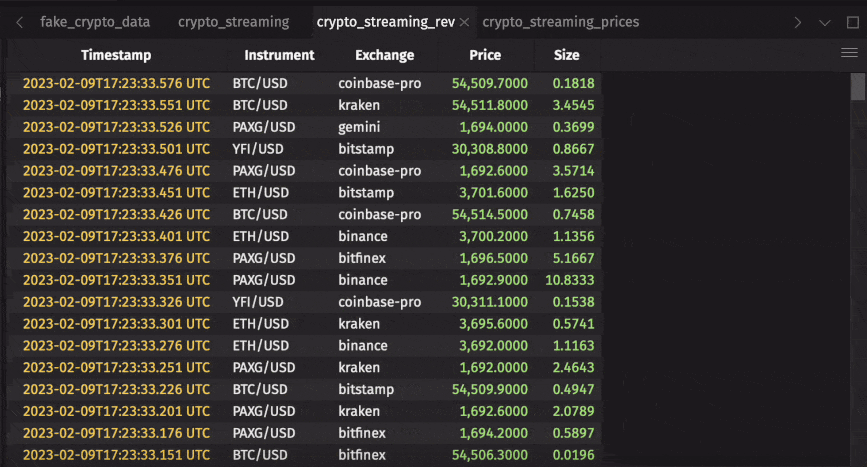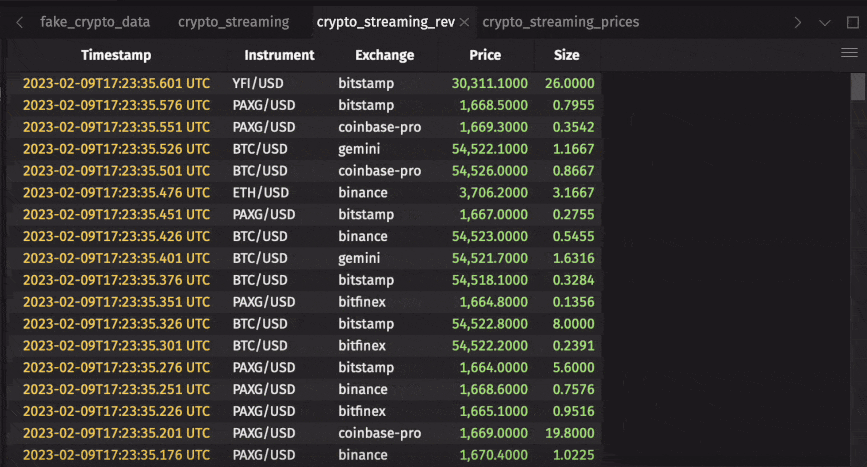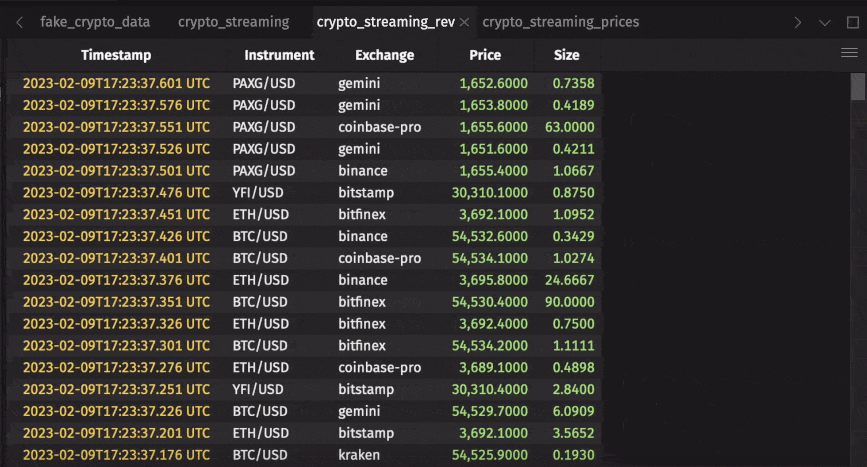
First, reverse the ticking (live-updating) crypto_streaming table with reverse so that the newest data appears at the top:
Tip
You can also perform many table operations from the UI. For example, right-click on a column header in the UI and choose Reverse Table.
Add a column with update:
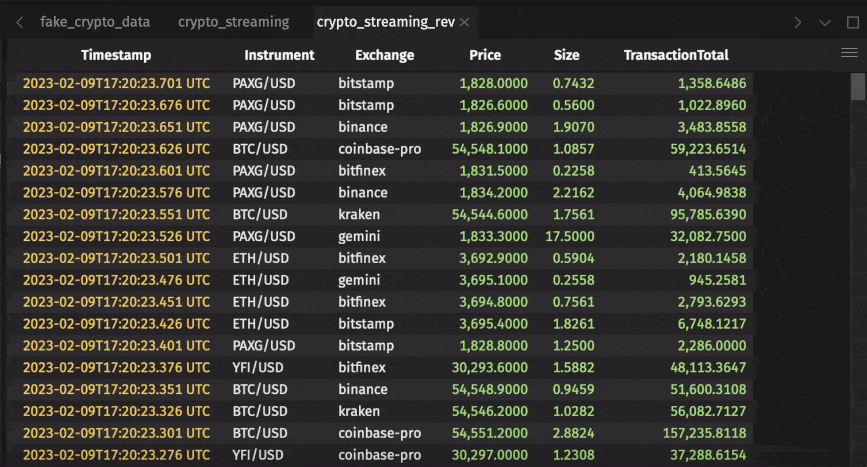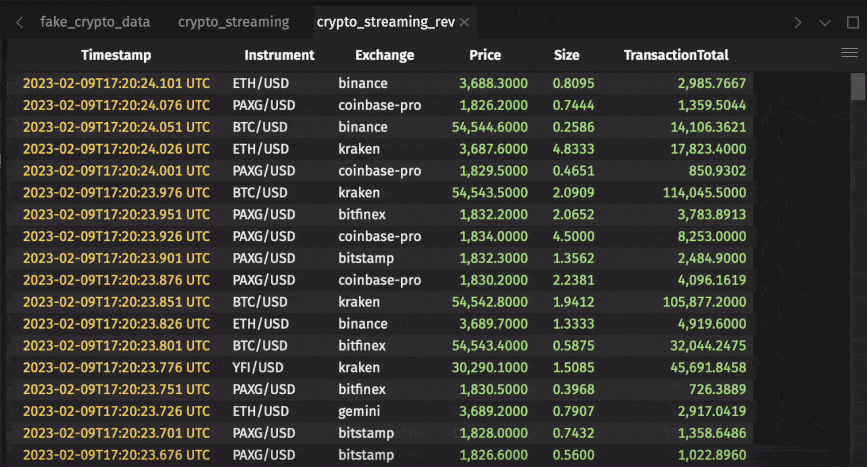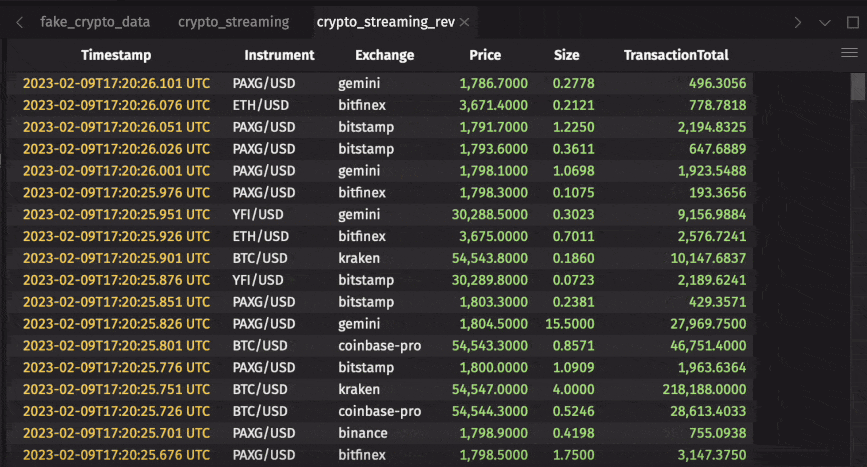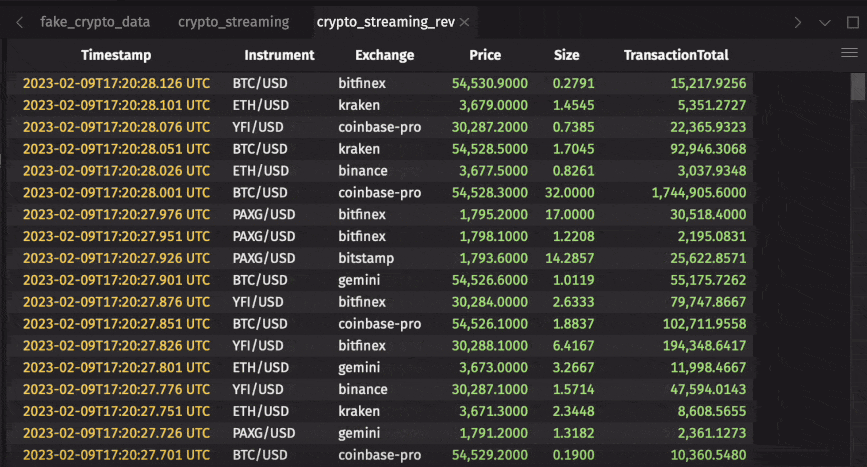
Use view to pick out particular columns. select does the same but computes the columns and stores them in memory, while view computes them on demand:
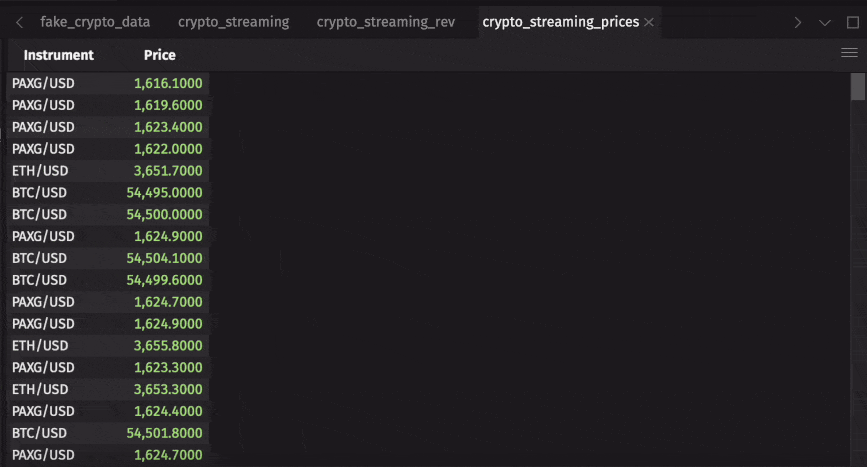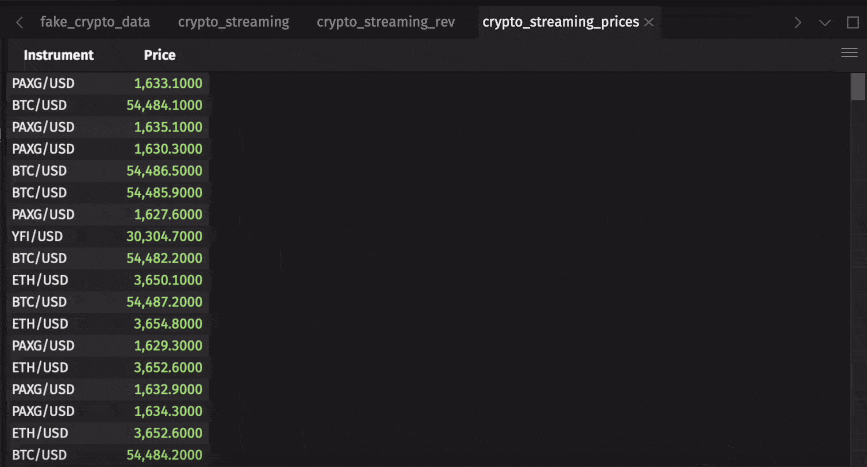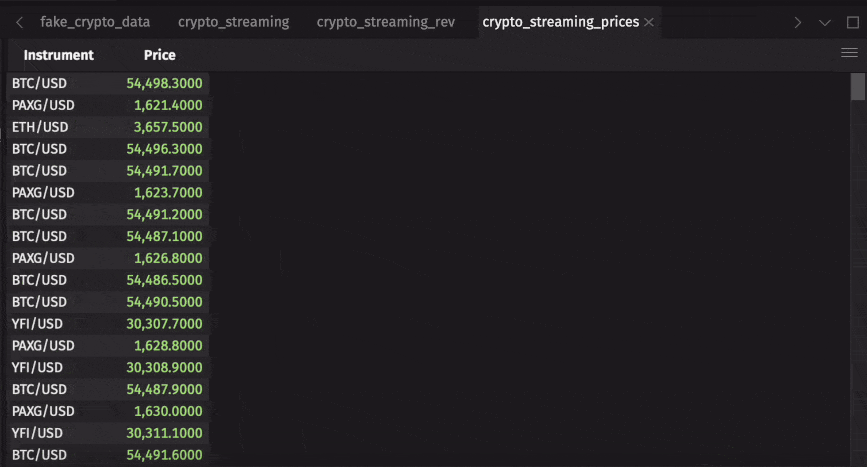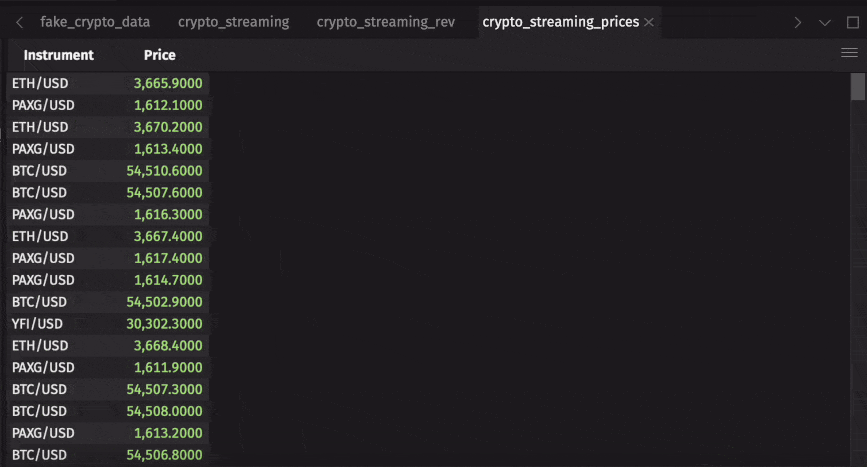
Remove columns with drop_columns:
Deephaven offers many operations for filtering tables, including where, where_one_of, where_in, where_not_in, and others. See the filtering guide for the full set.
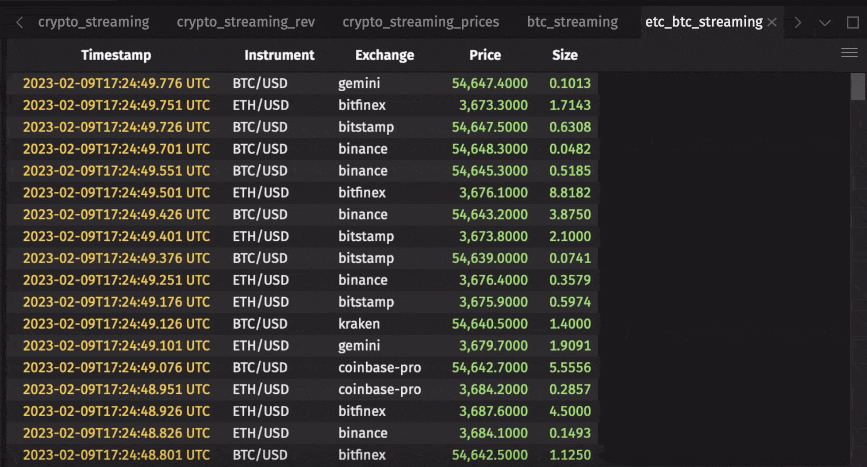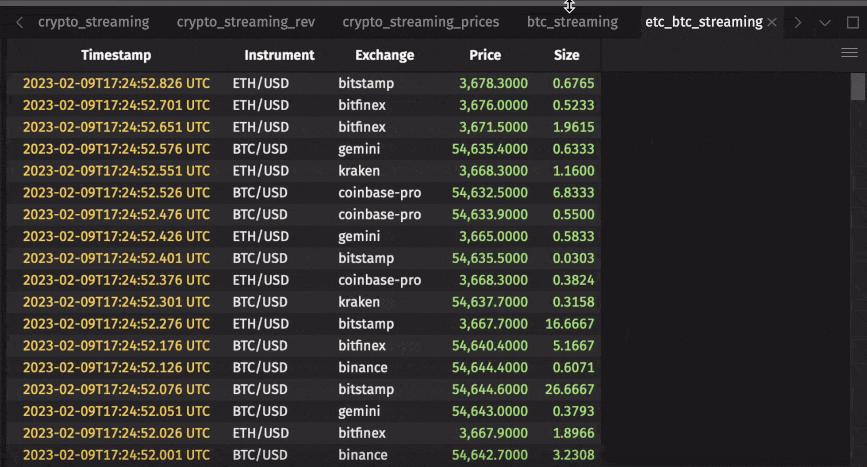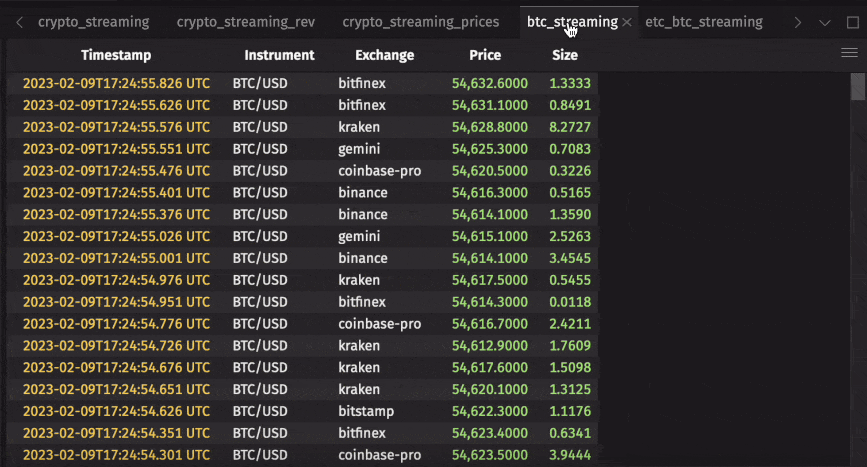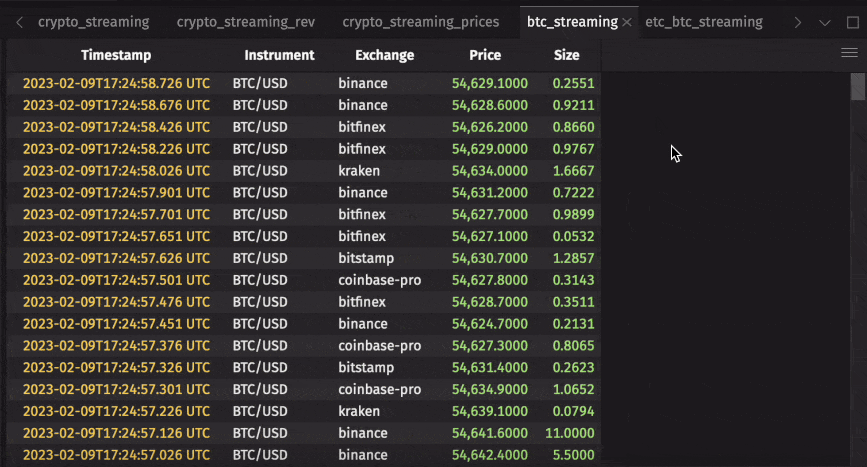
The following code uses where and where_one_of to filter for only Bitcoin transactions, and then for Bitcoin and Ethereum transactions:
Aggregate data
Deephaven's dedicated aggregations suite provides a number of table operations that enable efficient column-wise aggregations. These operations also support aggregations by group.
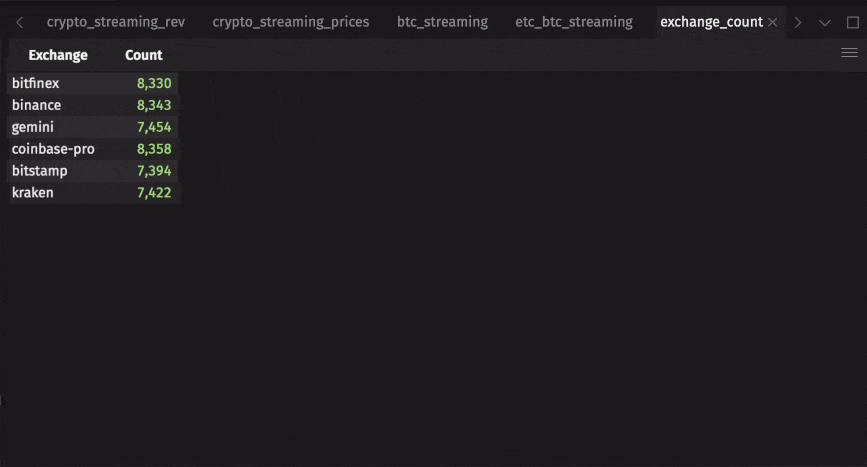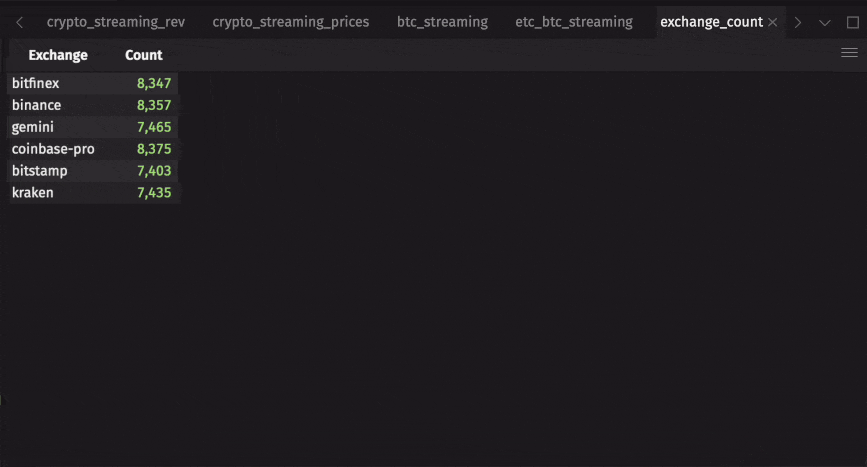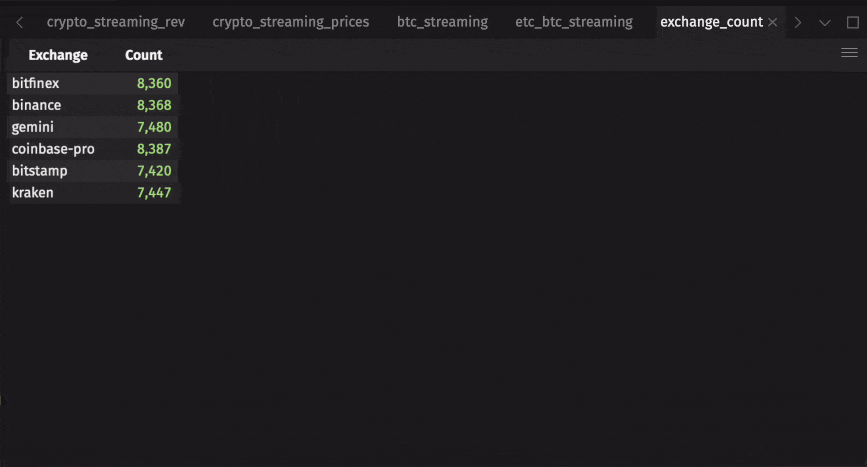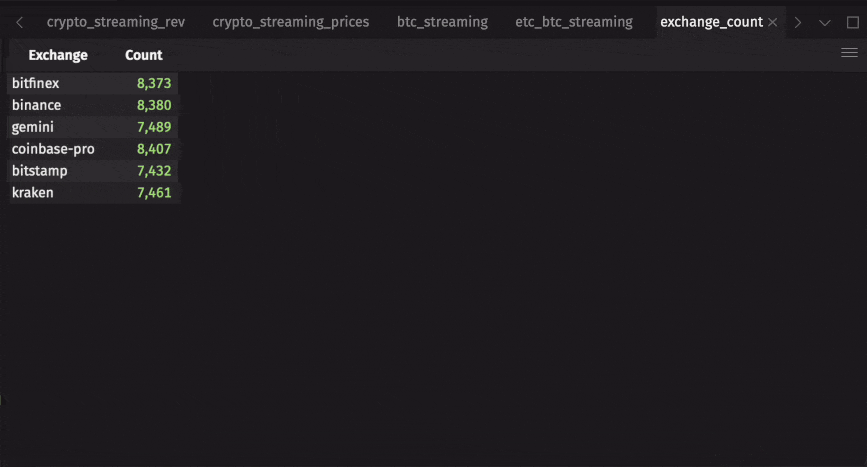
Use count_by to count the number of transactions from each exchange:
Then, get the average price for each instrument with avg_by:
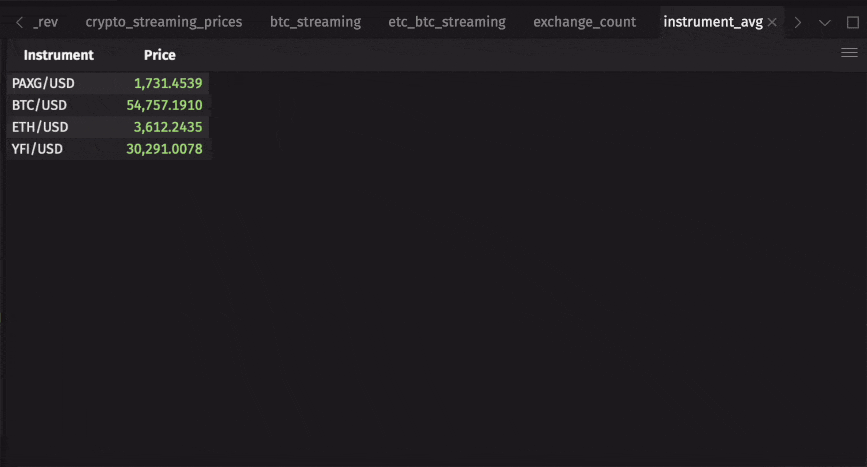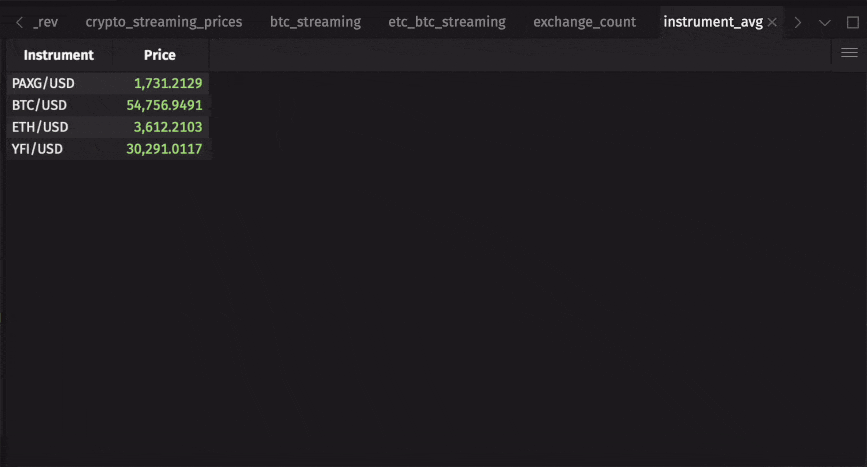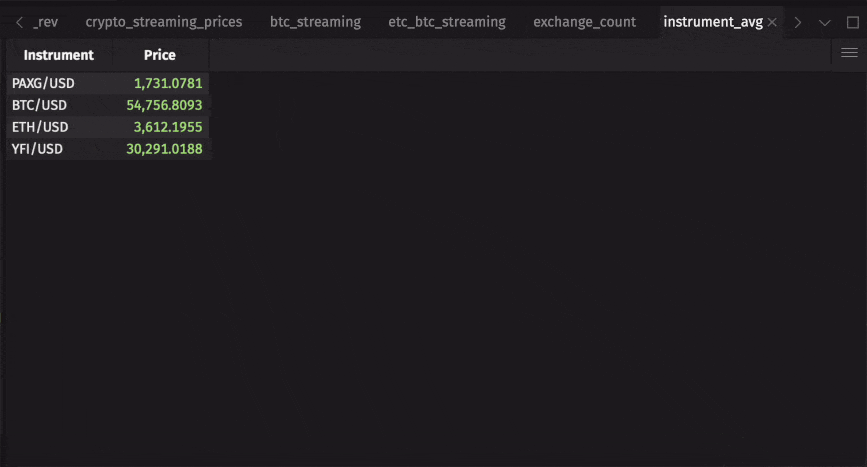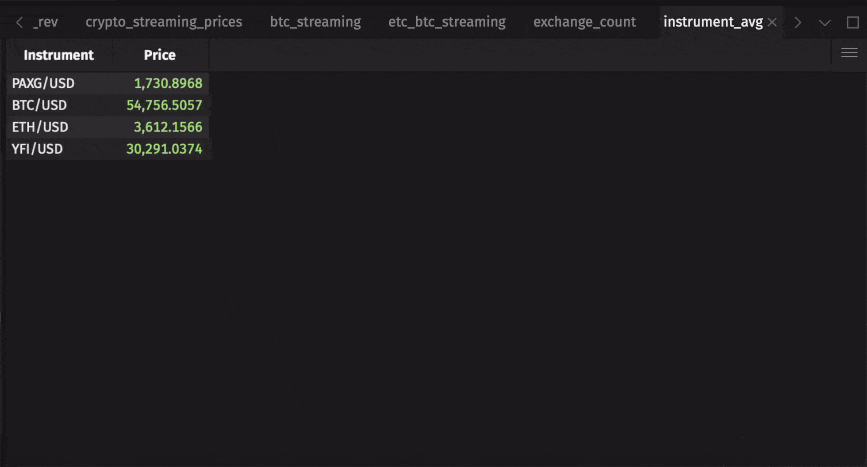
Find the largest transaction per instrument with max_by:
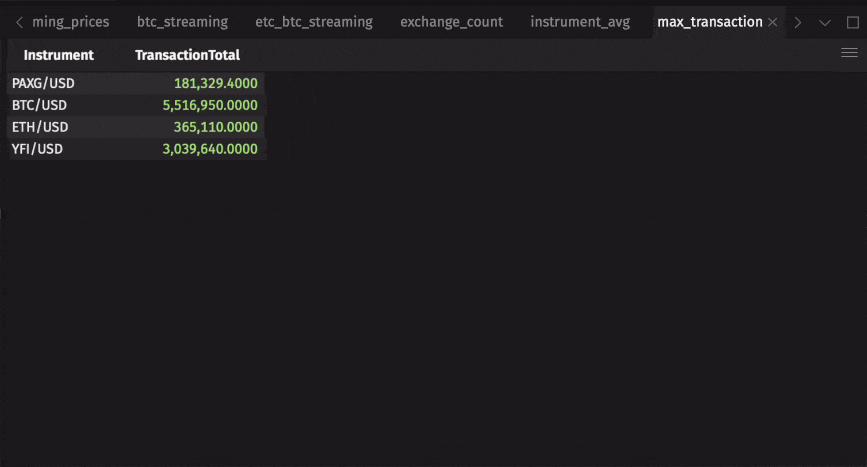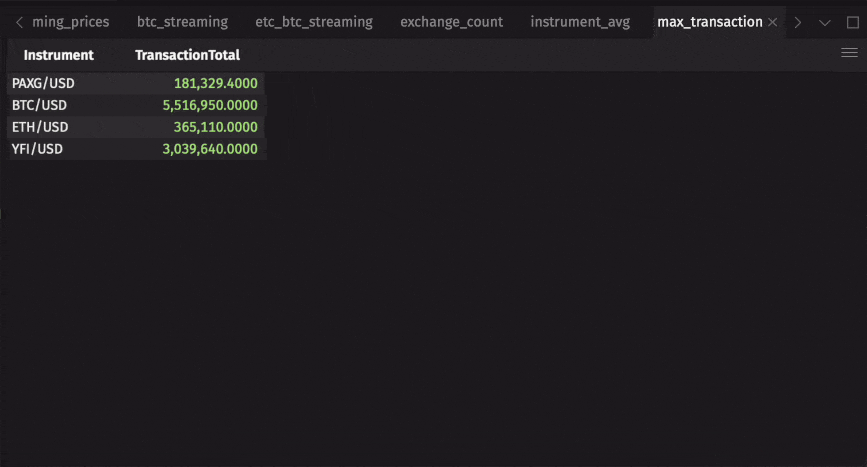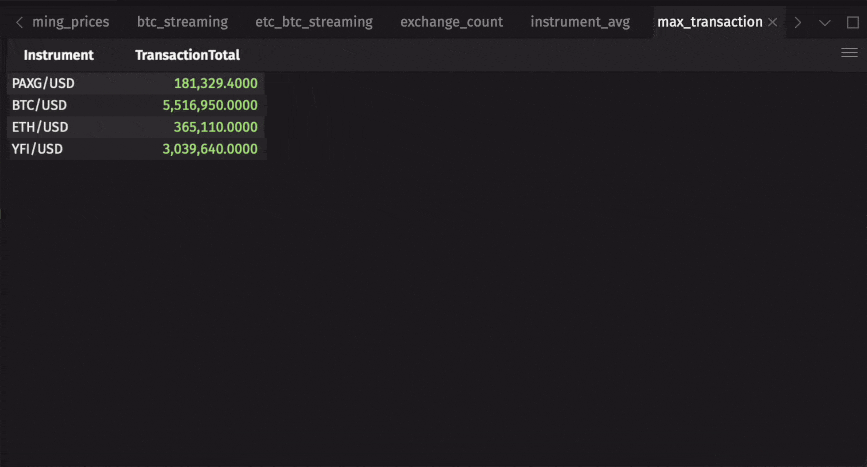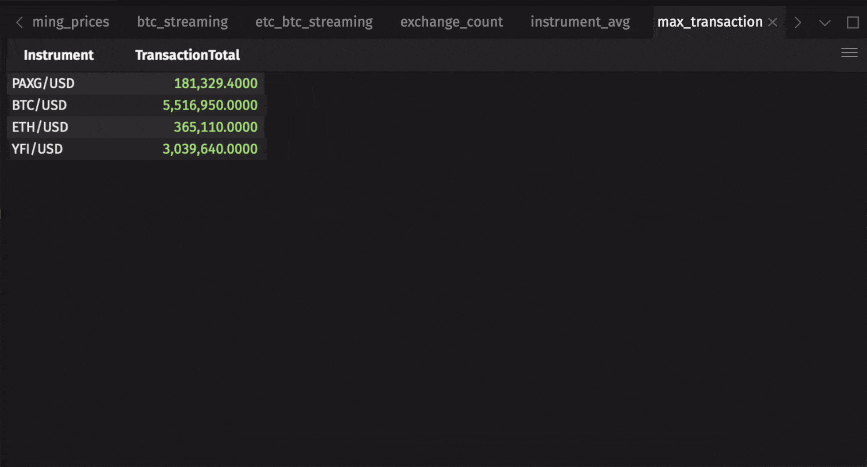
Each dedicated aggregation performs one aggregation at a time. You often need to perform multiple aggregations on the same data. For this, Deephaven provides the agg_by table operation and the deephaven.agg Python module.
First, use agg_by to compute the mean and standard deviation of the price, grouped by instrument and exchange:
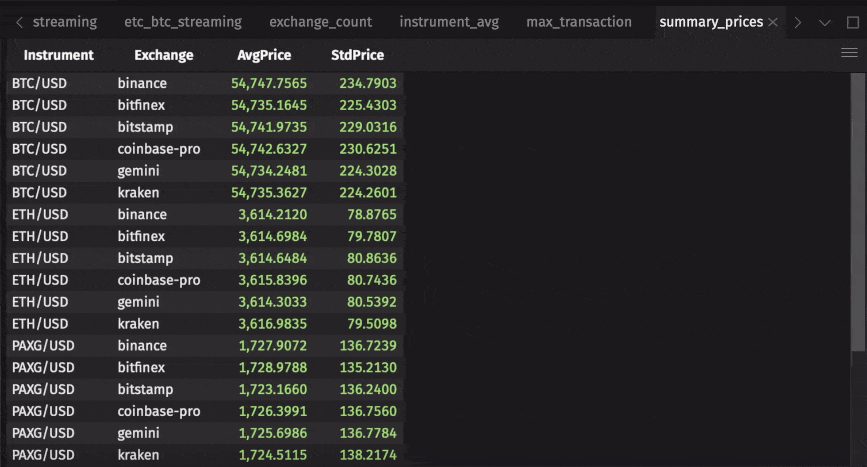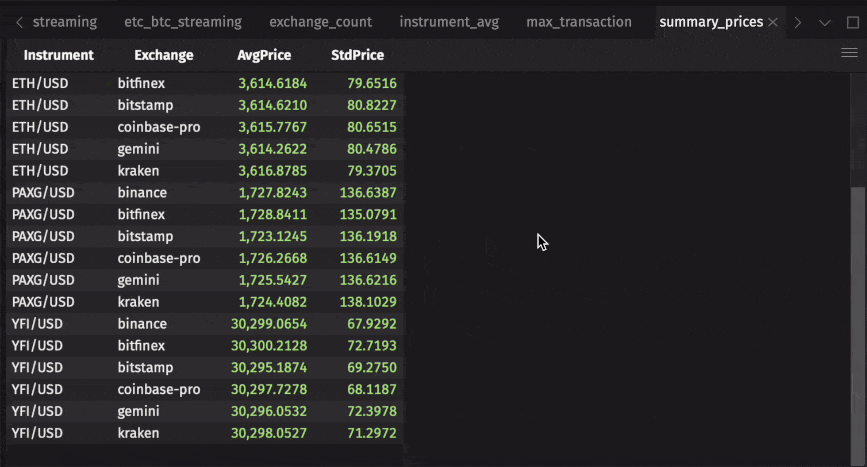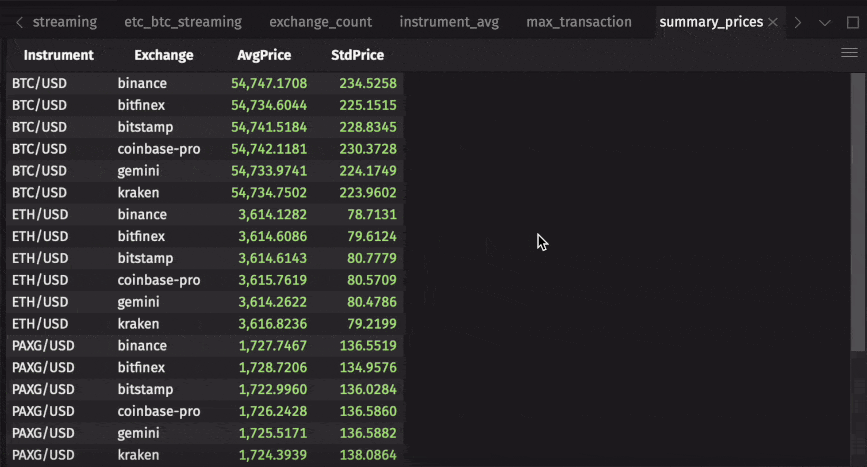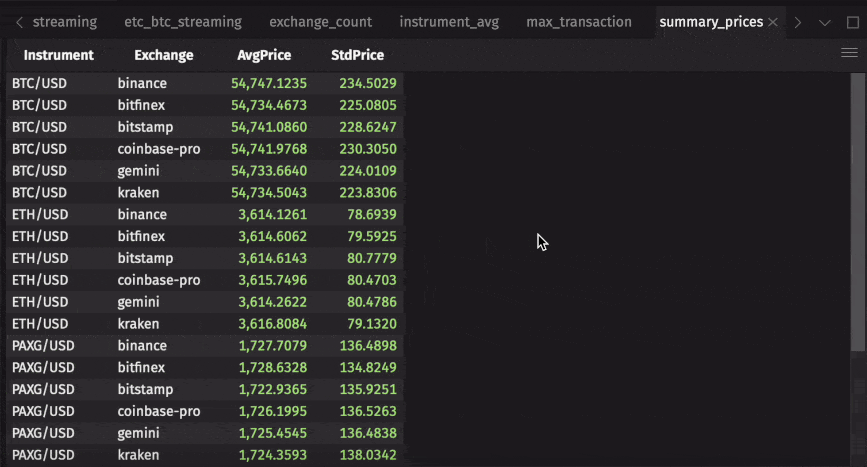
Then, add a column containing the coefficient of variation for each instrument and exchange, measuring the relative risk of each:
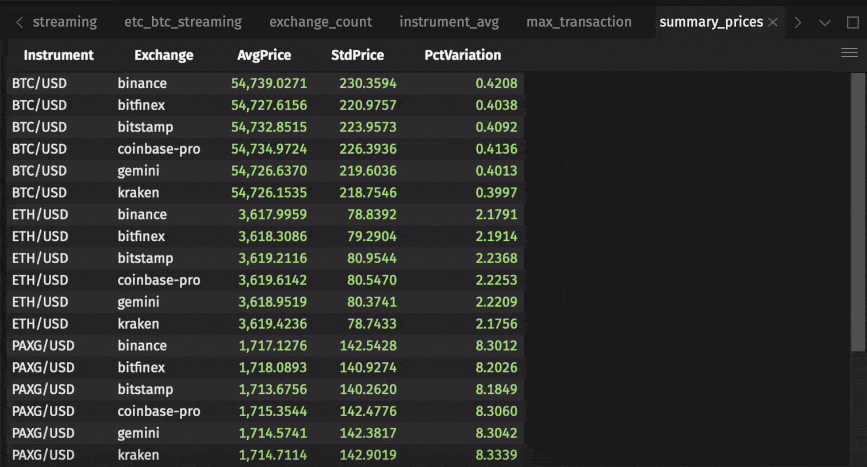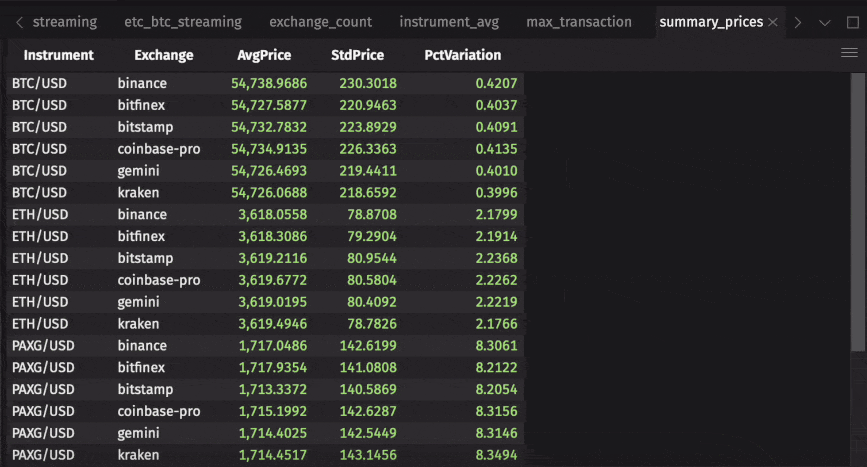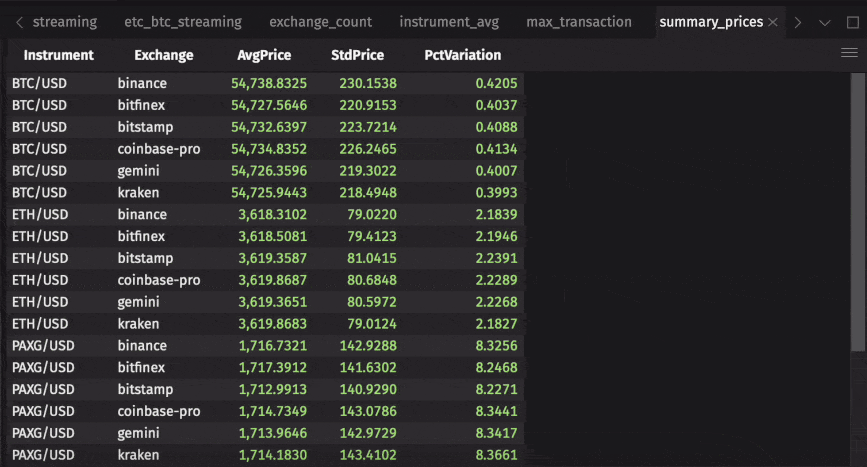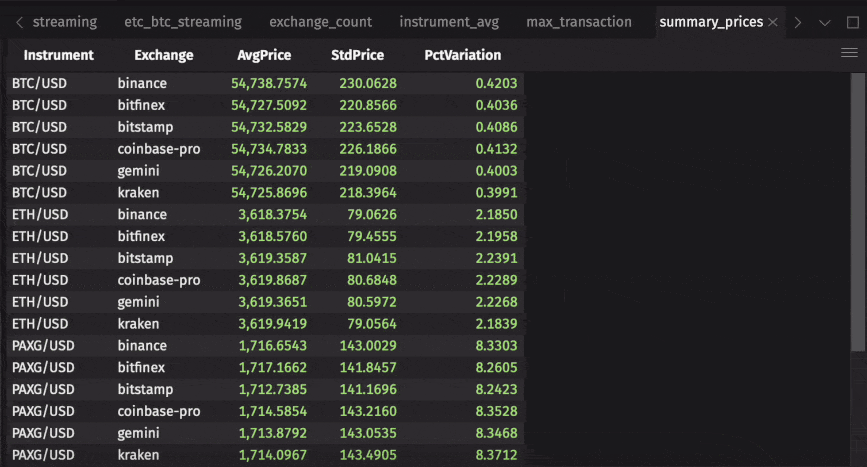
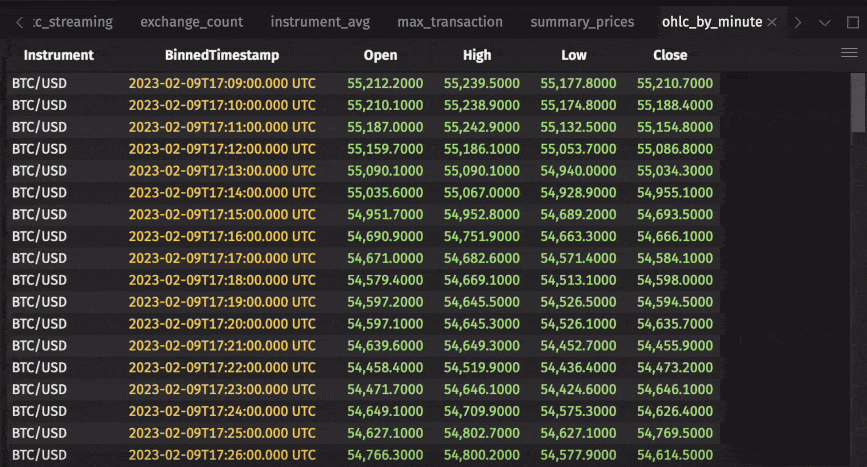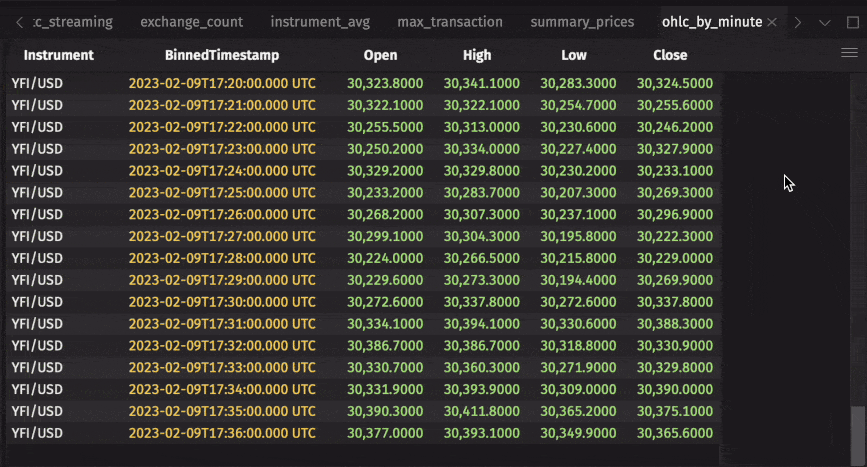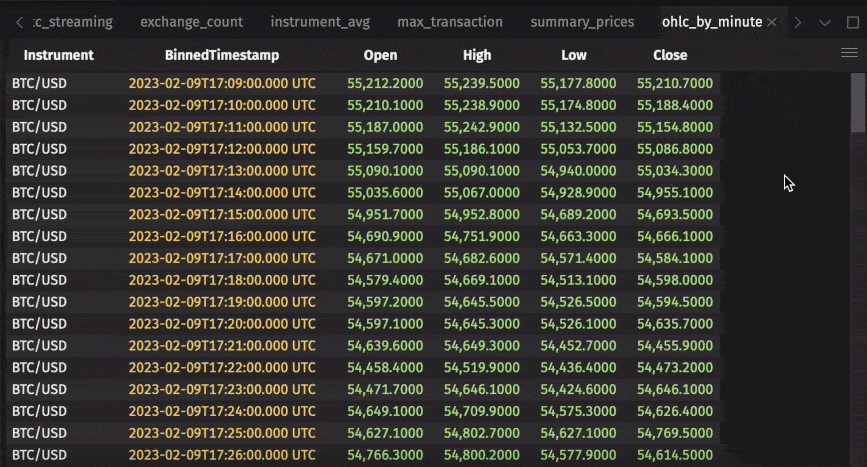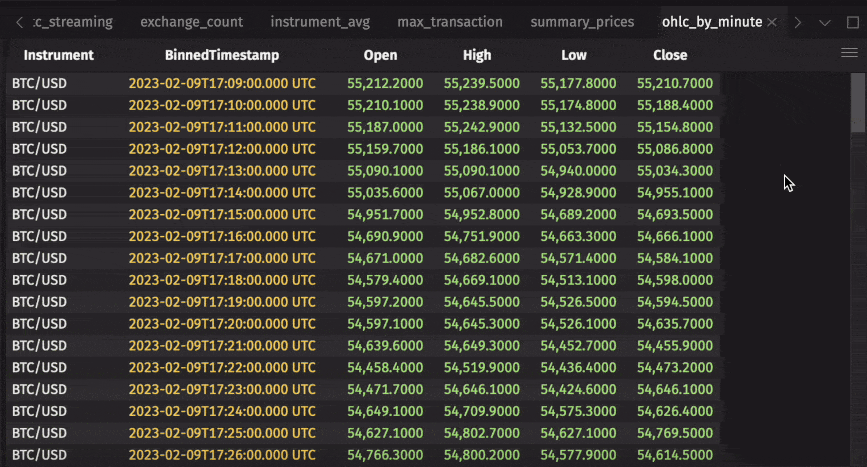
Finally, create a minute-by-minute Open-High-Low-Close table using lowerBin, one of Deephaven's built-in time functions, along with first, max_, min_, and last:
Window calculations
You may want to perform window-based calculations, compute moving or cumulative statistics, or look at pairwise differences. Deephaven's update_by table operation and the deephaven.updateby Python module are the right tools for the job.
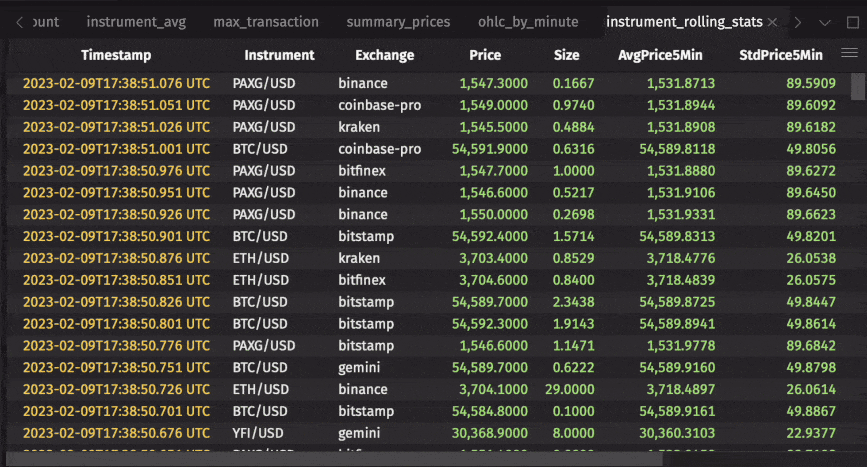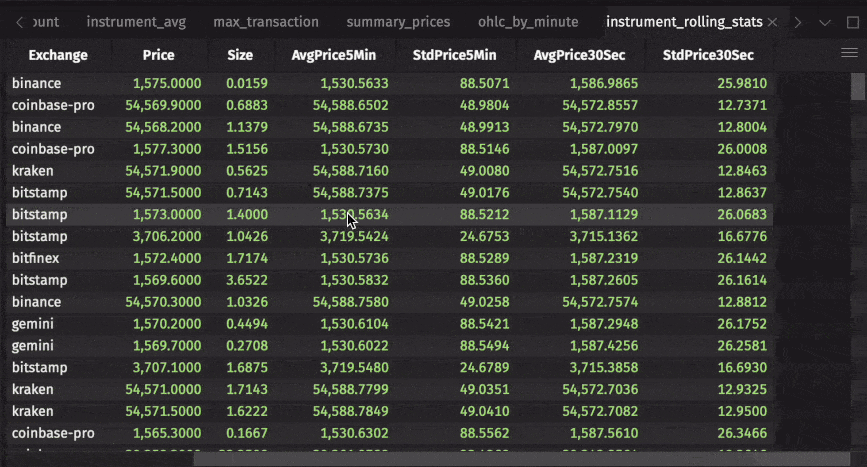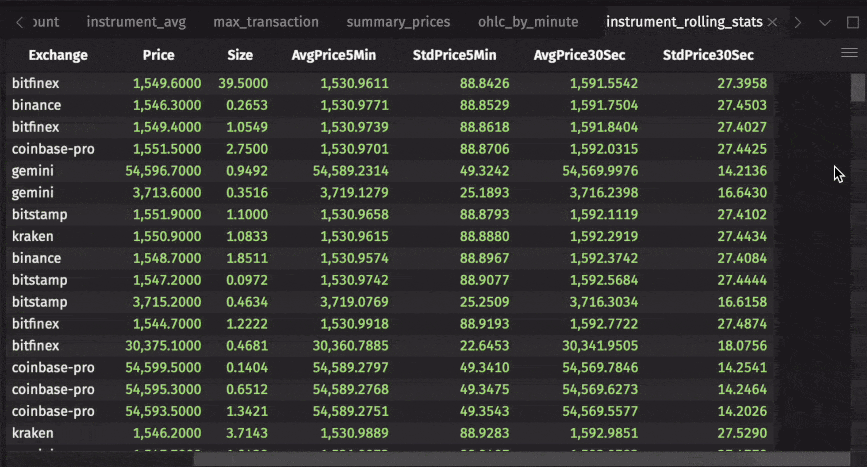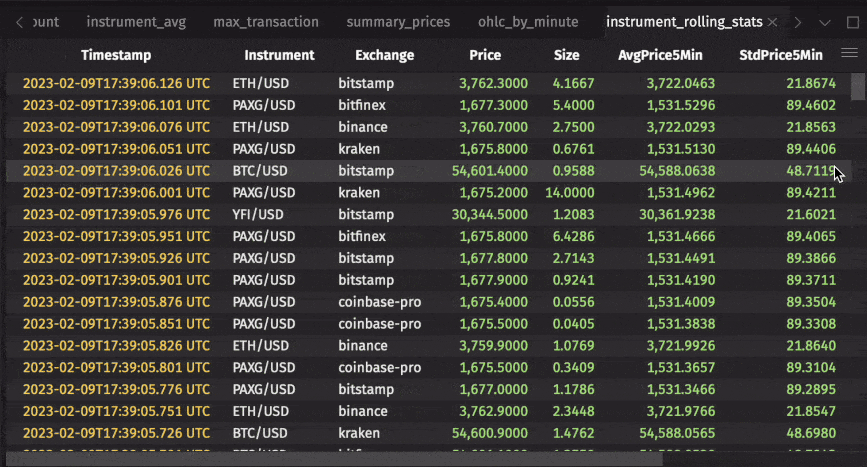
Compute the moving average and standard deviation of each instrument's price using rolling_avg_time and rolling_std_time:
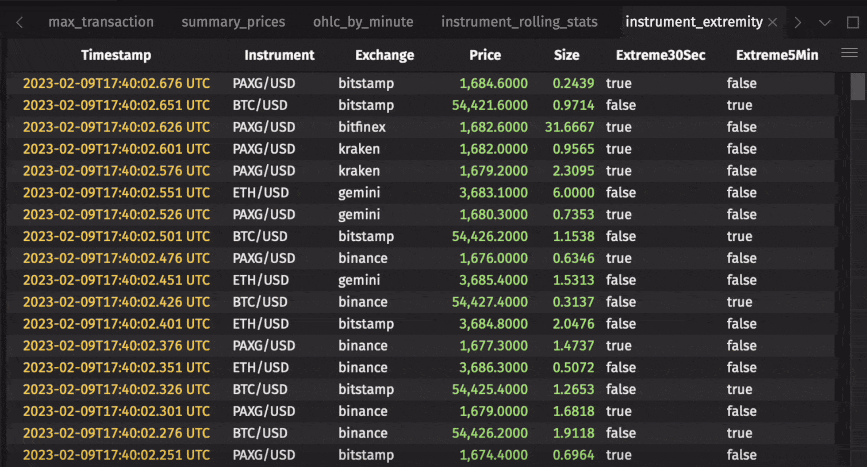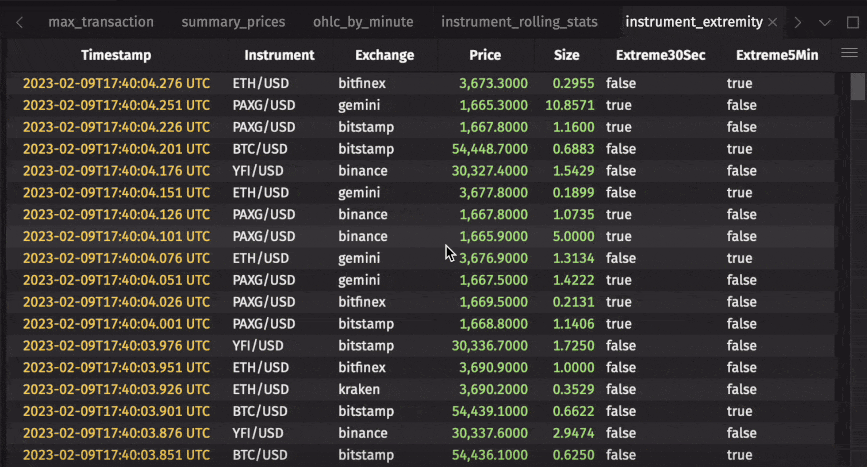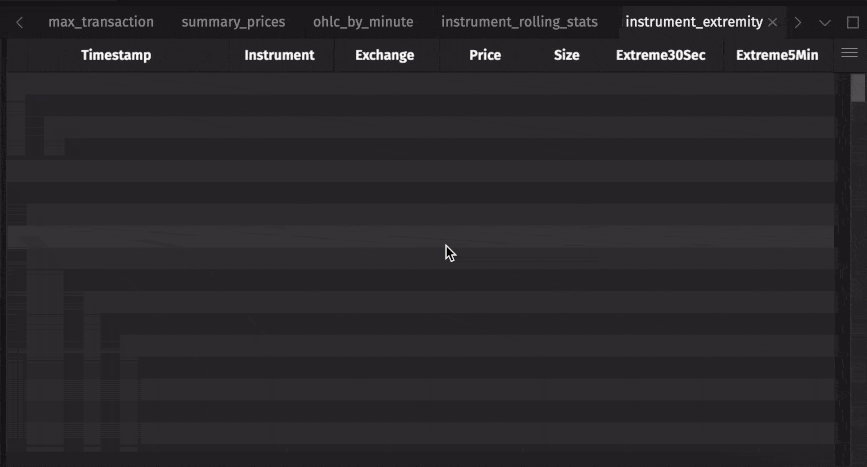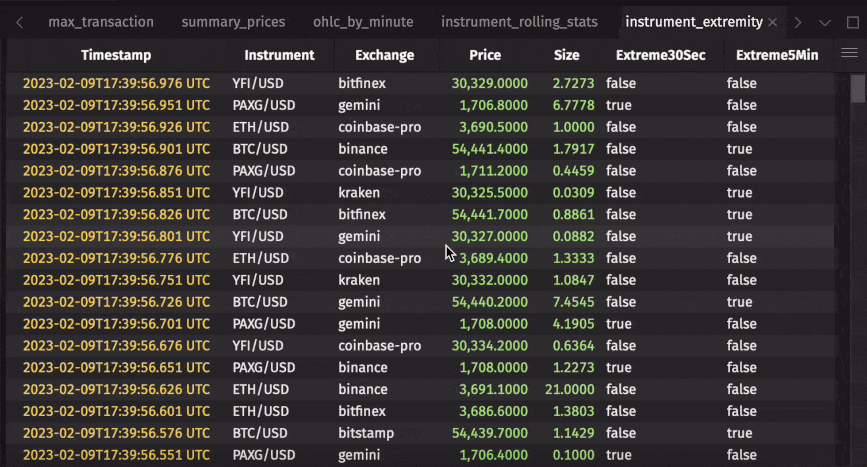
Use these statistics to find "extreme" instrument prices, where the price is more than 1.645 standard deviations above or below the rolling average for the window that ends at that row's timestamp:
There's a lot more to update_by. See the guide on rolling aggregations for more information.
Combine tables
Combining datasets can often yield powerful insights. Deephaven offers two primary ways to combine tables — the merge and join operations.
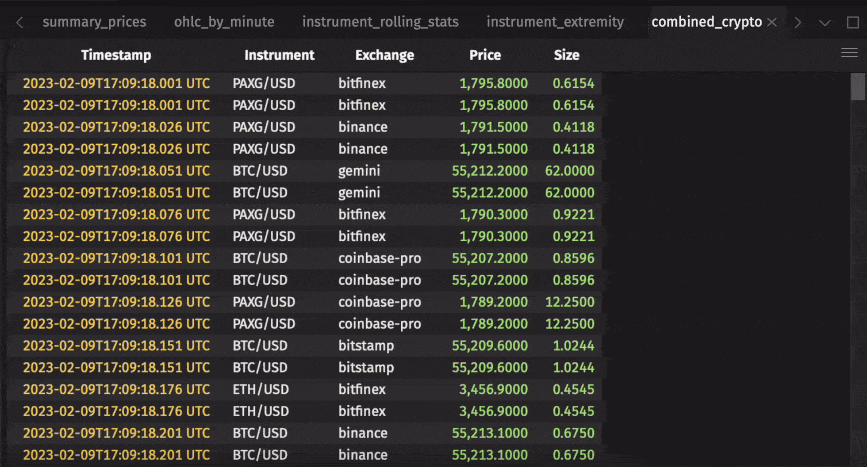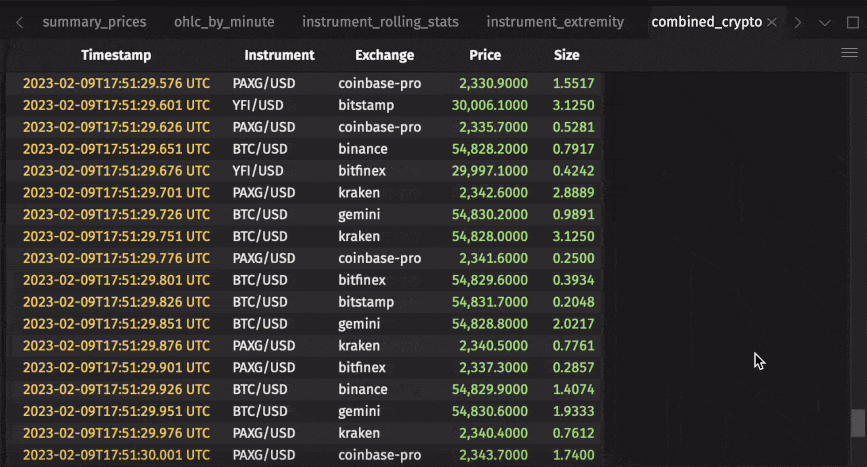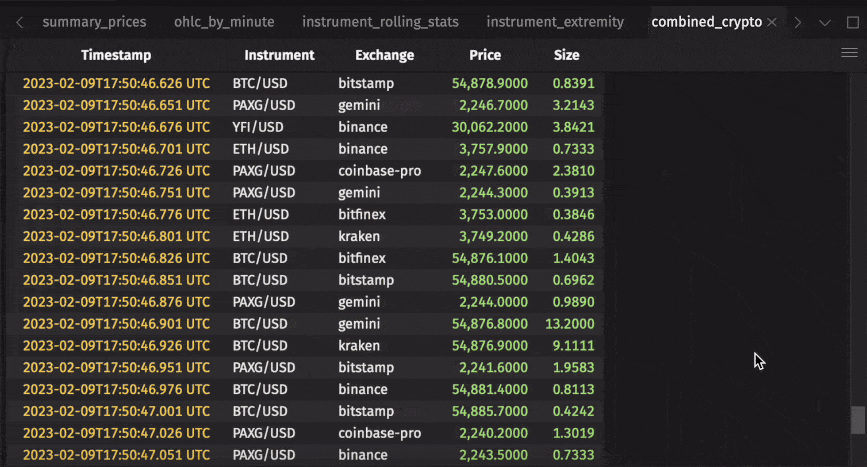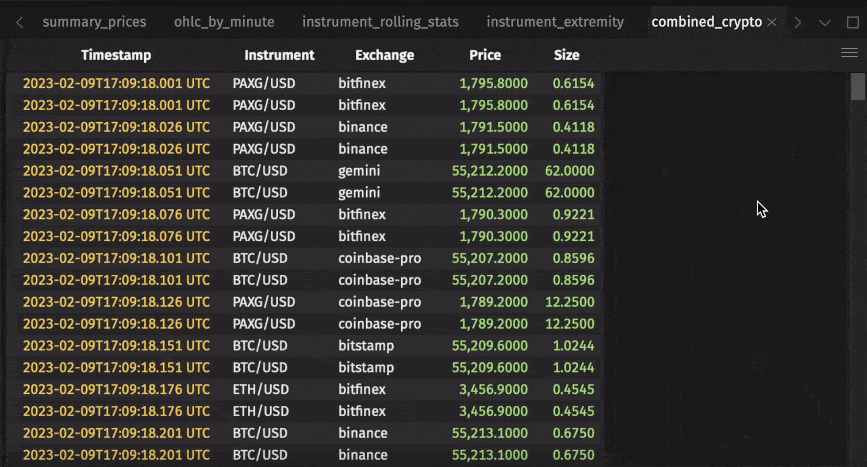
The merge operation stacks tables on top of one another. The tables must have the same columns with the same types. The tables you merge can be static, ticking, or a mix of both. For example, combine the static September 2021 trades with the ticking February 2023 replay:
The ubiquitous join operation combines tables based on columns that they have in common. Deephaven offers many variants of this operation, such as join, natural_join, and exact_join. The exact and relational joins guide covers the rest.
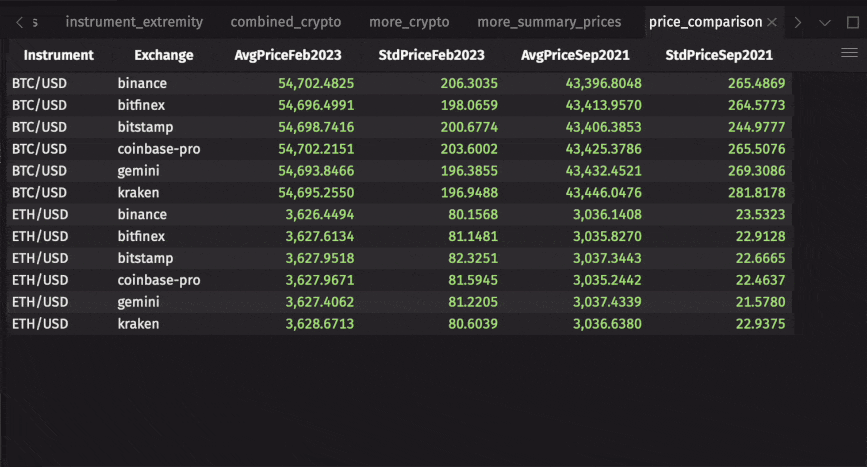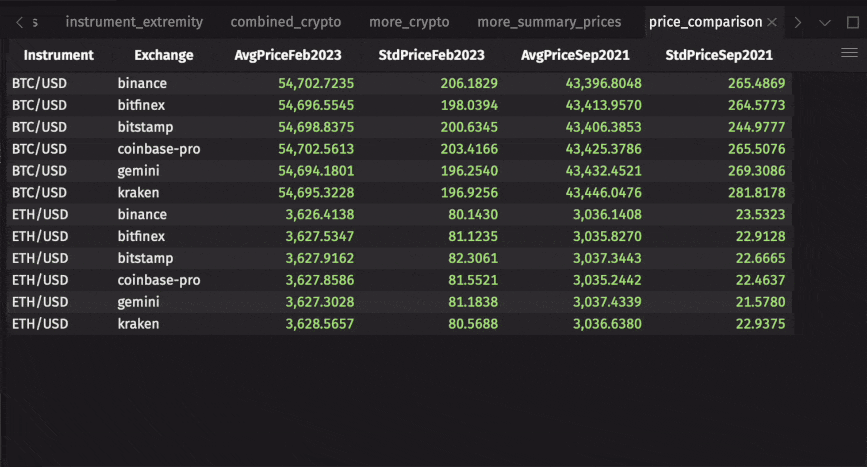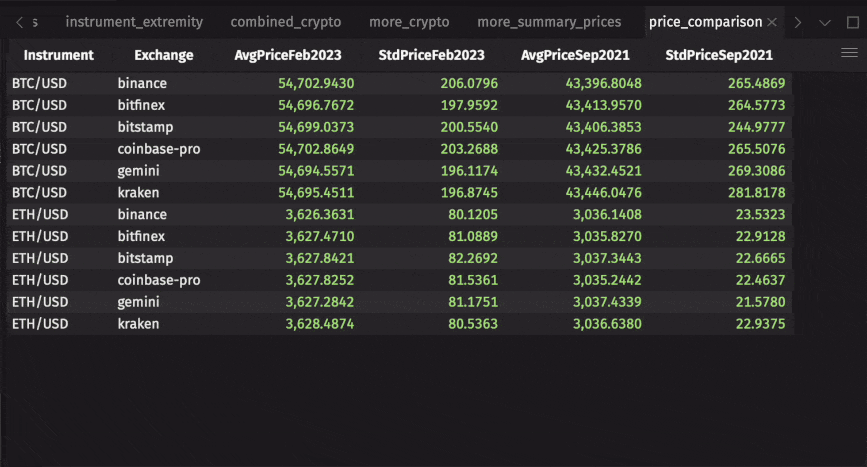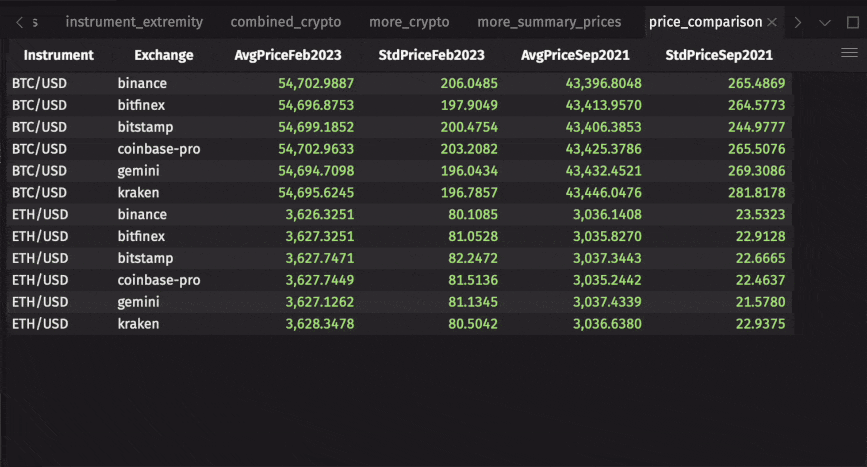
For example, summarize the older September 2021 trades in crypto_from_csv, the table you loaded at the start of this guide. Then, use join to combine that summary with the February 2023 summary_prices table from Aggregate data to compare February 2023 prices with September 2021 prices:
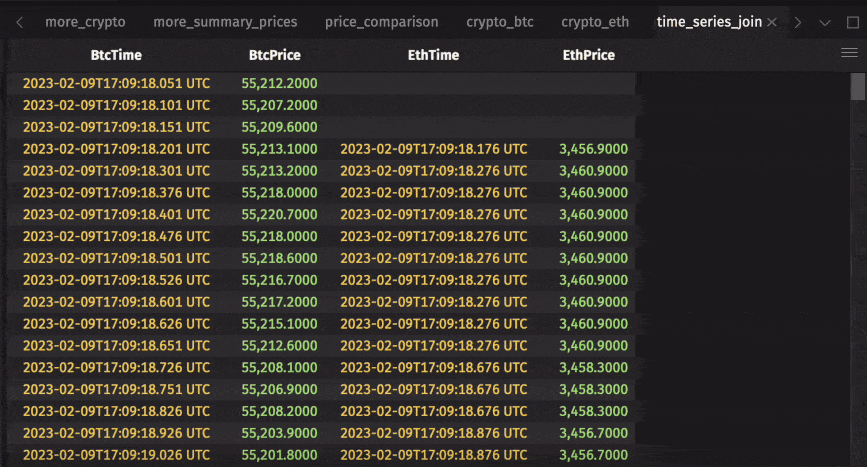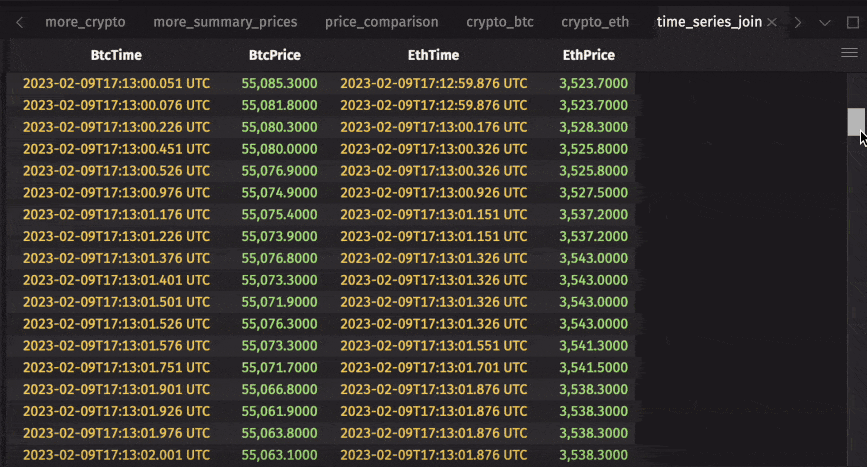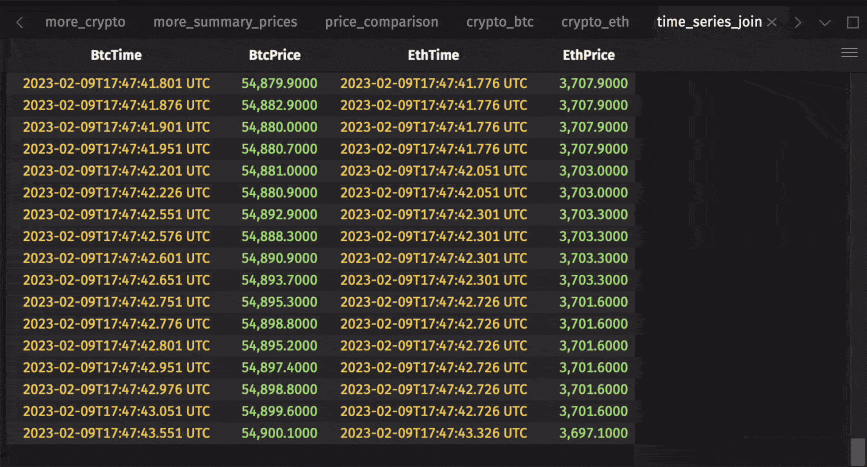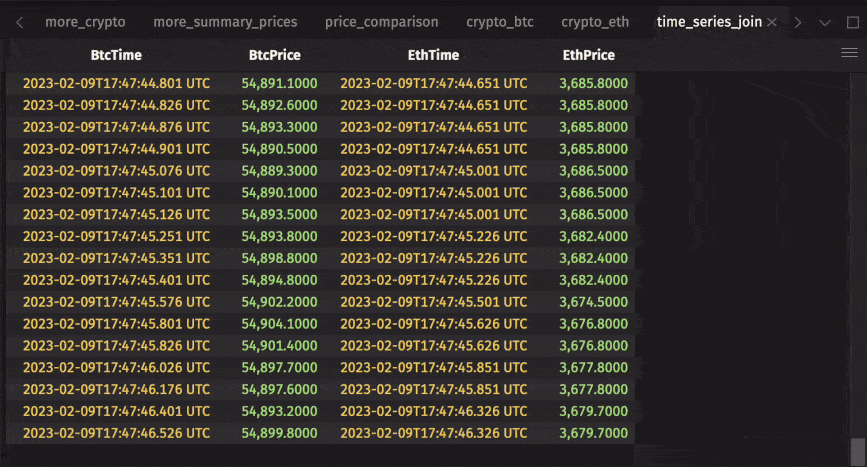
Many real-time data applications combine data based on timestamps. Traditional join operations often fail this task, as they require exact matches in both datasets. To remedy this, Deephaven provides time-series joins, such as aj and raj, that can join tables on timestamps with approximate matches.
The following example uses aj to find the Ethereum price at or immediately before the timestamp of each Bitcoin trade:
5. Plot data via query or the UI
Deephaven supports updating, real-time plots. Deephaven Express, a plotting plugin, is the recommended plotting library for most tasks. It builds real-time Plotly Express plots directly from Deephaven tables. See how to plot real-time data to compare Deephaven's plotting options.
The ghcr.io/deephaven/server Docker image includes Deephaven Express. If you installed with pip, you installed it along with Deephaven. If you run the production application, you installed it before starting the server.
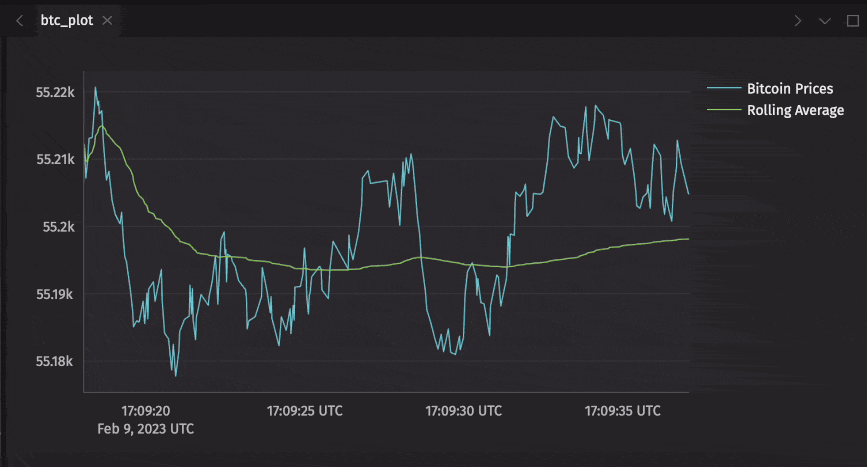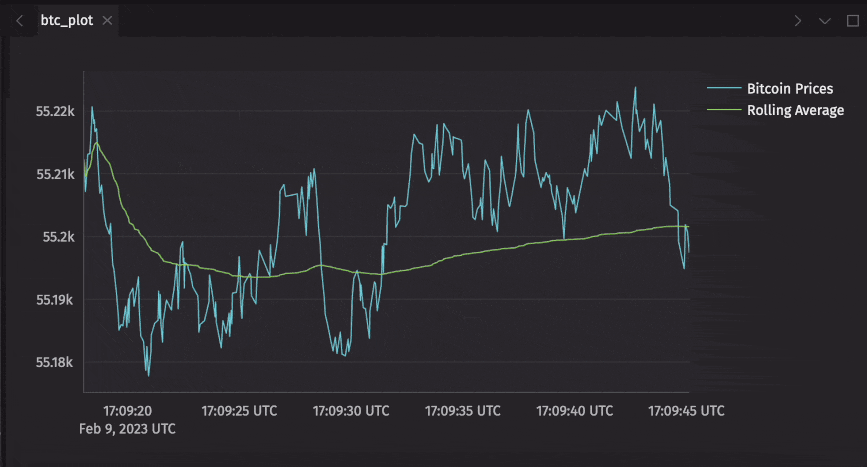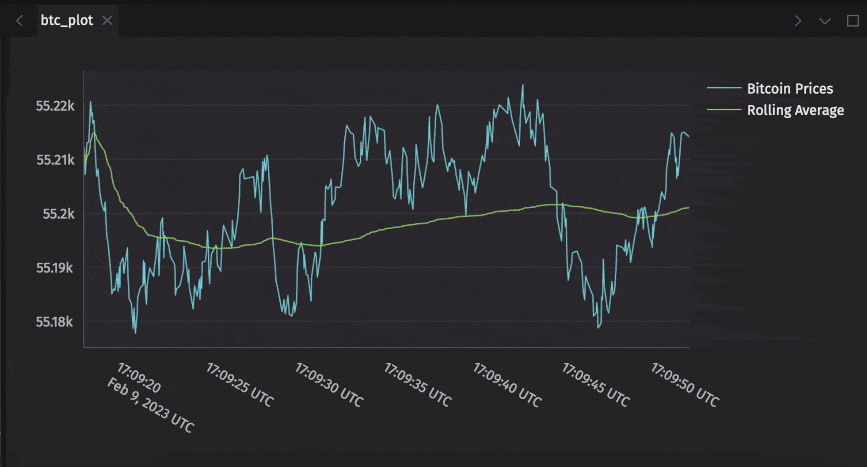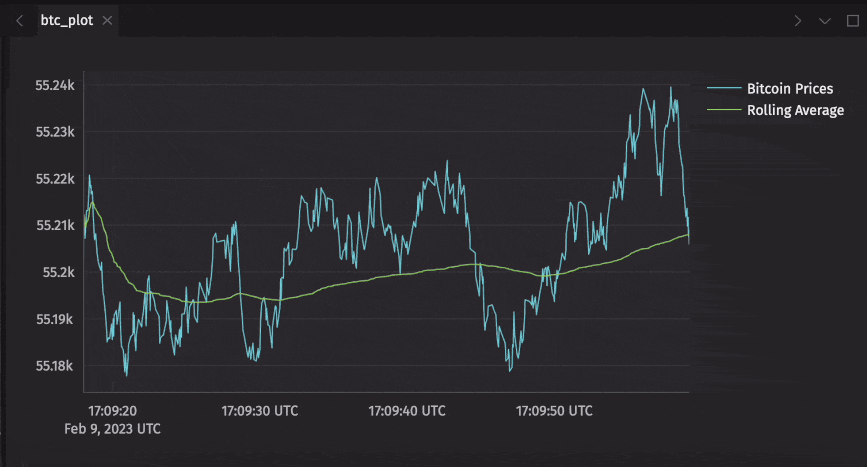
The following example uses Deephaven Express to plot the Bitcoin price and its 30-second rolling average:
To use the built-in plotting API instead, start with plot_xy.
You can also create plots from the web UI:
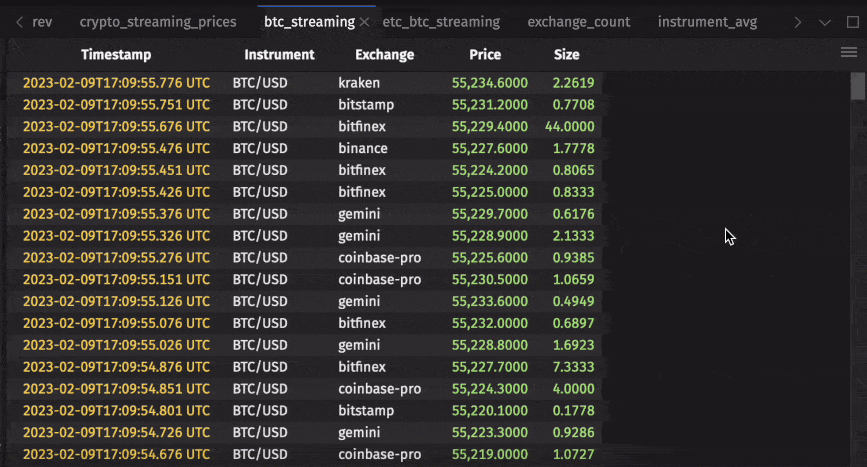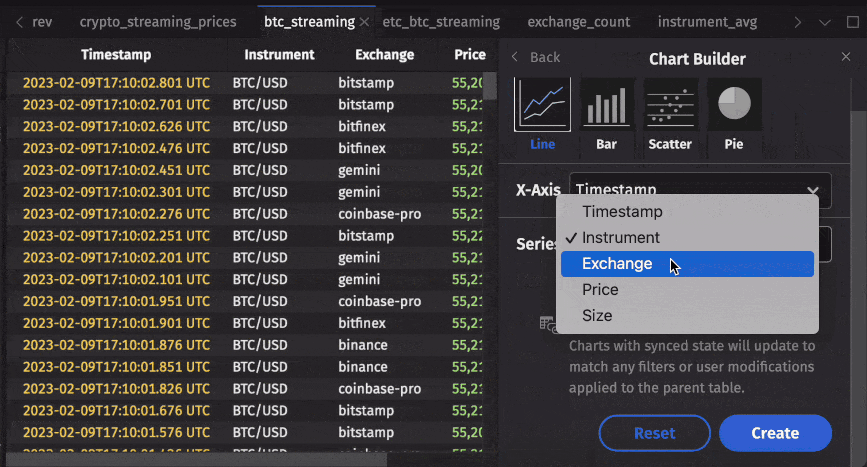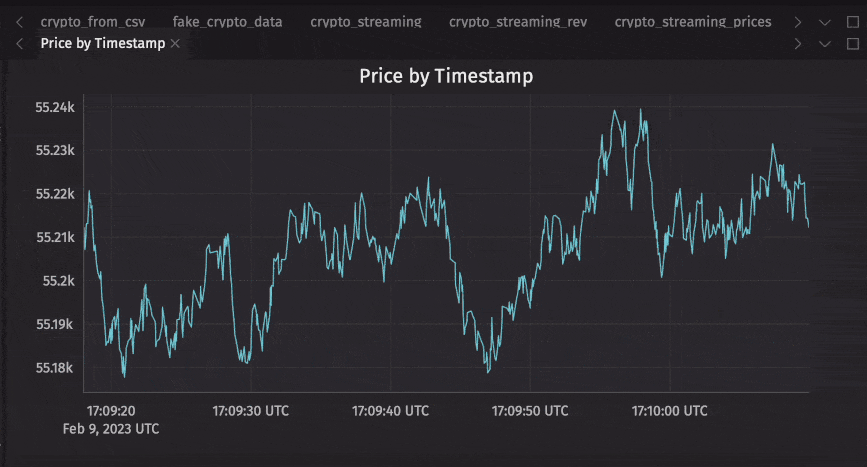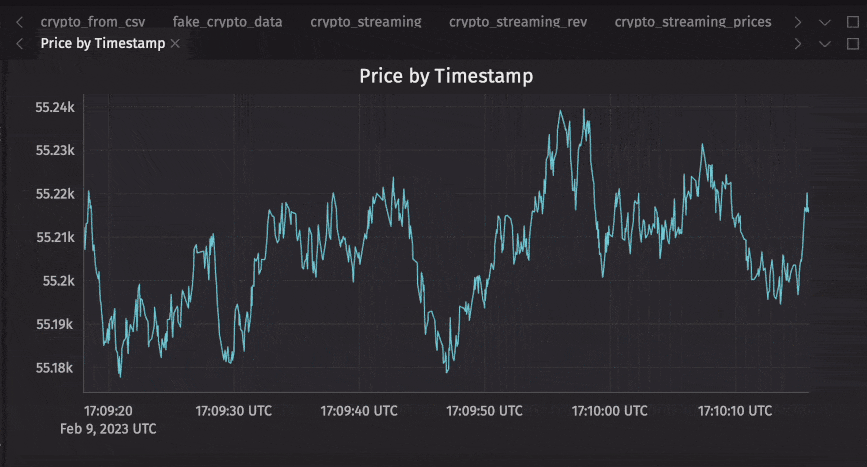
6. Export data
You can export your data from Deephaven to popular open file formats or to a pandas DataFrame.
The file examples below write to /data, the data directory in the Deephaven Docker image. If you started Deephaven with the Docker command above, the files appear in the data folder of the directory where you ran it. To mount other directories, see Add a second volume. If you installed Deephaven with pip or are running the production application, replace /data with a directory on your machine that you can write to.
To export a table to a CSV file, use the write_csv function with the table and the path where you want to save the file:
Similarly, use write from the deephaven.parquet module to export a Parquet file:
If a table is ticking, each exported file captures the table's state at the moment the script runs.
To create a static pandas DataFrame, use the to_pandas function:
7. What to do next
Now that you've imported data, created tables, and manipulated static and real-time data, we suggest heading to the Crash Course in Deephaven for a more in-depth introduction to Deephaven's design and APIs.
To go further with the topics in this guide, see: