Execute SQL queries in Deephaven
Structured Query Language (SQL) is one of the most popular languages for database management and access. You can use SQL with Deephaven in two ways. Use the deephaven.dbc Python package to run SQL against an external database and read the result into a Deephaven table. Use the experimental deephaven.experimental.sql module to run SQL against Deephaven tables in your session.
This guide shows you how to do both. SQL queries against Deephaven tables work on ticking tables too, and their results update as the source tables change.
Query an external database
deephaven.dbc provides three functions:
read_sql- Executes a provided SQL query via a supported driver.
odbc.read_cursor- Reads query results from a turbodbc cursor over the Open Database Connectivity (ODBC) interface.
adbc.read_cursor- Reads query results from a cursor over the Apache Arrow Database Connectivity (ADBC) interface.
Choose the right function
Consider the following factors when you choose among these three functions.
High-level vs low-level
read_sql is a high-level function for executing a query against a SQL database. Pass the SQL query as query. Pass a connection string or an existing turbodbc or ADBC Connection object as conn. It returns a static table that holds the query's result.
odbc.read_cursor and adbc.read_cursor are lower-level functions because they read from a cursor that has already executed a query. You open the cursor and execute the query yourself, then pass the cursor to the function. Use one of these when you need control over the cursor itself, for example to execute a parameterized query.
ODBC vs ADBC
The two lower-level options can both achieve the same results. When choosing one or the other, consider:
- ODBC (
odbc.read_cursor) is a well-known specification that works with relational databases that have an ODBC driver. - ADBC (
adbc.read_cursor) fetches data in Arrow format from databases that support Arrow natively, such as databases that serve the Arrow Flight SQL protocol. It also works with other databases that have an ADBC driver, such as PostgreSQL and SQLite.
Supported drivers and required packages
read_sql can use one of three supported drivers, which you choose with its driver argument. To use a driver, install the corresponding packages:
"connectorx"(ConnectorX, the default)"odbc"(ODBC)"adbc"(ADBC)- adbc-driver-manager
- adbc-driver-flightsql for Arrow Flight SQL
- adbc-driver-postgresql for PostgreSQL
- adbc-driver-sqlite for SQLite
If you pass a turbodbc or ADBC Connection object instead of a connection string, read_sql ignores driver.
odbc.read_cursor and adbc.read_cursor need the same packages as the "odbc" and "adbc" drivers, respectively.
For ODBC, you need a turbodbc build with Apache Arrow support, an ODBC driver manager, and your database's ODBC driver.
For ADBC, you always need adbc-driver-manager, along with the driver package for your database. With a connection string, read_sql(driver="adbc") supports only two databases:
- PostgreSQL, when the connection string is a
postgresql://URI. - SQLite, when the connection string is empty.
For other ADBC drivers, such as Flight SQL, pass an ADBC Connection object as conn, or use adbc.read_cursor.
Execute a query
With the necessary packages installed, you can create a table from a SQL query with read_sql, odbc.read_cursor, or adbc.read_cursor. Each example below pulls from a PostgreSQL database.
Tip
It's best practice not to store credentials in plaintext. The following examples read the username, password, host, and port of the PostgreSQL database from environment variables.
read_sql
odbc.read_cursor
Before you run this example, install the PostgreSQL ODBC driver and register it with the ODBC driver manager. The Driver value in the connection string must match the registered driver name (PostgreSQL Unicode in this example). turbodbc.connect takes an ODBC connection string rather than a PostgreSQL URI.
adbc.read_cursor
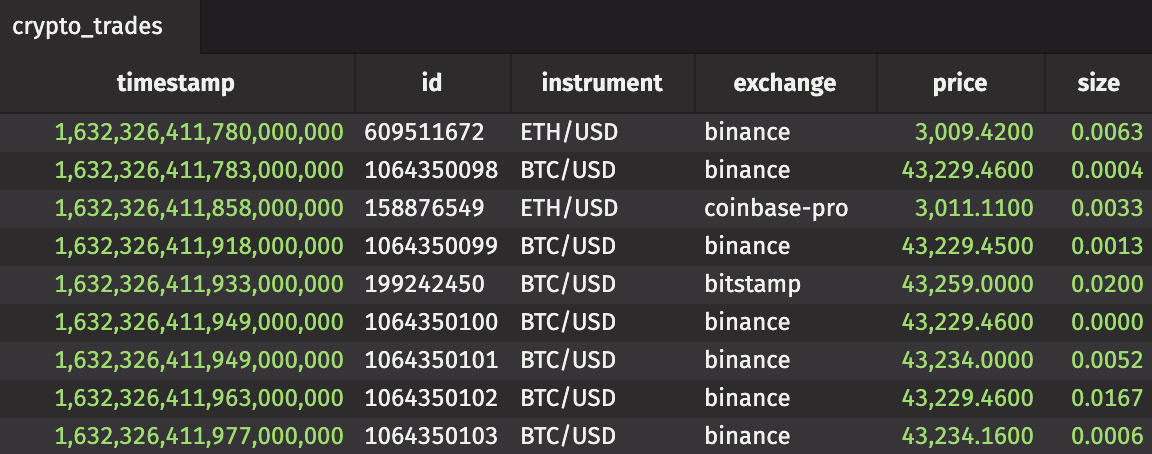
All three examples read the same rows into crypto_trades, although column types can differ between drivers. PostgreSQL converts unquoted identifiers such as Timestamp to lowercase, so the column names in the result are lowercase:
Query Deephaven tables with SQL
The deephaven.experimental.sql module runs SQL queries against Deephaven tables instead of an external database. Its evaluate function runs a query that refers to tables by their Python variable names in the calling scope and returns a new Deephaven table. If the source tables are ticking, so is the result.
Note
SQL support for Deephaven tables is experimental. The deephaven.experimental.sql API and the set of supported SQL features are subject to change.
Query a ticking table
Let's run SQL against a ticking table. The example below creates a time table that adds a row every second, then counts its rows by the value of X. The result updates each time a new row arrives:
Validate a query without executing it
To parse and validate a query without executing it, pass dry_run=True to evaluate. Instead of a table, evaluate then returns a Java TableSpec object that describes the query plan. It also writes the plan to the server log in Graphviz format. The example below prints that plan to the console with Graphviz.toDot:
Supported SQL features
Table and column names are case-sensitive and must match the Deephaven names exactly, so SELECT x FROM source doesn't find a column named X. Use double quotes to reference a name that isn't a valid SQL identifier.
Deephaven's SQL implementation supports:
SELECTstatements with column selection and aliasing.SELECT DISTINCTfor removing duplicate rows.WHEREclauses for filtering.- Inner joins with
JOINorINNER JOIN. GROUP BYwith aggregate functions:SUM,AVG,MIN,MAX,STDDEV,VARIANCE,ANY_VALUE,COUNT(*),COUNT(DISTINCT col), andAPPROX_COUNT_DISTINCT.DISTINCTworks only insideCOUNT.- Unlike standard SQL,
COUNT(DISTINCT col)counts null as a distinct value. APPROX_COUNT_DISTINCTreturns the same exact count asCOUNT(DISTINCT col).
ORDER BYfor sorting.LIMITfor restricting the number of rows.UNIONandUNION ALLfor combining the rows of queries with matching columns.- Arithmetic operators (
+,-,*,/).- Unlike standard SQL,
/on two integers returns a floating-point result.
- Unlike standard SQL,
- Comparison and logical operators (
=,<>,<,<=,>,>=,AND,OR,NOT,IS NULL,IS NOT NULL).- Unlike standard SQL,
=and<>treat null as an ordinary value, so two nulls are equal andX <> 1also matches rows whereXis null. UseIS NULLandIS NOT NULLto test for null values.
- Unlike standard SQL,
CASTto numeric types (TINYINT,SMALLINT,INTEGER,BIGINT,REAL,FLOAT, andDOUBLE).- Common math functions such as
ABS,SQRT,POWER,ROUND(one-argument form only),FLOOR, andCEIL.
To see how integer division differs from standard SQL, divide an int column by 2. The Half column in the result is a double, so 3 / 2 is 1.5 rather than 1:
Deephaven doesn't support every SQL feature. For example, it doesn't support OFFSET, the remainder operator %, COUNT(col), CAST to any other type (such as DECIMAL or VARCHAR), string functions and operators such as LIKE, or ORDER BY with ASC NULLS LAST or DESC NULLS FIRST. If a query uses one of these, evaluate raises a DHError.
Warning
Deephaven runs outer joins (LEFT, RIGHT, and FULL) as inner joins and does not raise an error, so the result drops unmatched rows.