Use deephaven.learn for AI/ML applications
This guide shows how to perform calculations in Python with Deephaven tables through the deephaven.learn package. It walks through each argument of the learn function with a toy example, puts them together, runs the result on a ticking table, and then applies the same steps to scikit-learn and TensorFlow models.
Data scientists and AI engineers spend a lot of their time transforming and cleaning data, and relatively little time doing the fun analytical work. Deephaven queries make that data preparation easier. The learn package then runs your model on the prepared data. It hands the data to your model in batches and writes the results back into a table.
Your model can use any Python objects or libraries, so working Python code that doesn't use Deephaven tables extends to Deephaven by wrapping it in a model function. Libraries that run on specialized hardware, such as GPUs, TPUs, or FPGAs, work without changes to the library code. The same model produces static predictions on a static table and real-time predictions on a ticking table.
The gather-compute-scatter paradigm
Deephaven's learn package follows a gather-compute-scatter paradigm with three building blocks:
- Gather data from specified columns and rows of a Deephaven table into the appropriate Python object.
- Compute solutions using the gathered data.
- Scatter the solutions back into new columns of a Deephaven table.
Data science libraries typically interact with input and output data stored in Python objects. Common examples of these objects include:
- Lists
- NumPy
ndarrays - pandas DataFrames
- PyTorch tensors
- TensorFlow tensors
Artificial intelligence and machine learning (AI/ML) applications typically gather data into arrays or tensors. Calculations then use that data either to optimize the model or to generate predictions from it. The application scatters predictions and other output values into columns of the output table.
Usage and syntax
A learn function call looks like this:
The sections below describe each of the five arguments, in the order you usually decide on them when constructing a solution to a data science or AI problem:
- Compute: define the model that calculates solutions from the input data (
model_func). - Input table: choose the table that holds the data (
table). - Batch size: choose how many rows to process at once (
batch_size). - Gather: determine how input data is best represented for your chosen model (
inputs). - Scatter: determine what the output of the model looks like (
outputs).
Compute
Whatever model you choose, you implement it as a Python function. In this step, you apply calculations to some input data.
learn calls the model function once per batch of rows:
- The function receives one argument for each input you define in the Gather step, in the same order.
learnpasses the function's return value to each scatter function in the Scatter step.
You don't need to decide every detail and parameter of the model yet. You do need to know:
- The number of input values the model needs to work.
- The overarching class of model to implement.
- The computational constraints on the model.
- The number of output values the model generates.
You typically train an AI model, validate it on held-out data, and test it on new data in separate steps. Each step can be its own learn call with its own model function, as the examples below show for training and prediction.
For a toy example, this guide constructs a "model" that sums values together. Unlike a real AI model, this needs no training or testing. Regardless, this toy example illustrates basic usage of deephaven.learn.
The model receives the gathered input as its features parameter. features is a two-dimensional NumPy array with one row for each table row in the batch and one column for each input column. The Gather section shows the gather function that builds it. The toy model sums the values in each row, so it passes axis=1 to np.sum.
Input table
Real-world AI applications use datasets drawn from many sources. Sensors, observations, and experimental results cover only a small portion of the data sources that AI models use. In a real application, a Deephaven table holds this data.
You call learn the same way on a static table and on a ticking table, one whose rows change as new data arrives. On a ticking table, learn batches and processes only the rows added during each update cycle, the periodic step in which Deephaven applies new data to ticking tables. The model therefore computes predictions only on new input data, which minimizes the computational power that streaming predictions need.
Because learn identifies rows by their row keys, it raises an error when you call it on a ticking table, unless the table is one of these types:
- Add-only, which includes append-only tables.
- Blink.
For other ticking tables, such as ones that modify or remove rows, use one of the approaches in the AI/ML workflows guide instead.
For the toy problem, create a static table called source using empty_table and fill it with data using update. source serves as the input table.
Later on, you pass source to learn as the table that contains the model's input data.
Batch size
The batch size is the maximum number of rows that each call to the model function receives. A batch can hold fewer rows than batch_size. For instance, source contains 100 rows. With a batch size of 40, learn processes three batches: the first 40 rows, the next 40, and the last 20.
batch_size is required. learn raises an error if you don't set it.
For a static table, learn splits all of the table's rows into batches. For a ticking table, it batches only the rows added in each update cycle, as Input table describes.
batch_size is separate from any batch size your ML library uses internally. For example, Keras model.fit still splits the rows it receives into its own mini-batches.
Smaller batches use less memory per call. Larger batches make fewer calls and let vectorized libraries work on more rows at once. Choose the batch size based on the largest memory footprint your problem can handle.
For training, many fitting functions, such as scikit-learn's LinearRegression.fit, replace the previous fit each time they are called. Pass all training rows in one batch, as the examples do by setting batch_size to the table's size.
In the toy problem, the batch size is the number of rows in source, so all 100 rows are processed in one batch.
Gather
In the gather step of learn, a gather function maps data from a Deephaven table to a Python object that suits the compute model. You specify the columns in the input table to gather data from, and learn supplies the rows in each batch.
The learn.gather module gathers data. Its built-in function table_to_numpy_2d gathers table data into a two-dimensional NumPy ndarray.
learn calls the gather function once per batch with two arguments: the set of rows in the batch and the column sources for the gathered columns. A column source is the object that holds a column's data. A gather function usually passes both straight to table_to_numpy_2d.
table_to_numpy_2d takes four parameters:
row_set: The rows to copy into thendarray.col_set: The column sources to copy into thendarray.order: Agather.MemoryLayoutvalue, eitherROW_MAJOR(the default) orCOLUMN_MAJOR.CandFORTRANare aliases forROW_MAJORandCOLUMN_MAJOR, respectively.- The returned array has one row per table row and one column per gathered column for either value, so most models can leave the default.
ordersets the memory layout of the returned array.ROW_MAJORreturns a C-contiguous array, andCOLUMN_MAJORreturns a Fortran-contiguous one.
np_type: The NumPydtypeof all values in the outputndarray.- Supported types are
np.byte,np.short,np.intc,np.int_,np.single, andnp.double. - The Python types
intandfloatconvert tonp.intcandnp.double, respectively. - The default is
np.intc, so passnp_typeexplicitly for floating-point data.
- Supported types are
The gathered columns must already hold the Java type that matches np_type, such as double columns for np.double or int columns for np.intc. Cast any other column with update before calling learn, as the scikit-learn example does.
For the toy problem, the model needs all of the data from input columns A and B in the source table. Thus, the gather step takes data from two columns and maps it to an ndarray. The resulting ndarray has one row for each row in the batch and one column for each gathered column. In the toy problem, the batch holds all 100 rows of source, so the array has 100 rows and 2 columns.
The toy gather function uses the default order and gathers the values as doubles:
An input pairs the column names to gather with the gather function. learn.Input takes a column name or a list of column names, followed by the gather function. Pass the inputs to learn as a list:
Note
If you only want to gather one column, gather.table_to_numpy_2d creates a two-dimensional array with a single column. You can convert it to a one-dimensional array with np.squeeze.
Scatter
The scatter step of learn runs after the model processes the input data. It writes the model's output back into a Deephaven table. You specify the output columns and a scatter function that maps the output data to table cells.
The toy example has two input columns and a function that sums them on a per-row basis. Its output is a single column, C, that holds each sum.
The scatter function receives the model's result and the index of a row within its batch. The toy scatter function returns the sum at that index, and learn writes that value to the output table.
An output pairs a new column name with the scatter function and the column's type. learn.Output takes the output column name, the scatter function, and the type. Pass the outputs to learn as a list:
Specifying "double" at the end tells learn to cast the output values as doubles in the result table. The type is a string that names a Java type, such as one of the Java primitive types ("int", "long", "double", and so on).
If the model function produces no output, such as one that only trains a model, pass outputs=None, as the training steps in the examples do.
Putting it all together
You can combine everything covered so far to make a program that uses learn to sum two columns in one table and return the result in another.
This is overkill for adding two columns. One update call does the same thing: source.update(formulas=["C = A + B"]). However, these steps generalize to AI code, where the added complexity is small relative to the problem itself.
Predict on a ticking table
The same learn call works on live data. The example below reuses the functions from the previous block. Its input comes from time_table, which creates a time table that adds a row every second. Because a time table is append-only, learn accepts it.
On each update cycle, learn gathers only the rows added since the previous cycle, runs the model on them, and fills in their C values. Rows that are already in result_live keep their values.
Examples
This section uses these AI packages:
These packages are not in the base server Docker image. To get them, either run an image that includes them, such as server-sklearn, server-tensorflow, or server-all-ai, or install them as described in Install and use Python packages.
The scikit-learn and TensorFlow guides cover each package both with and without deephaven.learn.
Predict insurance charges using scikit-learn and Deephaven
This first example uses a linear regression model from scikit-learn. This model predicts each customer's insurance charges from demographic and health factors such as age, BMI, and smoking status.
The code uses the insurance dataset from Deephaven's Examples repository, which was originally published on Kaggle.
The example below:
- Reads the insurance dataset from a CSV file with
read_csv. - Converts the string columns to numeric category codes with
group_by,update, andungroup. - Casts the integer columns to doubles.
- Constructs a linear regression model and defines model functions that fit it and use it to predict.
- Defines the gather and scatter functions.
- Uses
learnto fit the model to the data, with no outputs. - Uses
learnagain to apply the fitted model and write the predictions to a new column.
Each row of predicted_skl keeps its actual expenses next to the model's prediction in PredictedCharges.
Predict fraudulent credit card charges using TensorFlow and Deephaven
This second example uses TensorFlow to predict whether credit card purchases are fraudulent.
The code uses the credit card fraud dataset from Deephaven's Examples repository, which was originally published on Kaggle.
The dataset contains 48 hours' worth of credit card purchases. Out of 284,807 purchases, 492 are fraudulent. Principal component analysis (PCA) anonymizes 28 of the numeric columns, V1 through V28, which the model uses as its inputs. The low rate of fraudulent purchases (0.173%) makes this an outlier detection problem.
The code below:
- Reads the CSV file into memory with
read_csv. - Casts the
Classcolumn toshortso it can be gathered withnp.short. - Splits the table into training and testing sets with
where. - Constructs the model and defines model functions that train it and use it to predict.
- Defines the gather and scatter functions.
- Trains the model on the training data, with no outputs.
- Applies the trained model to the training data.
- Applies the trained model to the testing data.
- Keeps the columns of interest with
view.
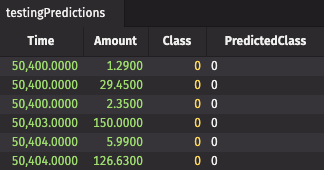
PredictedClass holds the model's prediction (0 for a valid purchase, 1 for fraud) next to the true Class for each testing purchase.
Related documentation
- Deephaven's table types
- Incremental update model
- AI/ML workflows
- Install and run with Docker
- Install and use Python packages
- Use PyTorch in Deephaven
- Use scikit-learn in Deephaven
- Use TensorFlow in Deephaven
- Create a time table
- How do row keys and positional indices behave during table operations?
empty_tablegroup_byread_csvtime_tableungroupupdateviewwheredeephaven.learnPydocdeephaven.learn.gatherPydoc