consume
consume reads a Kafka stream into an in-memory table.
Syntax
Parameters
| Parameter | Type | Description |
|---|
| kafka_config | dict | Configuration for the associated Kafka consumer and the resulting table. Once the table-specific properties are stripped, the remaining one is used to call the constructor of org.apache.kafka.clients.consumer.KafkaConsumer; pass any KafkaConsumer-specific desired configuration here. |
|---|
| topic | str | The Kafka topic name. |
|---|
| partitions optional | Sequence[int] | A sequence of partition numbers to subscribe to. The default, None, subscribes to all partitions. For example, partitions=[1, 3, 5] listens only to partitions 1, 3, and 5. |
|---|
| offsets optional | dict[int, int] |
ALL_PARTITIONS_DONT_SEEK (default) - Start each partition without seeking, so Kafka picks the starting offset: the consumer group's committed offset if group.id is set and the group has one, otherwise Kafka's auto.offset.reset setting (default latest, the end of the partition).ALL_PARTITIONS_SEEK_TO_END - Go to the newest available message for every partition.ALL_PARTITIONS_SEEK_TO_BEGINNING - Go to the oldest available message for every partition.{ _number_ : _offset_, ... } Map partition numbers to numeric offsets or one of the constants DONT_SEEK, SEEK_TO_END, SEEK_TO_BEGINNING.
- For example,
{ 1 : SEEK_TO_END, 3 : SEEK_TO_BEGINNING, 5 : 27 } means:
- Start from the last message sent in partition 1.
- Go to the oldest available message in partition 3.
- Start with offset 27 in partition 5.
|
|---|
| key_spec optional | KeyValueSpec | Specifies how to map the Key field in Kafka messages to table column(s). Any of the following found in deephaven.stream.kafka.consumer can be used:
simple_spec - Creates a spec that defines how a single column receives a key or value field from a Kafka message when consuming a Kafka stream.avro_spec - Creates a spec that defines how to use an Avro schema when consuming a Kafka stream.json_spec - Creates a spec for how to use JSON data when consuming a Kafka stream.protobuf_spec - Creates a spec for parsing a Kafka protobuf stream. Uses the schema, schema_version, and schema_message_name to fetch the schema from the schema registry, or uses message_class to get the schema from the classpath.object_processor_spec - Creates a Kafka key-value spec implementation from a named object processor provider.KeyValueSpec.IGNORE - Ignore the field in the Kafka event.KeyValueSpec.FROM_PROPERTIES (default) - Creates a single key column. The column name comes from the deephaven.key.column.name entry in kafka_config and defaults to KafkaKey if that entry is not set. The column type comes from the deephaven.key.column.type entry or, if that entry is not set, from a recognized key.deserializer entry. If neither entry is set, consume raises an error. |
|---|
| value_spec optional | KeyValueSpec | Specifies how to map the Value field in Kafka messages to table column(s). Any of the following found in deephaven.stream.kafka.consumer can be used:
simple_spec - Creates a spec that defines how a single column receives a key or value field from a Kafka message when consuming a Kafka stream.avro_spec - Creates a spec that defines how to use an Avro schema when consuming a Kafka stream.json_spec - Creates a spec for how to use JSON data when consuming a Kafka stream.protobuf_spec - Creates a spec for parsing a Kafka protobuf stream. Uses the schema, schema_version, and schema_message_name to fetch the schema from the schema registry, or uses message_class to get the schema from the classpath.object_processor_spec - Creates a Kafka key-value spec implementation from a named object processor provider.KeyValueSpec.IGNORE - Ignore the field in the Kafka event.KeyValueSpec.FROM_PROPERTIES (default) - Creates a single value column. The column name comes from the deephaven.value.column.name entry in kafka_config and defaults to KafkaValue if that entry is not set. The column type comes from the deephaven.value.column.type entry or, if that entry is not set, from a recognized value.deserializer entry. If neither entry is set, consume raises an error. |
|---|
| table_type optional | TableType | One of the following TableType enums:
TableType.append() - Create an append-only table.TableType.blink() (default) - Create a blink table.TableType.ring(N) - Create a ring table of size N. |
|---|
Returns
An in-memory table.
Examples
In the following example, consume is used to read the Kafka topic testTopic into a Deephaven table. Only the first
two positional arguments are required to read a Kafka stream into a Deephaven table.
- The first positional argument,
{'bootstrap.servers': 'redpanda:9092'}, is a Python dictionary that is standard for
any Python library consuming messages from Kafka. This dictionary gives the underlying Kafka library information about
the Kafka infrastructure.
- Here, the host and port for the Kafka server to use to bootstrap the subscription are specified. This is the
minimal amount of required information.
- The value
redpanda:9092 corresponds to the current setup for development testing with Docker images (which uses
an instance of redpanda).
- The second positional argument is the name of the topic (
testTopic).
In the following example, consume is used to read Kafka topic share_price with additional settings enabled and a
specific key_spec spec and value_spec defined.
partitions is set to None, which listens to all partitions.offsets is set to ALL_PARTITIONS_DONT_SEEK, which starts without seeking.key_spec is set to simple_spec('Symbol', dht.string), which expects messages with a Kafka key field of
type string, and creates a Symbol column to store the information.value_spec is set to simple_spec('Price', dht.double), which expects messages with a Kafka value field of
type double, and creates a Price column to store the information.table_type is set to TableType.append(), which creates an append-only table.
In the following example, consume reads the Kafka topic share_price with an additional dictionary set and keys
ignored.
deephaven.partition.column.name is set to an empty string (""), so the result table does not include a column for the partition field.key_spec is set to IGNORE, so the result table does not include a column for the Kafka field key.
In the following example, consume reads the Kafka topic share_price in JSON format.
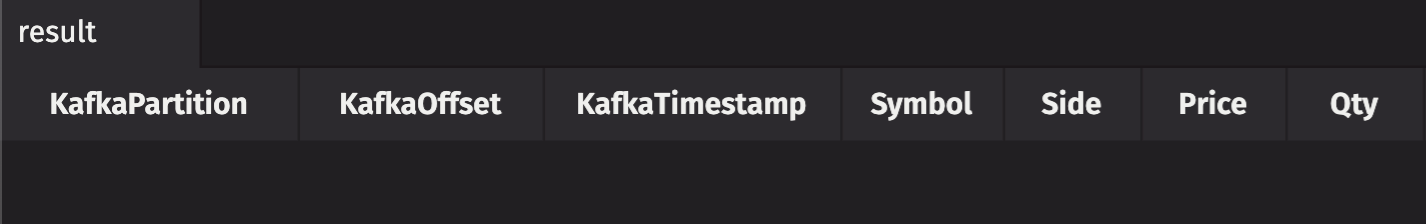
The following example also reads the Kafka topic orders in JSON format, but this time, uses a Jackson provider object processor specification.
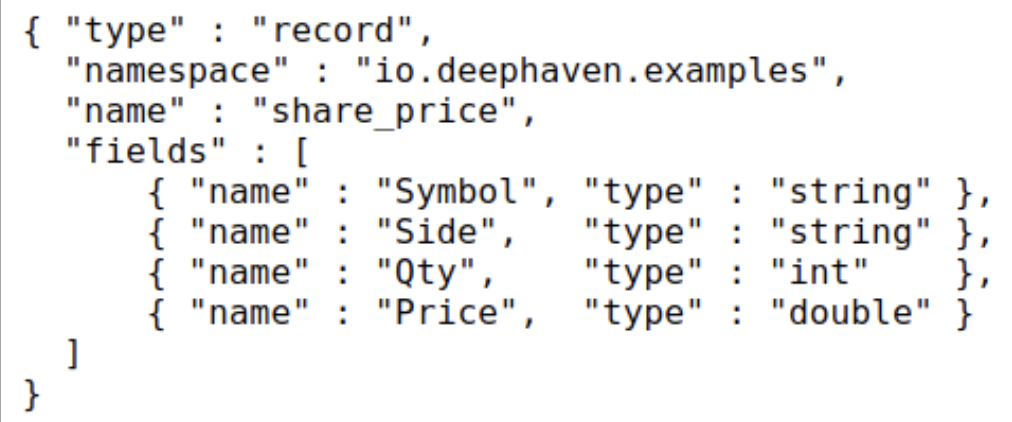
In the following example, consume reads the Kafka topic share_price in Avro format.