readTable
The readTable method will read a single Parquet file, metadata file, or directory with a recognized layout into an in-memory table.
Syntax
Parameters
| Parameter | Type | Description |
|---|---|---|
| sourceFilePath | String | The file to load into a table. The file should exist and end with the |
| sourceFile | file | The file or directory to examine. |
| readInstructions | ParquetInstructions | Optional instructions for customizations while reading. For example, |
Returns
A new in-memory table from a Parquet file, metadata file, or directory with a recognized layout.
Examples
Note
All examples in this document use data mounted in /data in Deephaven. For more information on the relation between this location in Deephaven and on your local file system, see Docker bind mounts.
Single Parquet file
Note
For the following examples, the example data found in Deephaven's example repository will be used. Follow the instructions in Launch Deephaven from pre-built images to download and manage the example data.
In this example, readTable is used to load the file /data/examples/Taxi/parquet/taxi.parquet into a Deephaven table.
Compression codec
In this example, readTable is used to load the file /data/output_GZIP.parquet, with GZIP compression, into a Deephaven table.
Caution
This file needs to exist for this example to work. To generate this file, see writeTable.
Partitioned datasets
_metadata and/or _common_metadata files are occasionally present in partitioned datasets. These files can be used to load Parquet data sets more quickly. These files are specific to only certain frameworks and are not required to read the data into a Deephaven table.
_common_metadata: File containing schema information needed to load the whole dataset faster._metadata: File containing (1) complete relative pathnames to individual data files, and (2) column statistics, such as min, max, etc., for the individual data files.
Warning
For a directory of Parquet files, all subdirectories are also searched. Files whose names do not end in .parquet are ignored, except for the _metadata and _common_metadata files described above. All files ending with .parquet need the same schema.
Note
The following examples use data in Deephaven's example repository. Follow the instructions in Launch Deephaven from pre-built images to download and manage the example data.
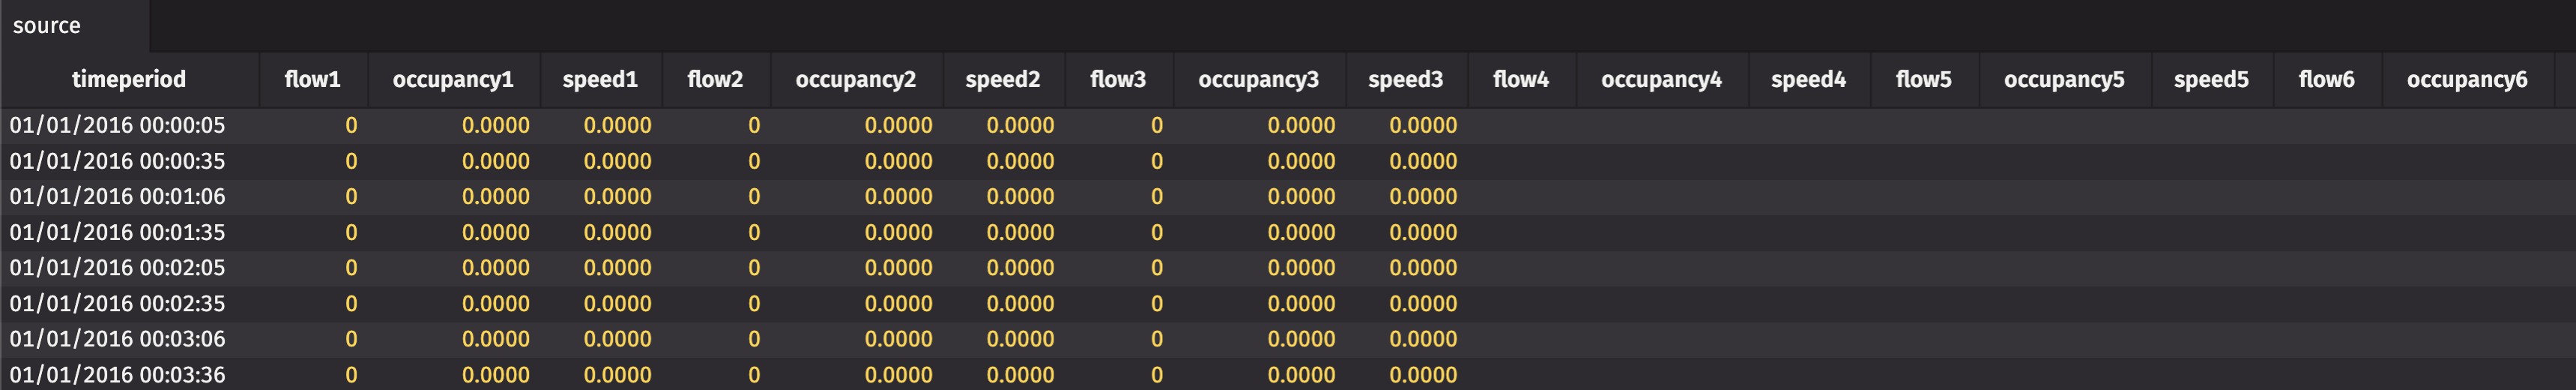
In this example, readTable is used to load the directory /data/examples/Pems/parquet/pems into a Deephaven table.
Read from a nonlocal filesystem
Deephaven current supports reading Parquet files from your local filesystem and S3 storage. The following code block uses special instructions to read a public Parquet dataset from an S3 bucket.
Additionally, the S3.maxFragmentSize configuration property can be set upon server startup. It sets the buffer size when reading Parquet from S3. The default is 5 MB. The buffer size should be set based on the largest expected fragment.