The Python-Java boundary and how it affects query efficiency
This guide discusses the relationship between Python and Java in Deephaven Python queries and how it affects query efficiency.
From Python to Java
Deephaven, on the backend, is written almost entirely in Java.
Deephaven's Python API allows users to perform tasks by wrapping the Java operations in Python. This is accomplished via jpy, a bi-directional Python-Java bridge that can be used to embed Java code in Python programs. This guide will cover Python -> Java.
jpy is a powerful tool taken full advantage of in Deephaven. However, Python developers typically don't want to have to write Java code. Moreover, they don't want to use Python just to invoke Java. So, the Deephaven Python API has wrapped Deephaven's powerful table operations in Python to make them PEP-compliant and easy for Python developers.
Why does this matter?
The Python-Java boundary can be crossed numerous times throughout a single query. Crossing this boundary takes time. So, the number of times this boundary is crossed will affect the query's efficiency. This concept becomes very important when working with real-time and big data, where speed can make or break them.
Here's a screenshot showing execution times between the built-in query language sin function, and numpy.sin:
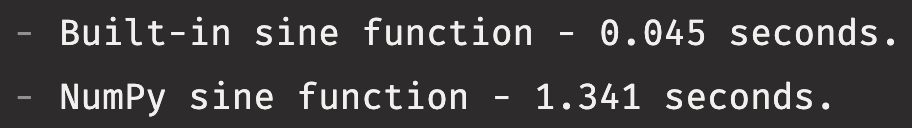
That's a pretty significant difference in execution time. Below is the code that produces it:
Why is NumPy so much slower?
- When creating
result_builtin, the query string uses built-in methods. This requires no crossings of the Python-Java boundary.- The
sinmethod is built into the query language.
- The
- When creating
result_numpy, the query engine calls NumPy'ssinmethod for every row. So, it has to cross the Python-Java boundary twice for each row.- The first time, it goes from Java to Python to calculate the sine of
X. - The second time, it converts the result from Python to Java.
- Deephaven can vectorize some Python function calls, making one call per chunk of rows instead of one per row. A call is vectorized only when it is a plain function call (not called through a module or object) that is not cast or used inside a larger expression.
np.sin(X)breaks two of these rules: it is called through thenpmodule, and its result is explicitly cast. So the engine calls it once per row, and 100,000 rows means 100,000 round trips.
- The first time, it goes from Java to Python to calculate the sine of
What's built into the query language?
Deephaven is written in Java under the hood, so all Java built-in classes are available. A list can be found here. Some of the most useful classes (and their subclasses) in queries are given below:
- java.lang
- java.lang.Math - Contains useful math functions.
- java.lang.Number - Useful for converting
BigDecimalandBigIntegerto primitive types. - java.lang.String - The Java String. This is the data type of any Deephaven string column.
- java.math
- java.math.BigDecimal - Arbitrary precision floating point value.
- java.math.BigInteger - Arbitrary precision integer value.
- java.util
- java.util.Arrays - Routines for searching and manipulating arrays.
- java.util.Collections - Routines that operate on or return collections.
- java.util.Random - Routines to generate pseudorandom numbers.
Not only that, but Deephaven has its own classes and methods built into the query language.
For guidance on using date-time types efficiently, see Time in Deephaven.
How to minimize the number of boundary crossings
Efficient queries typically make minimal Python-Java boundary crossings. They all have one thing in common:
They use Java methods and variables built-in to the query language.
When there is a one-to-one translation for a function, you should prefer to use the Java equivalent. If there is no Java equivalent, simply be aware of the size of your data and the number of boundary crossings. In the above example, processing 100,000 rows took about 1.3 seconds longer with NumPy. Whether that overhead is acceptable depends on your data size and update frequency.
Memory considerations
When using Python user-defined functions (UDFs) in Deephaven query strings, Python memory is allocated outside the Java heap. This has important implications:
- OOM risk — When total process memory grows too large, the Linux Out-Of-Memory (OOM) killer may terminate processes. This can happen when the combined Java heap and Python memory exceed the available system or container memory.
- Unbounded memory growth — Python objects allocated during UDF execution can accumulate over time, especially in long-running or high-throughput queries. This can lead to resident memory far exceeding the configured Java heap size.
Recommendations
To minimize memory risks when using Python UDFs:
- Convert performance-critical UDFs to Java — For frequently called functions, consider implementing them in Java or using built-in query language functions instead.
- Avoid returning large Python objects in UDFs — They can remain in Python memory for extended periods, and if not freed in a timely manner, may cause a Python
MemoryErrorand crash the worker process. Instead, when possible, have UDFs return only the data needed for table columns, which are typically primitive types and text. If Java is not actively garbage collecting unused table columns that store Python objects, calldeephaven.garbage_collectto run Python garbage collection and request a JVM garbage collection. The JVM treats the request as advisory, so the effect is not guaranteed. - Monitor resident memory — Track total process memory, not just Java heap usage, for queries using Python UDFs.
The Python API under the hood
Deephaven's Python API wraps its engine, written in Java, in Python. It adds small amounts of initialization overhead all for the sake of ease of use. For example, the update table operation creates a new table containing new, in-memory columns for each operation given in a list. Below is a simplified snippet of the Python source code for a Deephaven table with the update method.
-
The Python class
deephaven.table.Tableis a wrapper around the Java class,io.deephaven.engine.table.Table. This allows for a Pythonic interface for a Java method. -
_J_Tableis jpy's reference to the Java class. -
jpy.JTypeis jpy's type for Java objects. -
jpy.castensures thatj_tableis the correct type, and ensures that jpy has the correct signatures for making calls into Java. -
j_table.update(*formulas)is how jpy can call intoupdate. -
The returned result is a Python-wrapped Deephaven table.
Much of Deephaven's Python API looks like this under the hood. It serves two primary purposes: convenience and speed. The Python wrappers make using Deephaven feel Pythonic without losing the concurrency and efficiency offered by the query engine.