Deephaven's design
Note
New to Deephaven? Start with How Deephaven works: A mental model for an approachable introduction before reading this technical deep-dive.
We built Deephaven to be an incredible tool for working with tabular data — full stop. To us, tables are dynamic, powerful constructs, but we certainly care about static, batch ones too. In this piece, we explore some of the underlying technical and architectural decisions that, taken together, deliver Deephaven's value proposition.
This guide assumes familiarity with distributed systems, JVM architecture, and modern data platforms. For hands-on, task-focused guidance, see our how-to guides.
Deephaven's architecture is built on several key innovations. This page starts with two overviews and then explains each innovation:
- The live data stack: The engine, API, and UI layers that carry live data from its source to code, dashboards, and applications.
- How Deephaven compares: A side-by-side look at Deephaven and traditional batch-plus-streaming architectures.
- Table update model: Real-time and static data flow through the same directed acyclic graph (DAG) with automatic dependency tracking and incremental updates.
- Distributing DAGs: Snapshot-plus-delta replication extends the update model across processes.
- Unified batch and streaming: Batch and real-time data coexist behind a single, consistent API — no separate systems or complex coordination required.
- Tables designed for sharing:
RowSets andColumnSources enable zero-copy operations and efficient memory usage across query operations. Walkthroughs ofwhereandupdateshow the sharing in practice, and listeners keep each result live. - Mechanical sympathy: Chunk-oriented processing, columnar layouts, and careful JVM optimization make the engine work with the hardware and JVM rather than against them.
- Formula and condition evaluation: Most user expressions compile to Java classes that read data in chunks.
- Language and client integration: Groovy and Java run directly on the JVM engine, Python reaches it through jpy, and clients in other languages connect through gRPC. For custom UIs,
deephaven.uibuilds reactive web applications entirely in Python, andweb-client-uiprovides JavaScript/TypeScript components for custom front ends.
The live data stack
Deephaven is a full-stack data system that unifies live and historical data in a single, composable environment. Unlike traditional architectures that force trade-offs between batch and streaming, Deephaven delivers both through a unified platform built on three integrated layers:
| Layer | Components | What it provides |
|---|---|---|
| Engine | update graph, ColumnSources and RowSets, chunks | Incremental computation, columnar storage, zero-copy operations |
| APIs | gRPC/Barrage, Python, Java, C++, C#, JS, Go, and R clients, Arrow Flight | Cross-language access, network-transparent DAGs, real-time subscriptions |
| UI/Applications | deephaven.ui, web-client-ui, Jupyter widgets | Live dashboards, reactive components, real-time visualization |
At the core of this stack are Live Dataframes, Deephaven's signature abstraction. A live dataframe is a table that updates continuously as its sources change, so its data flows naturally through code, dashboards, and applications. When a source table changes, updates propagate through the entire stack:
- Engine: The update graph detects changes and propagates them through the DAG.
- APIs: The Barrage protocol streams incremental updates to connected clients.
- UI: Components automatically refresh to reflect the latest data.
This architecture means the same table can simultaneously serve a Python script, a Java application, a web dashboard, and a remote client. Remote clients receive the table as a snapshot followed by incremental deltas. Distributing DAGs and global consistency explains how that works and what consistency it gives.
Why this matters: Traditional systems require separate pipelines for batch and streaming, with different APIs, different mental models, and complex coordination. Deephaven's live data stack removes that complexity. Whether you're analyzing historical Parquet files or streaming Kafka data, you use the same code, the same operations, and the same UI, and subscribed consumers stay up to date as the data changes. Unified batch and streaming explains how.
How Deephaven compares
| Capability | Traditional approach | Deephaven |
|---|---|---|
| Batch + real-time | Separate systems for each | Unified table API for both |
| Update model | Recompute full datasets | Incremental (only affected rows) |
| Memory efficiency | Each derived view copies its data | Shared RowSets and ColumnSources |
| Query consistency | Manual coordination required | Automatic within a server via DAG and logical clock; consistent snapshots and deltas across processes |
| UI development | Separate front-end team/codebase | Pure Python (deephaven.ui) or JS (web-client-ui) |
| Data movement | Row-at-a-time or full scans | Chunk-oriented (thousands of values at once) |
| Performance | Tuned per system | Engine designed around hardware and JVM behavior (mechanical sympathy) |
The sections below explain how Deephaven delivers each of these capabilities.
Table update model
Deephaven's real-time engine uses a directed acyclic graph (DAG) to propagate updates efficiently through query operations. This architecture provides significant advantages over traditional batch processing.
How the DAG works
Queries automatically form a DAG where:
- Vertices represent tables or data operations.
- Edges represent dependencies and data flow.
- Updates propagate incrementally — only the affected data recomputes.
- Consistency comes from a logical clock that coordinates update cycles.
An update cycle is one pass in which the engine propagates a batch of changes through the DAG. Update graph (UG) cycles explains the batching.
The logical clock tracks two values for each cycle:
- Step: a counter that increases once per cycle.
- Phase: updating or idle.
Tables check the clock to tell whether their inputs have finished updating in the current cycle, so every table sees the same set of changes. The table update model describes the clock in more detail.
For example, consider this simple query:
When source receives a new row, the DAG ensures that filtered and aggregated update automatically and consistently. The engine processes only what changed.
Performance impact: Incremental updates mean a 1-row change to a million-row table recomputes only what that change affects, not the entire dataset. How far a change reaches depends on the operation:
- A filter or
updatetouches the changed rows. - A join or aggregation updates the matching output rows or groups.
In a trading scenario with 1,000 updates per second to a 10-million-row table, each one-second cycle handles about 1,000 changed rows, and for most operations the work tracks those rows. A full-recompute system would reprocess all 10 million rows every time it refreshes.
Update graph (UG) cycles
The update graph (UG) is the engine component that drives the DAG. It batches updates at a configurable target interval and propagates each batch through the DAG in topological order, one batch per cycle. A cycle takes longer than the interval when its work requires it. The Periodic Update Graph guide describes how to set the interval.
Batching updates into cycles:
- Improves efficiency: Processes multiple changes together instead of one at a time.
- Ensures consistency: All tables see the same snapshot of changes.
- Reduces overhead: Minimizes per-update costs.
For comprehensive coverage of DAGs, UG cycles, garbage collection, custom listeners, and performance optimization, see our DAG concept guide and table update model.
Distributing DAGs and global consistency
At Deephaven, we believe that our approach to propagating static and updating tabular data will revolutionize distributed data systems development.
As How the DAG works describes, the Deephaven query engine propagates updates via a DAG, relying on a logical clock to mark phase and step changes for internal consistency. While this sort of coordination is suitable within a single process, the coordination overhead becomes prohibitive when extending such a DAG across multiple processes.
Based on this observation, we've implemented a design for multi-process data-driven applications. It replicates tables consistently by sending an initial snapshot and then incremental deltas. This design:
- Extends the DAG across process and network boundaries, so you can build distributed data-driven applications.
- Gives each process its own logical clock, independent of the others, so processes propagate updates in parallel.
- Allows bidirectional data flows. A process that publishes one table can consume other tables.
Decoupling the logical clocks intentionally trades away "global consistency" for increased throughput and scalability. In practice, we think such a global view is either illusory or better built from end-to-end sequence numbers:
- Often illusory: Input sources often publish asynchronously with respect to each other. True consistency is then limited to something narrower, such as "mutual consistency based on the inputs observed at a given point in time."
- Better built from sequence numbers: For data sources that contain correlatable sequence numbers, Deephaven offers tools for synchronizing tables that reconstruct a consistent state within the query engine.
Remote clients use the same model. A client with an active Barrage subscription receives an initial snapshot and then consistent, incremental deltas as the table updates. Each remote client receives updates through its own subscription stream, so different clients may see an update at slightly different times.
A client can instead take a one-time snapshot, for example with pydeephaven.Table.to_arrow, which uses Arrow Flight's DoGet. That client gets a static copy of the table at that moment, not a live stream.
Unified batch and streaming
Many use cases require analyzing and commingling static and dynamic data. Capital markets trading systems are one classic example. They manage previous days' historical data, which is static, separately from intraday data, which is still growing. Models are often bootstrapped over the historical data and then extended with intraday data as it arrives.
Infrastructure monitoring systems that aggregate data hierarchically across many nodes are another example. They batch-process older data and aggregate it at coarse granularity, while keeping fresh data in raw form for minimum latency.
We don't think users should have to use different tools or APIs for these two types of sources, for two reasons:
- Learning curve: Learning two APIs can take twice as long as learning one, and users must keep remembering how each API performs the same operation.
- Ease of data integration: Merging or joining data accessible via different systems often requires a third tool for data federation or a custom tool, which is one more system to build and maintain.
At Deephaven, we have designed and implemented a unified table API that offers the same operations and semantics for both static and dynamic data sources. A few specialized table types restrict some operations. For example, blink tables don't support group_by.
A Deephaven table backed by real-time data refreshes in every update graph cycle in which its inputs change. Each update presents a consistent view of the data to downstream tables in the update graph. External listeners and data extraction tools, whether in-process or remote, see the same consistent view.
Example: The same code works for both static and live data:
Traditional lambda architecture requires separate systems for batch and real-time data — a batch layer, a speed layer, and a serving layer — with complex coordination between them. Deephaven needs none of that. As the example shows, only the data source changes.
The gRPC API links Deephaven query engines with one another and with client applications. Together, the update model, the unified API, and the gRPC API let Deephaven stand in for the lambda architecture. End users learn one API for data manipulation and access, and it works the same on every layer.
Deephaven Community Core gives users a comprehensive, extensible query engine that can interact with and commingle data accessed or ingested directly from disparate sources, including custom applications, Apache Parquet, Apache Kafka, Apache Iceberg, CSV, JSON, Arrow, JDBC, ODBC and ADBC, and CDC streams.
Deephaven Enterprise builds the unified batch-and-streaming model into the product. It provides tools to:
- Publish persistent, append-only, immutable data streams as tables.
- Distribute that data to many query engines hosted in remote applications.
- Manage the data lifecycle.
- Orchestrate data-driven applications.
Deephaven Enterprise post-processes, stores, and serves historical data in a form that maximizes throughput for common queries. It serves raw, real-time data with minimum latency. Its distributed data service layer integrates both.
Tables designed for sharing and updating
Deephaven builds tables from data structures that lend themselves to efficient sharing and incremental updating. At its most basic, a table consists of two components:
- A
RowSetthat enumerates the possibly sparse sequence of row keys (non-negative 64-bit integers) in the table. - A map associating names with
ColumnSources that allow data retrieval for individual row keys, either element-by-element or in larger batches.
A ColumnSource represents a column of data, which may update dynamically and which multiple tables can share.
A RowSet selects elements of that ColumnSource. It might cover all the data in the ColumnSource or only a subset of it.
A RowRedirection is a separate structure that maps row keys from one key space to another. Deephaven applies it to a ColumnSource, not to the RowSet. This lets a table present its parent's column data under a different key space. For example, a table can appear reordered without copying the underlying column data.
Filtering with where creates a new RowSet that is a subset of the parent's RowSet.
Sorting usually creates a new RowSet for the result. When a static source is already in the requested order, the result keeps the parent's RowSet. The shape of a new sorted RowSet depends on the source:
- For a static or blink source, it is flat. Its row keys run contiguously from 0 to the row count minus 1.
- For any other refreshing source, it starts as one contiguous range of row keys placed in the middle of the row key space, leaving room on both sides. As updates crowd a region, the engine opens gaps between rows and places later rows in those gaps in sorted order, so it rarely has to renumber many existing rows.
When it creates a new RowSet, sorting applies a RowRedirection to the parent's ColumnSources so the rows appear in the new order.
Allowing a RowSet's row keys to be sparse greatly reduces data movement within the RowSet and the ColumnSources it addresses. This is essential for the performance of Deephaven's incremental sort operation. It also matters when source tables publish changes that are more complex than simple append-only growth. Examples include multiple independently growing partitions and tabular representations of key-value store state.
A table may share its RowSet with any other table in its update graph that contains the same row keys. A single parent table maintains the RowSet for itself and every descendant that inherited it. These operations inherit their parent's RowSet:
- Column projection and derivation operations, such as
viewandupdate. - Column selection with
select, except on a static table whoseRowSetis not flat. There,selectusually creates a new, flatRowSet. - Some exact and relational joins and time-series joins, such as
natural_join,exact_join, andaj. These inherit the left input table'sRowSet.
A table may share any of its ColumnSources with any other table in its update graph that uses the same row key space or whose row key space can be redirected onto the same row key space. A single parent table is responsible for updating the contents of a given ColumnSource for itself and any descendants that inherited that ColumnSource.
Example of sharing:
By itself, this sharing capability represents an important optimization that avoids some data processing or copying work. In an updating query engine, this avoidance repeats in every update cycle, so the savings last for the lifetime of a query.
Performance impact: Shared ColumnSources save memory for queries with multiple filtered or joined views of the same source data. For example, five different where filters on a 10-column table share all 10 ColumnSources, storing only five different RowSets instead of duplicating 50 columns.
Operation pattern summary
Each operation decides separately whether to share or create its RowSet and each of its ColumnSources. This table shows what each common operation does:
| Operation type | RowSet | ColumnSources |
|---|---|---|
Filtering (where) | New (subset) | Shared |
Column derivation (update, view) | Shared | Mixed (shared + new) |
Sorting (sort) | Usually new (flat, or centered with room to grow) | Shared (via redirection) |
Joining (natural_join, exact_join, aj) | Shared (left table's) | Left: shared; right: shared via redirection |
Aggregation (agg_by, etc.) | New | New |
This sharing model, combined with incremental updates through the DAG, enables Deephaven to handle complex queries on large, rapidly changing datasets efficiently.
How operations work
Understanding how table operations execute helps explain why Deephaven is so efficient. This section traces through two common operations to show how RowSet and ColumnSource sharing work in practice.
What happens when you call where
The where operation filters rows based on a condition. Here's what happens internally:
-
Expression parsing: The engine parses the filter condition, such as
"Price > 100", and converts it into aWhereFilterobject that evaluates the condition efficiently. -
Consistent view: The operation reads a consistent view of the parent table's current
RowSet. For refreshing tables, this ensures the filter sees a stable view of the data. -
Evaluation: The
WhereFilterevaluates the condition against the parent'sColumnSourcedata, processing rows in chunks for efficiency. The filter collects only the row keys that satisfy the condition. -
Result table creation: The engine creates a new table with:
- New
RowSetcontaining only the matching row keys, a subset of the parent'sRowSet - Shared
ColumnSources, so the result points to the parent's column data with no copying
- New
-
Listener attachment: If the parent table is refreshing, or if the filter depends on refreshing data, the engine attaches a listener. The listener receives each of the parent's updates, so the filtered table updates automatically. On each update cycle, it typically re-evaluates only the changed rows, though some filter conditions may trigger broader re-evaluation.
Why this is efficient: The result table doesn't copy any column data. It maintains a smaller RowSet that selects which rows from the shared ColumnSources are visible. This is the sharing that the five-filter example relies on.
What happens when you call update
The update operation adds or replaces columns with computed values. Here's the execution flow:
-
Formula parsing: A direct column reference, such as
"X"or"Y = X", is recognized first and skips compilation. JavaParser parses every other formula, such as"Total = Price * Quantity", and the engine compiles it into executable code. -
Column source creation: Each computed column gets a new
ColumnSource.updatecomputes the values once and stores them.update_viewstores only the formula and computes each value when it is read.- A direct column reference (an alias like
"Y = X") reuses the parent'sColumnSourcewhen that column is already held in memory. Otherwise,updatecopies the data into a new one.
-
Formula evaluation: For
update, the engine evaluates the formula for each row in theRowSetand stores the results in the newColumnSource. It processes data in chunks for efficiency. -
Result table creation: The engine creates a new table with:
- Shared
RowSet, so the result has exactly the same rows as the parent - Shared
ColumnSources for pass-through columns - New
ColumnSources for the computed columns
- Shared
-
Listener attachment: For refreshing tables, a listener computes derived columns for added rows and recomputes them for modified rows whose input columns changed.
Why this is efficient: Only the new computed columns require storage. All other columns are shared with the parent, and the RowSet is inherited directly.
How operations stay live
The listeners that attach to refreshing tables are what make Deephaven tables "live." When a parent table updates:
- The parent table enqueues an update notification for each child listener.
- Each listener receives a
TableUpdatedescribing which rows were added, removed, modified, or shifted, along with information about which columns changed. - The listener processes the update and propagates its own update downstream. Most operations process only the changed rows. Some filters may need to re-examine additional rows.
This is how the DAG propagation described earlier happens at the level of individual operations. A single source change cascades through filters, joins, and aggregations. The engine processes this DAG within a single update graph cycle. The results then flow asynchronously through the API layer via Barrage to connected clients and UI components.
This is the technical foundation of Live Dataframes. A table whose source never changes is static. A table connected to streaming data is live. Most downstream operations preserve that behavior. Some operations, such as snapshot, intentionally produce static results from live sources.
Mechanical sympathy
"You don't have to be an engineer to be a racing driver, but you do have to have Mechanical Sympathy."
— Jackie Stewart, racing driver
Mechanical sympathy means writing software that works with the hardware and runtime underneath it rather than against them. One of our favorite blogs explains the term and its rationale in Why Mechanical Sympathy?. As systems programmers, we know it's best to use our tools the way their designers intended. These tools include the JVM, the host OS, I/O subsystems, and the CPU. We've optimized our query engine with this principle in mind, and we continue to refine it.
Key observations
A few key observations shape Deephaven's approach to mechanical sympathy:
- Large-scale aggregations and other operations are often best served by columnar storage. Deephaven's column orientation provides flexibility and performance.
- Data movement can have high fixed costs. It's often best to amortize those costs over many rows, cells, or bytes to achieve higher throughput. Larger reads have limits, though, so Deephaven uses block-oriented data reads and caches, with block sizes chosen to balance that saving against two costs of larger reads:
- Fetching more data than an operation uses has its own cost, called "read amplification."
- Working with overly large blocks of data can hurt locality of reference and cache performance.
- Predictable code is code that is unlikely to mislead the branch predictor, and the CPU can optimize it more easily. Deephaven's engine code often has relatively few branches, especially in the inner code of a loop. Our generated code typically prunes unreachable cases.
- JIT compilation in modern JVMs can work wonders for performance if you let it. We try to help it along by:
- Avoiding virtual method invocations that can't trivially be inlined, especially in inner loops.
- Operating on dense regions of memory to allow for vectorization when the CPU offers SIMD instructions.
- Garbage collection can seriously degrade performance, both by consuming CPU resources that might otherwise be available for application throughput and by triggering unpredictable slowdowns or pauses at performance-critical times. Deephaven uses preallocation and object pooling to lower overall young generation usage. To the extent possible, and particularly within our inner loops, we try to use reusable objects rather than allocating many temporaries.
- Concurrency can be a double-edged sword. Poorly designed concurrent systems can be slower than single-threaded ones because of resource contention, false sharing, and thrashing, so Deephaven avoids shared state wherever possible.
- Engine parallelism: The engine parallelizes stateless
select,update, andwhereexpressions, and it processes independent parts of the update graph in parallel. A stateless expression doesn't depend on mutable external inputs or on the order in which rows are evaluated. Parallelizing queries covers both, including when expressions that use Python objects run in parallel. - User parallelism: Partitioned tables let users parallelize their own workloads along natural partition boundaries.
Chunk-oriented architecture
The Deephaven query engine moves data around using a data structure called a Chunk. This subsystem is key to achieving mechanical sympathy in our implementation.
By working with chunks of data rather than single cells, we allow the engine to amortize data movement costs at every applicable level of the stack. For example, ColumnSources are also ChunkSources, which means they can transfer data in bulk through getChunk and fillChunk rather than one cell at a time. A ColumnSource may in turn implement these transfers by wrapping or copying arrays, by reading the appropriate region of a file, or by evaluating a formula once for each result element.
Deephaven implements chunks as regions of Java arrays. Chunks are strongly typed by the storage they represent:
- There is one chunk implementation for each Java primitive type and another for Java
Objects. - Chunks that code can modify are
WritableChunks. Each writable class, such asWritableIntChunk, extends its read-only counterpart and adds mutators. - Chunks take a generic attribute argument that names the kind of data they hold, such as values, hash codes, or chunk positions. This gives compile-time type safety with no runtime cost.
In the Chunk type hierarchy, per-cell accessors such as get, set, and add are final, so the JIT can inline them and per-cell access never makes a virtual method call. Bulk copy methods such as copyToChunk and copyFromChunk are final too. Only a few methods, such as slice, are virtual, with multiple implementations.
The engine pools chunks and reuses them as temporary data buffers, which reduces garbage generation and the frequency and duration of garbage collection.
Performance impact: Processing data in chunks instead of one element at a time reduces method call overhead by orders of magnitude and gives the JIT compiler tight loops that it can vectorize. Each operation sizes its chunks, typically in the thousands of elements.
Columnar hash tables
Deephaven join and aggregation operations often use a columnar hash table built on chunks. Where data patterns permit, it hashes, inserts, and probes whole chunks of single or multi-column keys at once. Each part of the hash table uses chunk-oriented kernels to hash data, sort data, and find runs of identical values. These kernels enable vectorization and avoid virtual method lookups.
RowSet implementations
Every table operation relies on the RowSet that enumerates its row keys, so how RowSets are stored matters as much to mechanical sympathy as how column data moves. In practice, RowSets switch between three implementations depending on size and sparsity:
- Single range: One contiguous range of row keys. Ideal when all row keys in a
RowSetare contiguous. - Sorted ranges: Several contiguous ranges in sorted order. Ideal for tables with a small number of ranges, no matter how widely separated.
- Regular Space Partitioning (RSP): Our take on the popular Roaring Bitmaps (RB) data structure, for large or widely distributed sets of row keys. It splits the row key space into fixed blocks of 2^16 keys, each held in a container. Regular Space Partitioning (RSP) vs. median-split trees describes it in detail.
In all cases, the goal is to allow for efficient traversal or set operations with minimum storage cost and high throughput.
Performance characteristics:
| Implementation | Best for | Memory | Operations |
|---|---|---|---|
| Single range | Contiguous keys | O(1) | O(1) |
| Sorted ranges | Few ranges | O(ranges) | O(log ranges) lookup; O(ranges) insert and set operations |
| RSP | Sparse, large sets | O(containers) | O(log containers) lookup; O(containers) set operations |
Regular Space Partitioning (RSP) vs. median-split trees
A simple way to accumulate a set of values, such as a RowSet, is a sorted array. For example, the following sorted array of only a few values is very simple and efficient:
To keep an array sorted when performing operations such as an insert, the system must first find where to put the new value. This requires a binary search, which is an O(log n) operation. Next, the system makes space for the new value. As the set grows, the system splits the array at its median and arranges the two pieces in a tree structure. This page calls that structure a median-split tree.
To insert 10 into the array above, the system first checks whether the resulting array is too big. If it is, the system splits it at a median value, creating two sub-arrays and a parent node:
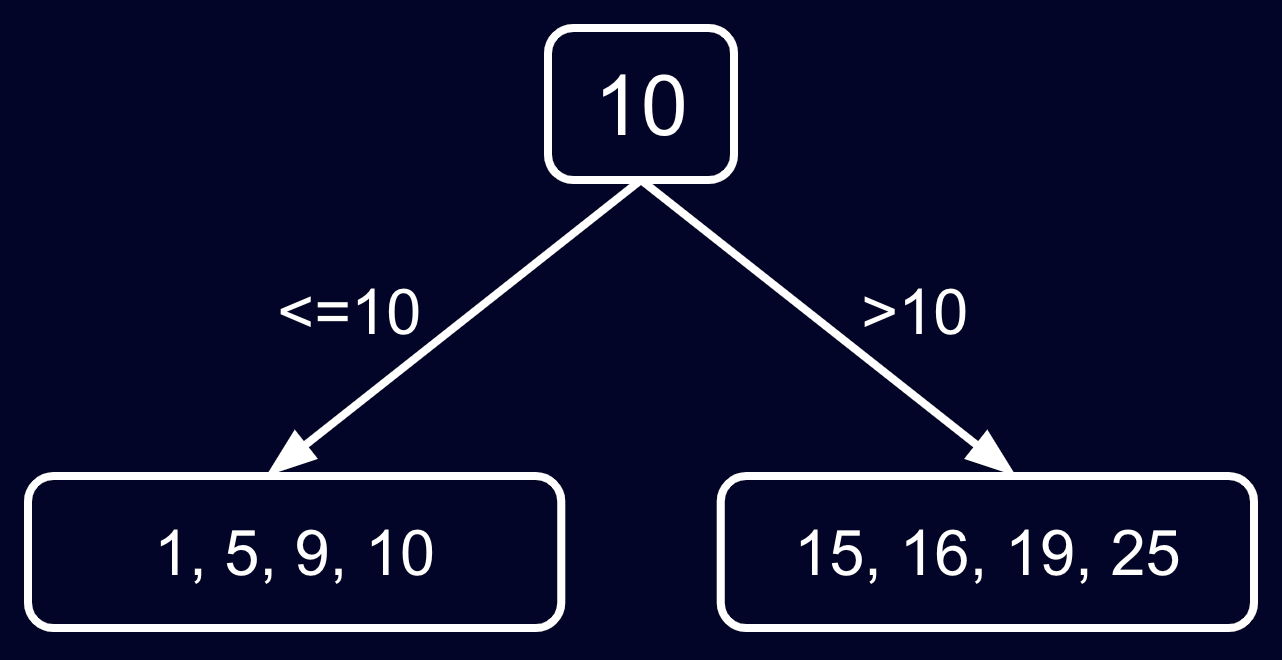
In this case, 10 is the parent node that tells a search which sub-branch to descend.
For big RowSets — often accumulating millions of values — the overhead on median-split tree operations can be high. As a single RowSet is created or grows, the binary subdivision operation can be expensive. Operations that combine two RowSets, such as union, intersection, or set difference, can be particularly expensive because they need to look at the individual values in each RowSet and decide which values go in the result.
RSP is Deephaven's general-purpose RowSet representation for large, sparse sets of row keys, and it avoids the median-split tree costs above.
Deephaven's RSP is modeled on the Roaring Bitmaps RoaringArray:
- It divides the row key space into fixed blocks of 2^16 (65,536) keys, and each block's keys are held in a container.
- Its containers come from a library initially derived from the Java RB implementation. Deephaven adds a few special-case containers that use less memory in important edge cases.
- Containers sit in an array, with a parallel array that holds each entry's key, as in RB.
- RSP stores a run of blocks that would be entirely full as a single entry in that array instead of one container per block.
- Deephaven adds substantial optimizations for widely distributed row key ranges.
Fixed split points give RSP three advantages over a median-split tree:
- Known locations: A median-split tree splits at the median of the values, such as 10 in the example above. RSP splits at every integer multiple of 2^16, whatever values the set holds. Row key 65,537 can only be in the second container, which holds keys 65,536 through 131,071.
- Faster set operations: Two
RowSets always split at the same boundaries. For large datasets, union, intersection, and set difference are usually much faster, because they process one pair of matching containers at a time and never cross array boundaries that fall at different points in eachRowSet. - Compact ranges: Writing out every value in the set
[ 0, 1000 * 2^16 - 1 ]would take 1,000 full containers. RSP instead stores a continuous range that spans full blocks,[ n * 2^16, m * 2^16 - 1 ]form > n, as one entry.
RSP costs more for small RowSets, because each one still needs an array of containers and then the containers themselves. This matters for queries that create one RowSet per row, such as joins. The single range implementation in RowSet implementations covers that case.
Formula and condition evaluation
Deephaven table operations often take complex, user-defined expressions. A formula creates a column, and a condition filters rows. We've made several key design decisions that either enable interesting use cases or allow for significant optimization.
Expression parsing
Deephaven uses JavaParser to turn user-specified expressions into executable code:
- Direct column references: An expression that is just an existing column name, or an alias for one (e.g.,
"Y = X"), bypasses compilation entirely and can reuse the existingColumnSource, as What happens when you callupdatedescribes. - Other formulas: Deephaven compiles every other formula into a Java class, no matter how simple it looks. Filter conditions have a shortcut, described below.
Example of formula evaluation:
Deephaven caches compiled classes, so an identical formula reuses the class it already built.
Compilation also does two things for the formula:
- It replaces column name references with parameters, which the engine fills from data it loads in chunks.
- It lets the formula read a whole column as an array indexed by row position, such as
X_[ii - 1].
A filter condition that compares a column with a literal value or a query scope variable, such as "Price > 100", "Sym = `AAPL`", or "Sym in `AAPL`, `MSFT`", usually becomes a built-in range or match filter, and no class is compiled. A string-containment condition such as "Sym includes `AA`" also skips compilation. Most other conditions are compiled the same way as formulas. Integrating user methods describes an exception for Python functions.
Integrating user methods
Formulas and conditions can call any user function that is callable from Java, either directly or through the Java Native Interface (JNI). A formula or condition can also call a Python function.
When a formula or filter condition is a single call to an eligible Python function, whether ordinary or Numba-vectorized, the engine evaluates it with a chunked Python kernel. The kernel crosses from Java into Python once per chunk of rows instead of once per row, and the function runs once for each row in the chunk.
- In a formula: The engine compiles the expression, but the chunked kernel evaluates the column instead of the compiled class.
- In a filter condition: The engine skips code generation and uses a chunked Python filter.
Users can extend the query language with their own functionality by integrating external models and algorithms into their queries. This, in turn, enables all manner of exciting integrations with data science toolkits, whether open source or proprietary.
Further work on formula evaluation
Deephaven's formula and condition evaluation can still improve. We're especially interested in exploring alternative bytecode-generation strategies and integrating GraalVM as a compilation option.
Language and client integration
The Deephaven engine is written in Java. The components in this section let Python code, client applications in other languages, and user interfaces work with it.
Bridging Java and Python: jpy
Although the core of Deephaven is implemented in Java, we consider Python to be the most important language in use for writing Deephaven queries. We have invested significantly in a fork of the open source jpy project and work with the project's contributors to evolve its capabilities. Written in C with JNI and Python C APIs, jpy is a performant, low-level library.
To maximize the familiarity of the Deephaven data science and app-dev experience, we have developed a transparent, pure Python API that relieves the user of the details of calling jpy. During the design and implementation of this Pythonic API, we took special care to minimize the number of crossings between JNI and the Python runtime.
gRPC APIs for polyglot interoperability
Deephaven's core API is built on gRPC and Apache Arrow Flight, which have implementations in almost every language, so developers can implement compatible clients, and even servers, in almost any language. The API has several complementary modules. The two most important are:
- Arrow Flight service: High-performance columnar data transport. With Deephaven's Barrage extension, it also streams real-time, incremental updates.
- Table Service: A table manipulation API that mirrors the Deephaven engine's internal compute paradigm.
Read more in Deephaven's core API.
Building UIs
Deephaven provides two approaches for building custom user interfaces:
-
deephaven.ui: A Python web framework for building real-time data-focused applications. Write scripts entirely in Python — no front-end engineering, JavaScript, or CSS required.Key features:
- Component-based: Create user interfaces from components defined entirely with Python.
- Live dataframe aware: Components can use Deephaven tables as a data source.
- Reactive: UI components automatically update when the underlying Python data changes.
- Declarative: Describe the UI as a function of the data and let the framework handle the rest.
- Composable: Combine and reuse components to build complex interfaces.
- Broad: Components range from simple text fields to complex tables and plots.
For complete documentation, tutorials, and examples, see the
deephaven.uidocumentation. -
web-client-ui: JavaScript/TypeScript components for building custom web applications with full control over the front end.
The whole is greater than…
Deephaven is the result of evolution. Its architecture grew out of requests and feedback from sophisticated users and many years of R&D by a dedicated development team. Compelling problem sets deserve prolonged attention, and servicing real-time app-dev and data science use cases certainly qualifies.
Deephaven Community Core is modular by design. Modularity follows modern best practice and makes the software easier to extend. The engine, APIs, and user interfaces described on this page form one stack. Taken together, we hope you'll find Deephaven a compelling stack for your data-driven use case. Sometimes range matters, and range is a Deephaven superpower.
Related documentation
Conceptual guides
- How Deephaven works: A mental model
- Directed acyclic graph (DAG)
- Table update model
- Periodic Update Graph
- Table types
- What is Barrage?
- Core API design
- Parallelizing queries
- Deephaven Enterprise overview
How-to guides
- Use filters
- Joins: exact and relational
- Inexact, time-series, and range joins
- Combined aggregations
- Create and use partitioned tables
- Query strings
- Formulas
- Arrays
- Python functions in query strings
- Use Numba in Deephaven queries
- Create a time table
- Synchronize multiple tables
- Read Parquet files into Deephaven tables
- Connect to a Kafka stream
- Iceberg and Deephaven
- Read CSV or other delimited files
- Execute SQL queries
- Arrow Flight and Deephaven
- Use jpy
Reference
agg.avgagg.sum_agg_byajconsumeempty_tableexact_joinnatural_joinreadselectsnapshotsorttime_tableupdateupdate_viewviewwhereChunkJavadocChunkSourceJavadocColumnSourceJavadocRowRedirectionJavadocRowSetJavadocTableUpdateJavadocWhereFilterJavadocWritableChunkJavadocWritableIntChunkJavadocpydeephaven.Table.to_arrow
An in-depth look at what we've done, why we've done it, and why you should care.