AI/ML workflows
This guide explores several AI/ML workflows in Deephaven. It shows how to train a model on historical data with a table iterator, then apply it to live data in real time. It covers two ways to apply the model:
- A table operation, which works on any table.
- A table listener and table publisher, which work on any ticking table, including ones that modify or remove rows.
deephaven.learn is an alternative to these workflows. It works on static tables and on add-only or blink ticking tables. Append-only tables are add-only, so they qualify too.
Train a model
Training data in AI/ML applications is almost always historical and thus inherently static. You can train a model on historical data with a table iterator. Deephaven provides four table iterators:
Model training typically uses batch data, so a chunked iterator is usually the best choice. Use iter_chunk_dict or iter_chunk_tuple. The choice between the dict-based and tuple-based iterators is a matter of personal preference.
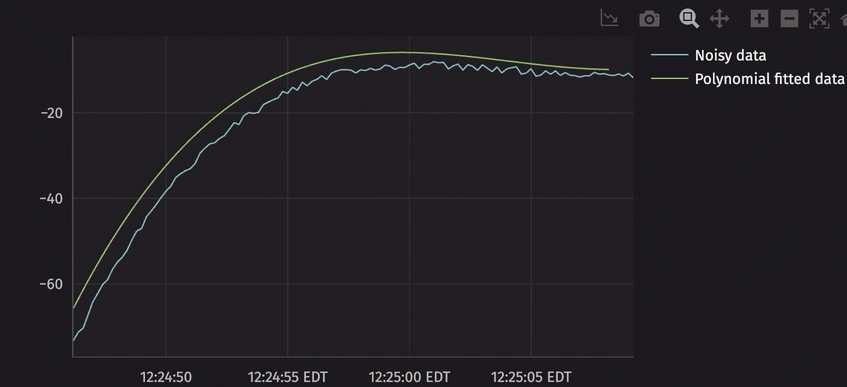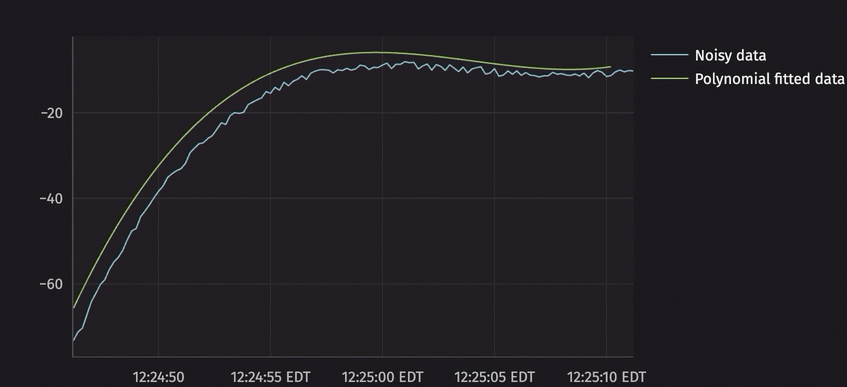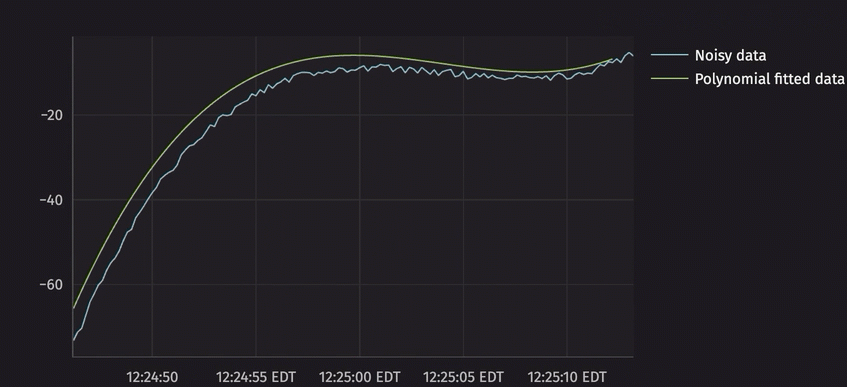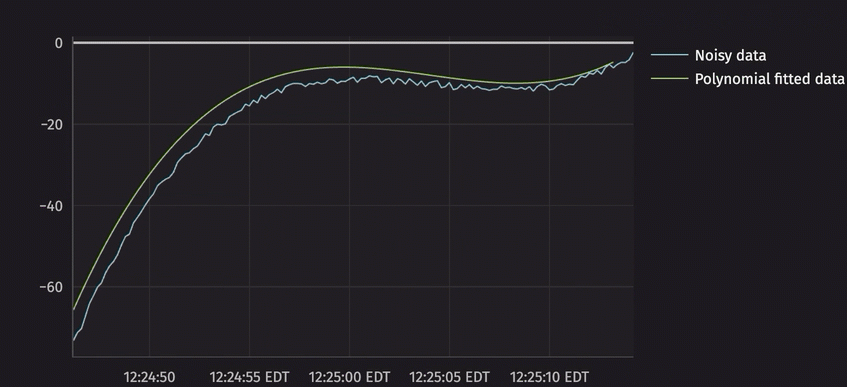
Consider the following code, which fits a cubic polynomial model to a table of noisy static data:
The printed polynomial is the model. Its coefficients approximate the 0.1, 0.3, -0.7, and -11 used to generate the data. They don't match exactly, because of the noise and because the model averages two separate fits.
Real-time inference
You can apply a trained model to a ticking table in two ways:
- Add a column with a table operation.
- Process each update with a table listener, and publish the results with a table publisher.
Table operations are simpler, while the listener and publisher give more control. Workflow trade-offs compares them.
The examples in this section apply the model fitted in Train a model, whose coefficients are stored in coeffs. Run that example first.
Table operations
One way to apply a model to a table in real time is to use one of the following table operations:
These operations create new columns from existing columns, so you can use them to add a column of model outputs. They differ in when they compute results and whether they store them in memory. For more information, see Choose the right column selection method.
The following code block uses update to apply the model. update performs the calculations immediately and stores the results in memory.
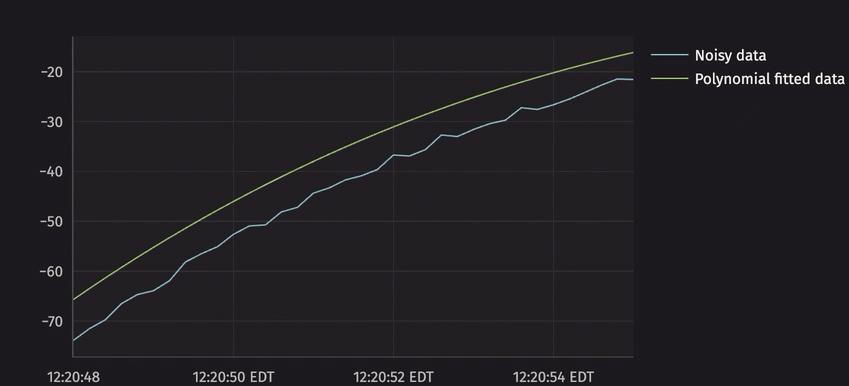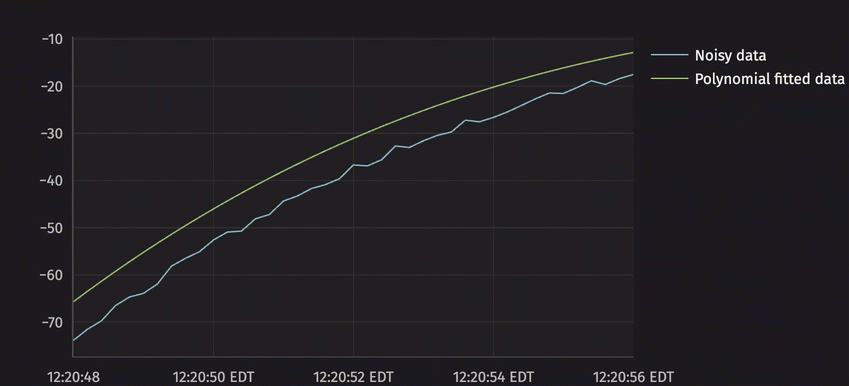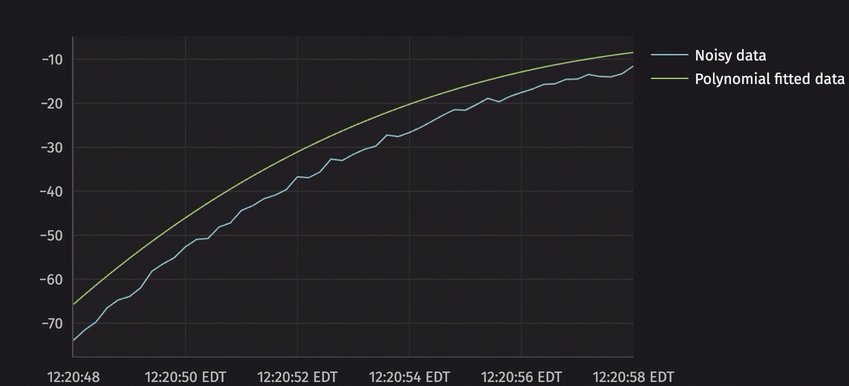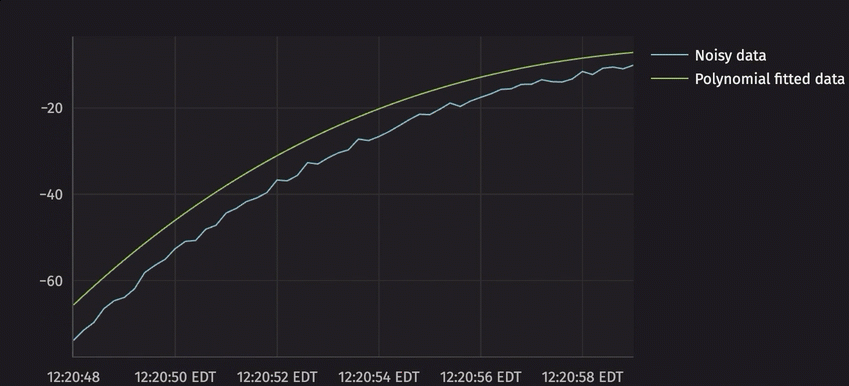
Table listener and publisher
A combination of a table listener and table publisher can also evaluate AI/ML models in real time. The listener runs in each update cycle in which the source table changes. It receives the rows that were added, modified, and removed, and passes the ones you choose to the model. The publisher writes the model's outputs to a new table.
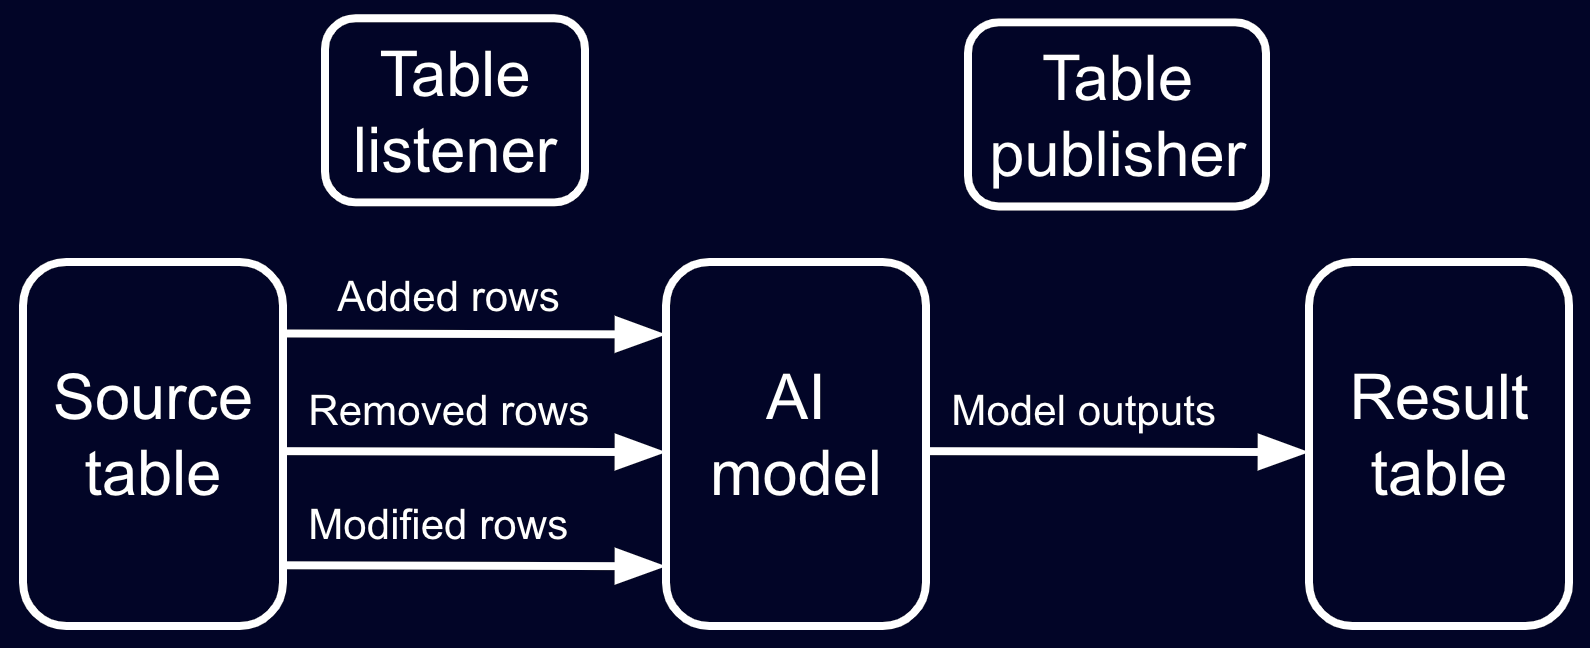
The diagram shows all three kinds of row change reaching the model. This guide's example passes only the added and modified rows to it.
The example below works in five steps:
- The table listener applies the polynomial model to the rows added or modified in each update cycle.
- The table publisher writes the outputs to
preds, a blink table that holds only the current cycle's outputs. - The
blink_to_append_onlycall convertspredsto an append-only table that keeps the full prediction history. - The
last_bycall keeps only the latest prediction for eachTimestamp. - The
natural_joincall joins those latest predictions back to the source table so the plot can show them next to the input data.
In on_update, the listener handles each kind of row change differently:
- Added rows: The listener applies the model and publishes one prediction per row.
- Modified rows: The listener applies the model again and publishes another prediction with the same
Timestamp.last_bykeeps only the latest prediction for each timestamp before thenatural_join. - Removed rows: The listener ignores them. Their old predictions stay in the prediction history. The
natural_joindrops them from the result, because it keeps only rows that are still insource_live.
The time table in this example only adds rows, so the modified and removed cases never happen here. They matter when you use the same listener on a table that modifies or removes rows.
The last_by step works because each row of the time table has its own Timestamp. When several rows can share a timestamp, publish and join on the column or columns that identify each row.
The example registers the listener with do_replay=True. Its first call also receives the rows already in source_live, so every row gets a prediction. For more information, see Replay data.
Use a thread pool
Deephaven calls a listener function inside the update cycle, while the update graph holds its exclusive lock. That lock gives the listener a consistent view of the data, but the cycle can't finish until the listener returns. A slow listener therefore makes every table in the update graph fall behind. To avoid this, run slow calculations on other threads.
Worker threads keep the model out of the update cycle. On a Python build with the GIL (global interpreter lock), they run Python code one at a time. They speed up a model only when its heavy work runs in native code, such as NumPy, PyTorch, or TensorFlow.
The following code uses a thread pool from Python's concurrent.futures module to illustrate the concept. It builds on the previous example, with these changes:
- It creates a
ThreadPoolExecutorwith four worker threads. compute_and_publishno longer takes the publisher as an argument.- The listener calls
executor.submit(compute_and_publish, timestamps, data)instead of callingcompute_and_publishdirectly. The model runs on a worker thread, and the listener returns right away. - A
report_errorcallback prints any exception a worker thread raises.
With more than one worker, calculations can finish out of order. If the source table modifies a row twice in quick succession, the older prediction can be published last. last_by keeps whichever prediction was published last, so the joined value can come from the row's older inputs.
To keep predictions in order, set max_workers=1. A single worker runs calculations in the order the listener submits them, and the model still runs outside the update cycle.
executor.submit returns a Future that holds any exception compute_and_publish raises. The example's report_error callback prints it, so errors on worker threads aren't lost.
To stop the example, call handle.stop(), then executor.shutdown().
Workflow trade-offs
So, you have a trained AI/ML model and aren't sure which workflow to use. Here are some things to consider:
- Table operations: Table operations are the simplest way to make predictions with a model, and they take a single line of code.
- With
updateorselect, the model runs inside the update cycle, so a slow model delays every table in the update graph. - With
view,update_view, orlazy_update, the model runs when the column is read instead, which can also be inside the update cycle.
- With
- Table listener and publisher: This workflow is more complex but more flexible.
- It passes each update's rows to the model as NumPy arrays, so the model can process them in one vectorized call.
- The publisher's outputs appear in the update cycle after the rows that produced them, so new rows in the joined result have a null
YFitteduntil then. With a thread pool, they can arrive later still. - The listener itself runs inside the update cycle. A slow model holds back the update graph unless the listener hands the work to a thread pool.
Related documentation
- Table types
- Incremental update model
- The update graph
- Multithreading: Synchronization, locks, and snapshots
deephaven.learn- NumPy in Deephaven
- PyTorch in Deephaven
- scikit-learn in Deephaven
- TensorFlow in Deephaven
- Table iterators
- Table operations overview
- Create a time table
- Listen to ticking tables
- Write data to an in-memory, real-time table
- Choose the right column selection method
- Deephaven Express
blink_to_append_onlydatetime_coldouble_colempty_tableiter_chunk_dictiter_chunk_tupleiter_dictiter_tuplelast_bylazy_updatenatural_joinnew_tableselecttable_publishertime_tableupdateupdate_viewviewdeephaven.table_listenerPydoc