Execution Context
An ExecutionContext is the environment the engine evaluates a query in. It bundles four things:
- The query library: the imports that query strings can use.
- The query compiler: it turns query strings into code.
- The query scope: the variables that query strings can use.
- The update graph: it schedules when ticking tables refresh.
Most of the time you never see it. When a Deephaven script session starts, it creates a default context and runs every query you enter in the console inside it. That default context is systemic: the system supplies it, not your code. A systemic context is unrelated to systemic object marking.
You need a context of your own in two situations: when a table operation runs on a thread you start, and when an operation does deferred work that the engine runs later. This page covers both, then shows when and how to create additional contexts.
Contexts are also a tool in their own right. Because each context can carry its own query scope and update graph, you can use contexts to keep independent real-time workloads from stepping on each other's variables or update cycles.
When an ExecutionContext is needed
The script session supplies a context for the code you run in the console. You must supply one yourself when:
- A table operation runs in a thread other than the script session's thread.
- A table operation does deferred work: the engine runs part of it later, outside the script session, such as when a new partition arrives in a partitioned table.
Table operations in a separate thread
Each thread has its own current context. A thread you start has no usable context until you open one in it.
Take, for instance, the following code, which attempts to use a TablePublisher to write data to a blink table in a separate thread once per second:
The table operation in the new thread fails, and the server log shows the following error:
This occurs because add_table runs in a separate thread, and the table operations it calls (empty_table and update) don't run inside an open ExecutionContext.
A simple fix lets the code run. Get the script session's context with get_exec_ctx, then open it in the thread with a Python with statement:
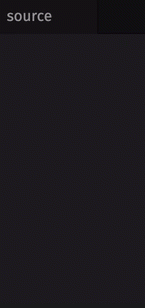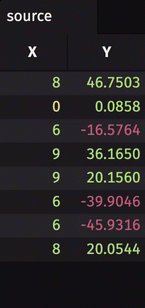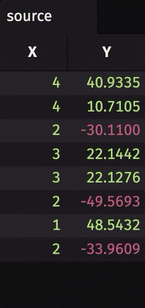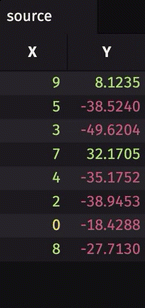
The source blink table now receives a batch of 5 to 10 random rows about once per second, five times. Several threads can use the same execution context, so any other thread you start can open ctx the same way.
Table operations that do deferred work
A partitioned table transform can do deferred work: if a new partition arrives later, the engine re-evaluates the transform function for that partition.
Operations that record a context for later work don't record a systemic one. Because the script session's context is systemic, transform doesn't record it for that deferred work. The function then runs without access to the query library, query scope, or query compiler unless it opens an execution context itself.
A time_table starts empty, so in the following code every partition arrives after transform is set up, and each call to max_date is deferred work:
sourceis a time table that adds a row every second. ItsKeycolumn isAfor the first five rows andBafter that.partition_bysplitssourceinto a partitioned table with one partition per key.transformcallsmax_dateon each partition.max_dateopens the script session's context,main_exec_ctx, around its table operations.
Alternatively, open a non-systemic context around the transform call. Called with no arguments, make_user_exec_ctx returns a user execution context: a copy of the current context that isn't systemic. Because it isn't systemic, transform records it, so max_date runs in it without its own with block:
When and how to create additional execution contexts
For most applications where a single user runs Deephaven, the systemic execution context is enough. Each ExecutionContext can have its own update graph, query library, and query scope, which lets you compartmentalize units of code so they work independently of one another. That matters in these more complex use cases:
- Freezing query-scope variables: Some work must keep the values its variables had when it was set up. For example, transforms set up in a loop each need their own iteration's value, and a thread might need to be shielded from changes that other threads make to the query scope. Pass
freeze_varstomake_user_exec_ctx, described in Create a context from the current one. - Isolating update processing: A secondary update graph runs its own update cycles, so an expensive operation on it doesn't delay the update cycles of the main graph. Separate update graphs refresh independently, so their update cycles can run in parallel on different cores. Build a context with its own update graph, described in Create an execution context from scratch.
- Separating workloads: When multiple users share a Deephaven server, or a single user wants to keep each workload's variables, imports, and update processing separate from the others, each workload can run in a context with its own query scope, query library, and update graph. Build each context from scratch, described in Create an execution context from scratch.
Create a context from the current one
The thread example and the first partitioned table transform example above reuse the script session's own context, which get_exec_ctx returns. make_user_exec_ctx creates a user execution context, which isn't systemic.
- Called with no arguments, it shares the current query scope, query library, query compiler, and update graph, as in the deferred-work example.
- Called with
freeze_vars, it gets its own query scope (shown below).
freeze_vars is a name or sequence of names from the current query scope. The new context's query scope contains only those names, with their current values, and later changes to those variables aren't visible in it.
The following code block freezes value1, value2, and value3, then sets value1 to 100. It runs the same update on an empty_table inside and outside the new context:
inside shows 1, the value value1 had when the context was created, and outside shows 100.
Neither form gives the context its own update graph. For that, create an execution context from scratch.
Create an execution context from scratch
Create an ExecutionContext from scratch, instead of using the systemic context or make_user_exec_ctx, when you need a context with its own query library or its own update graph, such as a separate PeriodicUpdateGraph or an EventDrivenUpdateGraph that refreshes only on request.
The following example builds an ExecutionContext from scratch by calling the Java builder through jpy:
Note
When creating a new update graph, you must provide a unique name. If you're running this in a Deephaven server where a "DEFAULT" update graph already exists, use a different name like "MyCustomGraph" to avoid conflicts. If you run the example a second time, the name is already taken, so call [existingOrBuild](/core/javadoc/io/deephaven/engine/updategraph/impl/PeriodicUpdateGraph.Builder.html#existingOrBuild() instead of build to reuse the graph you created the first time.
A context also has an operation initializer, which controls whether operations parallelize their initial work. It also carries the AuthContext that was current when the context was built. Deephaven records that AuthContext with the work done in that context, for example in the performance logs.
The builder lets you specify each component:
- Query library: A new query library with only the default imports, via
newQueryLibrary. - Query scope: A new, empty query scope, via
newQueryScope. - Operation initializer: Whether and how the engine parallelizes the initial work of table operations in this context, via
setOperationInitializer. The example passesOperationInitializer.NON_PARALLELIZABLE, which runs that work on the calling thread. - Update graph: A custom update graph, such as a
PeriodicUpdateGraphor anEventDrivenUpdateGraph, viasetUpdateGraph. - Query compiler: The compiler that turns query strings into code, via
setQueryCompiler.QueryCompilerImpl.createalso accepts an optional directory to add to the compiler's classpath and an optional parent class loader.
newBuilder starts from the current thread's update graph, operation initializer, and AuthContext. The example replaces the update graph and operation initializer and keeps the AuthContext.
A new PeriodicUpdateGraph doesn't refresh until you call its start method, as the example does.
The builder chain returns execution_context as a Java object, and a Python with statement can't open it directly. Wrap it in the Python ExecutionContext class first:
Because the query scope is new and empty, query strings in this context can't see the script's Python variables or functions. Query strings that use them fail with a Cannot find variable or class or Cannot find method error. Put any values they need in the context's query scope first, for example with execution_context.getQueryScope().putParam("my_value", my_value).
Refreshing tables that belong to different update graphs can't be used together in one table operation. For example, a join between a table that ticks on MyCustomGraph and a table that ticks on the server's main update graph fails.
To refresh only on demand, build an EventDrivenUpdateGraph instead of the PeriodicUpdateGraph and pass it to setUpdateGraph in the builder chain above. An event-driven graph has no start method, so leave out the start call. Instead, it runs one update cycle each time you call its requestRefresh method:
Related documentation
- Live DAG
- Table types
- Create an empty table
- Partitioned tables
- Query scope
- Time tables
- Use jpy
- Deephaven data types
cum_maxdrop_columnsempty_tablepartition_byTablePublishertime_tabletransformupdateupdate_byupdate_viewdeephaven.execution_contextPydocExecutionContextJavadocPeriodicUpdateGraphJavadocEventDrivenUpdateGraphJavadoc