Generate tables with Python functions
This guide covers function-generated tables, which enable the creation of ticking tables via a Python function. The function is run when either:
- One or more source tables tick.
- A refresh interval is reached.
Usage pattern
Function-generated tables follow this basic usage pattern:
- Define a Python function that returns a table.
- Define one or more trigger tables or a refresh interval.
- Create a function-generated table by calling
function_generated_table.- A function-generated table uses at most one of the following to trigger the function call:
- One or more trigger tables.
- A refresh interval.
- Supplying neither gives the result no trigger at all: the function runs once, and the result is a static table.
- A function-generated table uses at most one of the following to trigger the function call:
A function-generated table is designed to ingest data from external sources into ticking tables. The only requirement is that the Python function that ingests this data returns a table, or returns None to retain the previous result.
Table generator function
You can define your function in the normal Pythonic way. The only requirement is that the function must return a table, or None to keep the previous result.
Here's an example:
Call function_generated_table
The following code block uses make_table as the table generator function. function_generated_table is called twice:
- Once with a trigger table.
- Once with a refresh interval.
Weather data
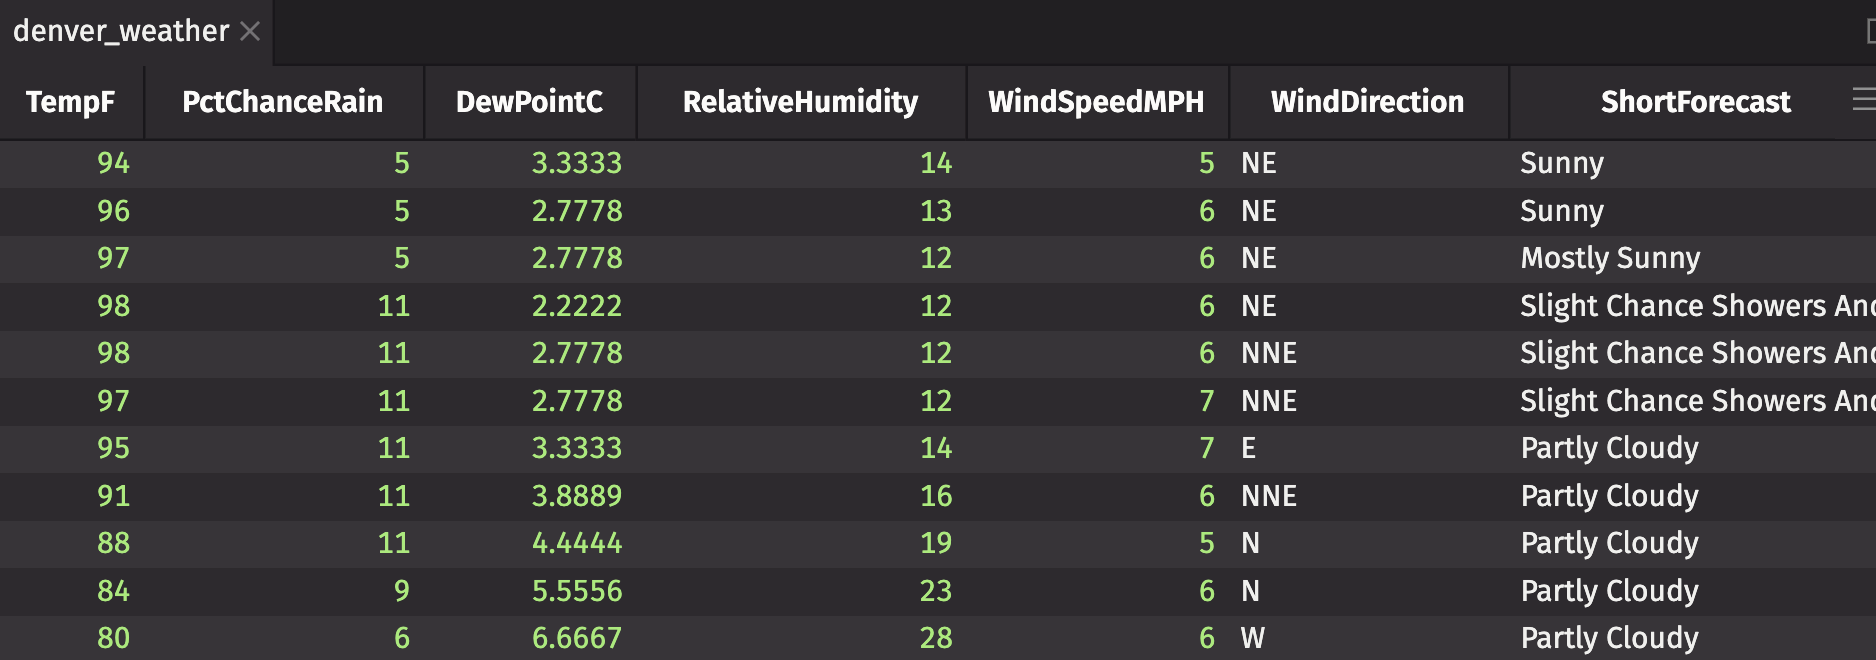
The following example pulls weather from NOAA's free-to-use Weather API for the city of Denver, Colorado. The trigger table ticks once per minute.
Execution context
Function-generated tables require an execution context to run in. If you don't specify an execution context, the method will use the systemic execution context. The example above does not specify an execution context, so the systemic execution context is used.
Additional options
Beyond the trigger, function_generated_table accepts several optional parameters that control how the result is produced and shaped.
Retain the previous result
The table_generator function can return None to decline producing a new table on a given cycle. When it does, the previous cycle's result is retained instead of being regenerated. This is useful when new data is not always available. When the first invocation returns None, supply a table_definition so the result's columns are known before the first table exists.
How the result updates
Every refresh in which the table_generator produces a table replaces the result in full. The table update removes all of the previous rows and adds all of the newly generated rows, with no modified rows and no shifts, even when the generated data is identical to the previous cycle's. A refresh in which the table_generator returns None produces no update, as described in Retain the previous result. Downstream operations therefore reprocess the entire result on every refresh that produces a table. This is why regular table operations, which update incrementally, are preferable when the input is already a Deephaven table.
The copy_data and blink_table options below refine this behavior. They are independent of one another: copy_data controls where the result's data lives and what its row keys look like, and blink_table controls how downstream operations interpret each update.
Copy data or delegate to the generated table
By default (copy_data=True), the generated rows are copied into the result's own column sources, and the result uses a flat, contiguous row set with row keys 0 through size - 1. The generated table itself is not retained.
With copy_data=False, the result skips the copy and delegates directly to the generated table's column sources, adopting the generated table's row set as-is. The added rows of each update are exactly the generated table's row set, and the removed rows are the previous cycle's row set. Because the result holds the generated column sources across cycles, a refreshing generated table must expose immutable column sources; a generated table that changes values in place is rejected. A static table produced fresh on each refresh — for example, via snapshot — always satisfies this requirement.
Present the result as a blink table
Set blink_table=True to present the result as a blink table, so downstream operations see only the rows generated during the current cycle. Each update is still the same full replacement described above; the blink attribute changes how downstream operations interpret it, not how the rows are copied or delegated. Rows generated in one update cycle are removed on the next cycle whether or not the table_generator runs again, so with a refresh interval longer than one cycle the result is empty between refreshes. A blink table requires a refresh trigger. On a cycle where the table_generator returns None, the blink result is cleared.
Specify the table definition
When you supply a table_definition, it is authoritative: it defines the result's columns and their order, and every table the table_generator produces must be compatible with it. A definition is required when the first invocation returns None, since the columns must be known before the first table exists.