Write data to an in-memory, real-time table
This guide covers two ways to publish data to in-memory ticking tables:
table_publisher publishes data to a blink table, while DynamicTableWriter writes data to an append-only table. Both can ingest data from external live sources, such as WebSockets. We recommend table_publisher in most cases: it has a newer, more flexible, and more performant API, and it supports blink tables natively. DynamicTableWriter can be more convenient when you add very few rows (for example, one) at a time and want a simple interface.
Table publisher
The table_publisher factory function creates a TablePublisher and its linked blink table. From there:
- Add data to the blink table with
add. - (Optionally) Store data history in a downstream table.
- (Optionally) Shut the publisher down when finished.
More sophisticated use cases add steps but follow the same basic formula.
Example: getting started with a table publisher
The first four arguments of table_publisher are:
name: the publisher's name.col_defs: the blink table's column definitions, such as a dictionary that maps column names to data types. SeeTableDefinitionLikefor all accepted forms.on_flush_callback: an optional function that runs at the start of each update cycle.on_shutdown_callback: an optional function that runs once when the publisher shuts down.
This example passes an on-shutdown callback and no on-flush callback. table_publisher returns the linked blink table and the TablePublisher, in that order.
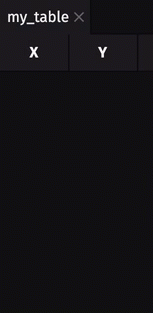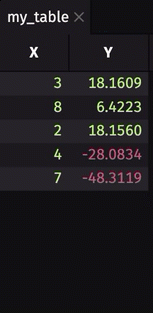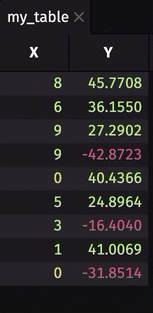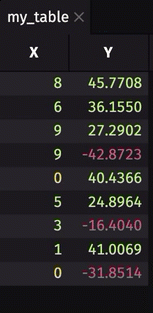
The following code creates a blink table with three columns (X, Y, and Z). The columns contain no data until you call add, which the example's add_table function wraps.
Each call to add_table adds rows to my_table. The rows appear on the next update cycle after the command that adds them finishes. For details, see Data appears on the next update cycle.
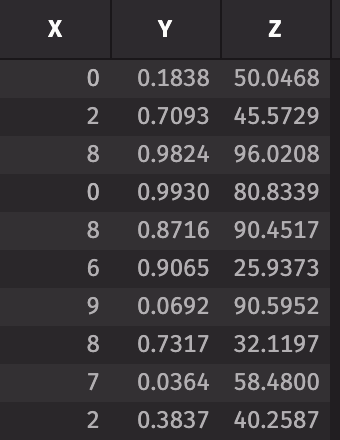
To stop the TablePublisher, call publish_failure. This notifies the blink table's listeners of the failure, so downstream tables show an error. It also invokes the on-shutdown callback, and later calls to add return without publishing. In this example, the when_done function calls publish_failure.
Example: threading
The getting started example adds data to its blink table only when you call add_table by hand. In most real-world use cases, you want to add data automatically at a regular interval. Python's threading module can do this. The following example adds between 5 and 10 rows of data to my_table via empty_table every second for 5 seconds.
Important
Table operations that run in a separate thread and compile query strings, such as update, need an execution context. Without one, they raise an exception. Capture the current context with get_exec_ctx and open it in the thread with a with statement.
Data history
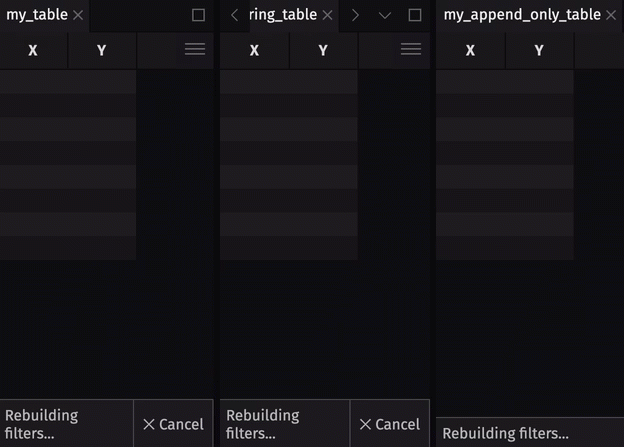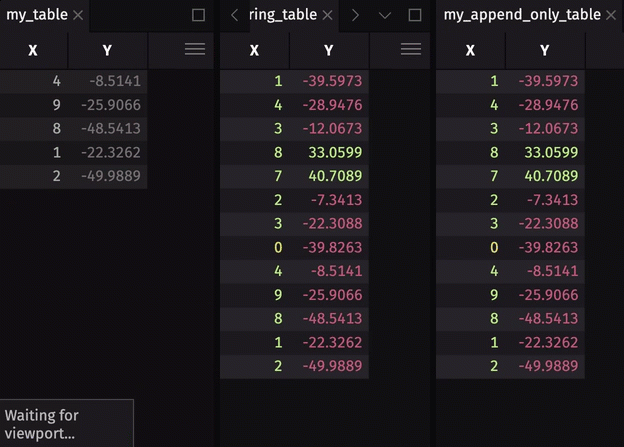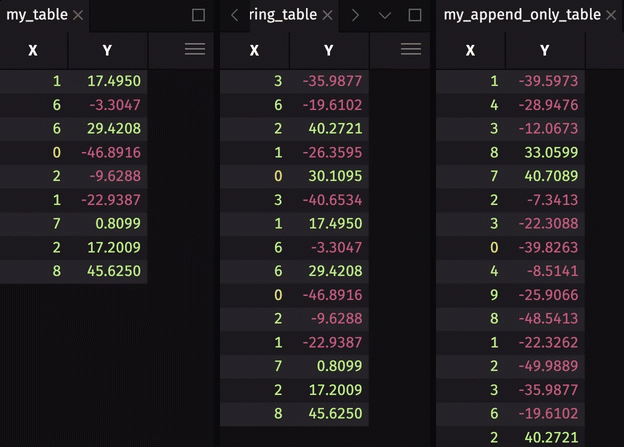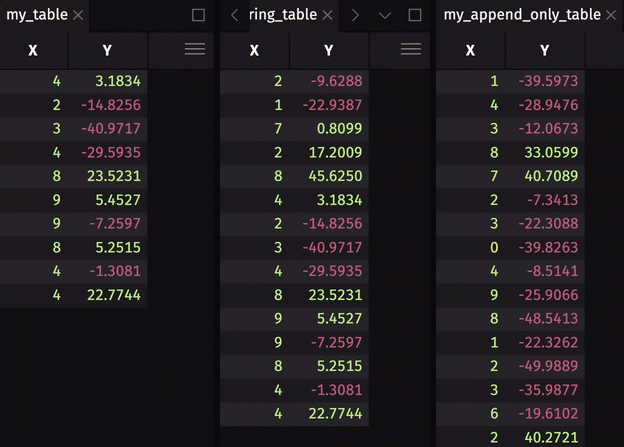
Table publishers create blink tables. Deephaven processes new data in periodic update cycles. A blink table keeps only the rows added in the current cycle and drops them when the next cycle starts, so it stores no data history. In most use cases, you want to store some or all of the rows written during previous update cycles. There are two common ways to do this:
- Store some data history by creating a downstream ring table with
ring_table. - Store all data history by creating a downstream append-only table with
blink_to_append_only.
See the table types user guide for more information on these table types, including which one is best suited for your application.
The following code block builds on the threading example. It reuses that example's my_table and thread_func, creates a downstream ring table and append-only table from my_table, and then starts a new thread that adds more data to my_table.
Example: asyncio
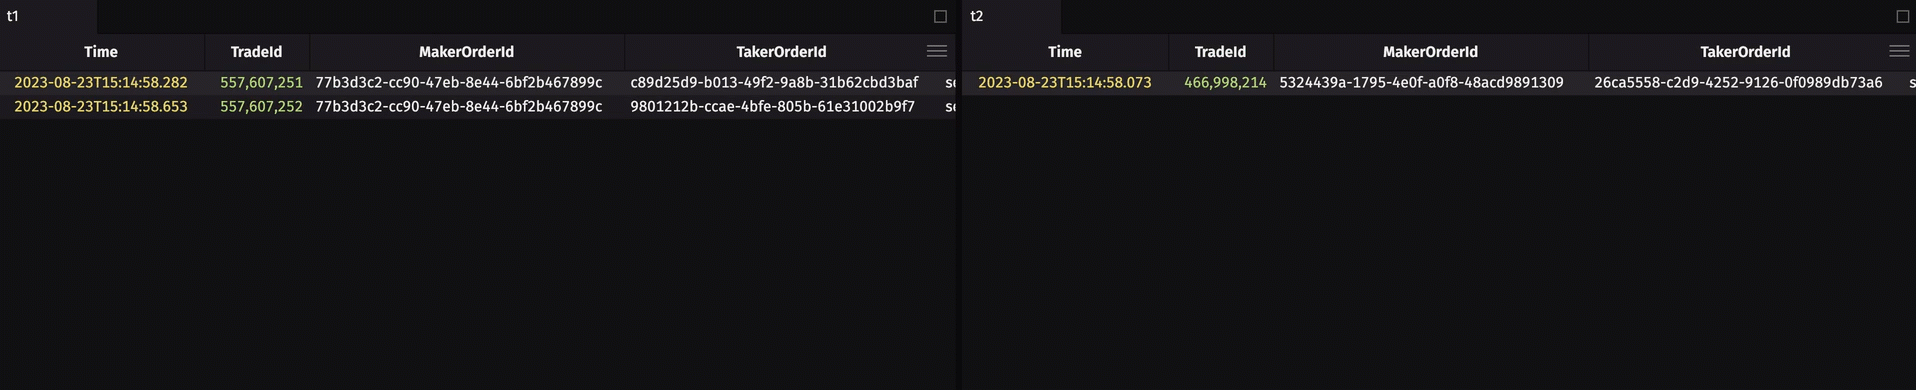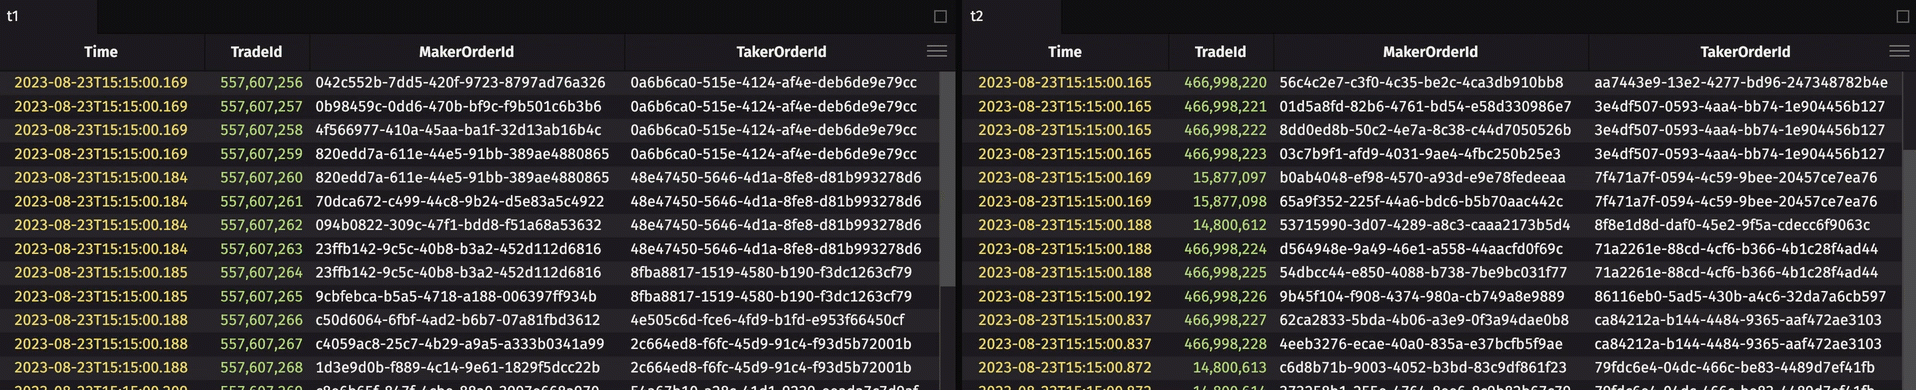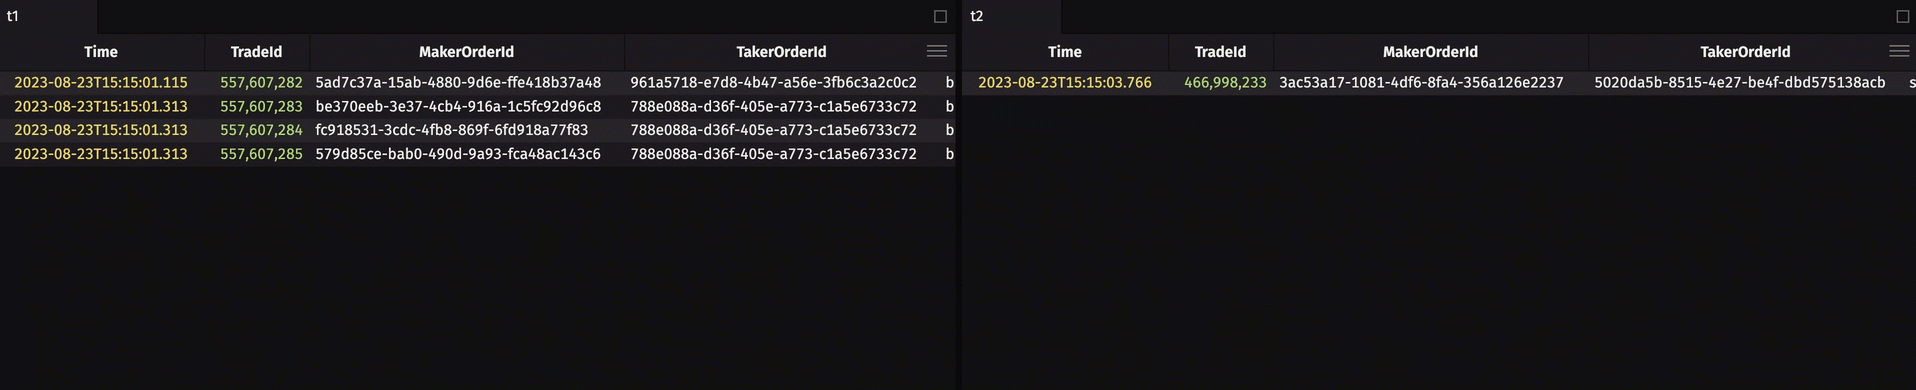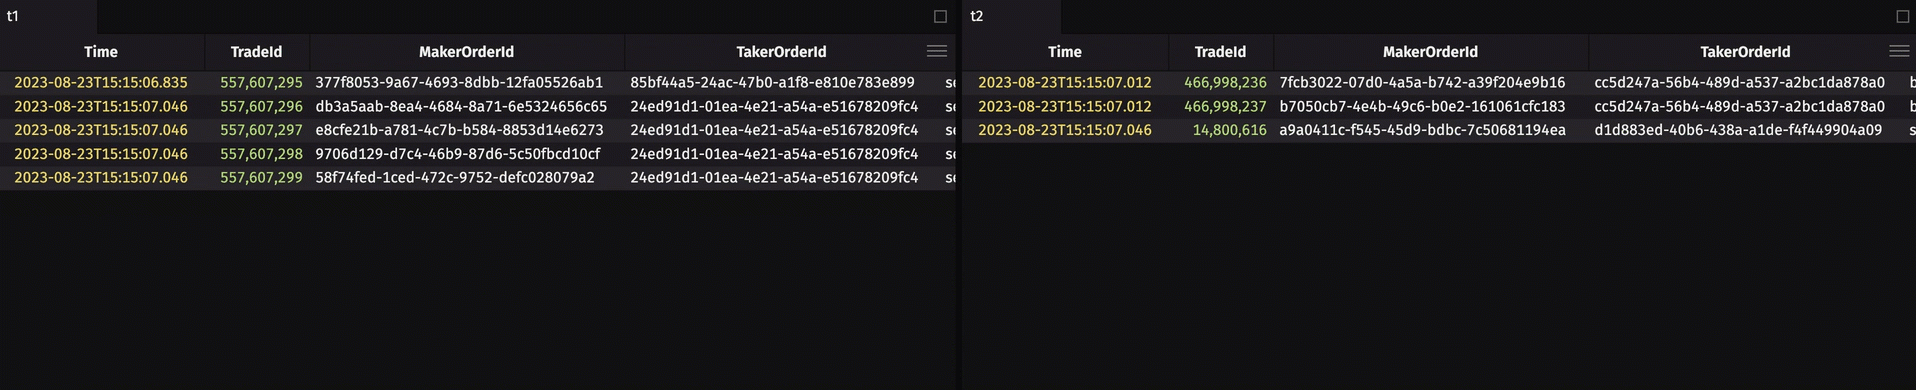
The following code block pulls cryptocurrency trade data from Coinbase's WebSocket feed. It ingests the data asynchronously on an asyncio event loop that runs in a background thread, so a single thread can serve several WebSocket subscriptions without blocking the console.
The code collects incoming WebSocket messages in the my_matches list instead of adding them to the publisher one at a time. The on_flush_callback passed to table_publisher runs once at the beginning of each update cycle, so on_flush adds everything collected since the previous cycle as one table. Keep the flush callback fast, because it blocks the update cycle while it runs.
The on_shutdown_callback cancels the WebSocket task when the publisher shuts down.
Note
Install the websockets package before you run the code below.
DynamicTableWriter
DynamicTableWriter writes data into a live, in-memory table whose column names and data types you define. To use it:
- Create the
DynamicTableWriter. - Get the table that the writer writes to.
- Write data to the table, typically from a separate thread so that rows appear while writing continues (see Data appears on the next update cycle).
- Close the writer.
Example: getting started with DynamicTableWriter
The following example creates a table with two columns (A and B). The columns contain randomly generated integers and strings, respectively. A separate thread adds a new row every second for ten seconds. When the thread finishes writing, it closes the writer with close.
Example: trig functions
The following example writes rows with an X column and its sine, cosine, and tangent in the SinX, CosX, and TanX columns, and plots the sine and cosine with Deephaven Express as the table updates.
Data appears on the next update cycle
Neither a table publisher nor a DynamicTableWriter adds rows to its table immediately. A table publisher's add and a writer's write_row both queue the new rows. The queued rows reach the table when the table's update source next refreshes, which happens once per cycle of the Update Graph (UG). The UG is the engine component that processes table updates. Rows queued from a background thread can appear in a cycle that is already running, if they arrive before that refresh. Rows added from a table publisher's on-flush callback, which runs at the start of a cycle, appear in that same cycle.
The Python script session holds the exclusive UG lock while a command executes, so that cycle cannot run until the command finishes. As a result, new rows do not appear in output tables while the command that wrote them is still running.
The following example shows this with a DynamicTableWriter, whose append-only table keeps the rows so you can inspect them afterward. What would you expect the print statement below to produce?
The print statement prints True: it runs in the same command as the write_row calls. The Python script session holds the exclusive UpdateGraph lock while a command executes, so the UG cycle that adds the queued rows to result can't run until the command finishes.
A second command can still start before that cycle runs, so wait for the table to update if it is still empty. Then the same print statement prints False.
In a standard Deephaven server, the Periodic Update Graph drives these update cycles. To learn how update cycles propagate changes through your queries, see Deephaven's table update model.