Single aggregation
This guide shows you how to compute summary information on groups of data using single (dedicated) aggregations.
Often when working with data, you want to break the data into subgroups and then perform calculations on the grouped data. For example, a multinational corporation might want to know its average employee salary by country, or a teacher might want to calculate grade information for groups of students or in certain subject areas.
The process of breaking a table into subgroups and then performing a single type of calculation on each subgroup is known as "single aggregation" or "dedicated aggregation." "Aggregation" refers to creating a summary of the data within each group. "Single" or "dedicated" means that only one type of calculation runs at a time.
To compare single aggregations with the other ways Deephaven summarizes data, and to choose between them, see Aggregations in Deephaven.
Deephaven provides many dedicated aggregations, such as max_by and min_by. These aggregations are good options when you need only one type of aggregation. If you need more than one type of aggregation or have a custom aggregation, multi-aggregation, also called combined aggregation, is a more efficient and more flexible solution.
Syntax
The general syntax is:
Replace DEDICATED_AGG with one of the aggregators listed in Single aggregators. The by parameter determines the column(s) by which to group data:
- Omitting
by(for example,source.last_by()) or passing[]uses the whole table as a single group. ["X"]outputs the desired value for each group in columnX.["X", "Y"]outputs the desired value for each group designated from theXandYcolumns."X", a single column name passed as a string, is the same as["X"].
You can also pass by by position instead of by keyword, so source.last_by(["Name"]) is the same as source.last_by(by=["Name"]).
Some aggregators take a required argument before the grouping columns:
head_byandtail_bytake the number of rows.count_bytakes the name of the count column.weighted_avg_byandweighted_sum_bytake the weight column.
Single aggregators
Each dedicated aggregator performs one calculation at a time:
abs_sum_by- Sum of absolute values of each group.avg_by- Average (mean) of each group.count_by- Number of rows in each group.first_by- First row of each group.group_by- Group column content into vectors, one row per group.head_by- Firstnrows of each group.last_by- Last row of each group.max_by- Maximum value of each group.median_by- Median of each group.min_by- Minimum value of each group.std_by- Sample standard deviation of each group.sum_by- Sum of each group.tail_by- Lastnrows of each group.var_by- Sample variance of each group.weighted_avg_by- Weighted average of each group.weighted_sum_by- Weighted sum of each group.
The examples on this page cover every aggregator in this list except abs_sum_by, group_by, weighted_avg_by, and weighted_sum_by. For those four, see the examples on their reference pages.
Select and count rows in each group
In the following examples, we have test results in various subjects for some students. We want to summarize each student's results.
first_by and last_by
In this example, we want to know the first and the last test results for each student. To achieve this, we can use first_by to return the first test value and last_by to return the last test value. The example groups the results by Name.
For how last_by decides which row is last, and how to get the last row after sorting by a column, see Find the last row for each key.
head_by and tail_by
In this example, we want to know the first two and the last two test results for each student. To achieve this, we can use head_by to return the first two test values and tail_by to return the last two test values. The example groups the results by Name.
count_by
In this example, we want to know the number of tests each student completed. count_by returns the number of rows in the table as grouped by Name and stores that in a new column, NumTests.
Summary statistics aggregators
The following examples use the source table of student test results created in Select and count rows in each group. It has a Name column, a string Subject column, and an integer Number column of scores. Because of the type restrictions below, the examples remove the string column Subject with drop_columns, so each result contains only score statistics.
Caution
sum_by, avg_by, std_by, and var_by raise an error on a column of an unsupported type, such as a string column. These aggregators accept string columns:
median_byreturns the middle value in sort order.min_byreturns the smallest value in sort order.max_byreturns the largest value in sort order.
In sort order, uppercase letters come before lowercase letters.
sum_by
In this example, sum_by calculates the sum of test scores for each Name.
avg_by
In this example, avg_by calculates the average (mean) of test scores for each Name.
std_by
In this example, std_by calculates the sample standard deviation of test scores for each Name.
var_by
In this example, var_by calculates the sample variance of test scores for each Name.
median_by
In this example, median_by calculates the median of test scores for each Name.
min_by
In this example, min_by calculates the minimum of test scores for each Name.
max_by
In this example, max_by calculates the maximum of test scores for each Name.
Find the last row for each key with last_by
The last_by operation creates a new table that contains the last row of the input table for each key. The key columns are the grouping columns you pass to last_by. A key is one unique value or combination of values in those columns. first_by follows the same rules but returns the first row for each key.
The "last" row is the row closest to the bottom of the table. It depends only on the order of rows in the source table. It does not depend on values in the data, such as timestamps or sequence numbers. In a live-updating table, it is not necessarily the row that most recently arrived.
When you pass no key columns, last_by returns the last row in the table:
When you pass key columns (such as MyKey in the example below), last_by returns the last row for each key:
You can use multiple key columns:
You often use last_by with time series data to get a table that shows the current state of each key. When data is out of order, sort it before applying last_by. For example, the data below is naturally ordered by Timestamp1. To find the latest rows based on Timestamp2, sort the data before running last_by:
If the query doesn't use the sorted table anywhere else, use agg.sorted_last instead of sorting first. It avoids sorting the whole table:
- It splits the rows into groups by the key columns.
- Within each group, it finds the row with the largest sort-column value.
- It doesn't build a sorted copy of the whole table, so it typically uses less memory and processing than
sortfollowed bylast_by.
To use it, pass agg.sorted_last to agg_by and set order_by to the column to sort by. The example below reuses t from the previous example and picks the same row for each key as that example's t2, without creating an intermediate sorted table. The key column comes first and rows can appear in a different order. Unlike last_by, it returns only the key columns and the columns listed in cols, so the example lists Timestamp2 too.
Aggregate columns in the UI
You can also aggregate a column in the UI with the Aggregate Columns feature. Unlike the programmatic examples above, it doesn't create a new table with one row per group. Instead, it adds a row at the top or bottom of the table that applies the operation you choose to each column. Use it to quickly see the sum, average, or another aggregate of a column.
In the example below, we add an Average row and a Minimum row to the top of the table:
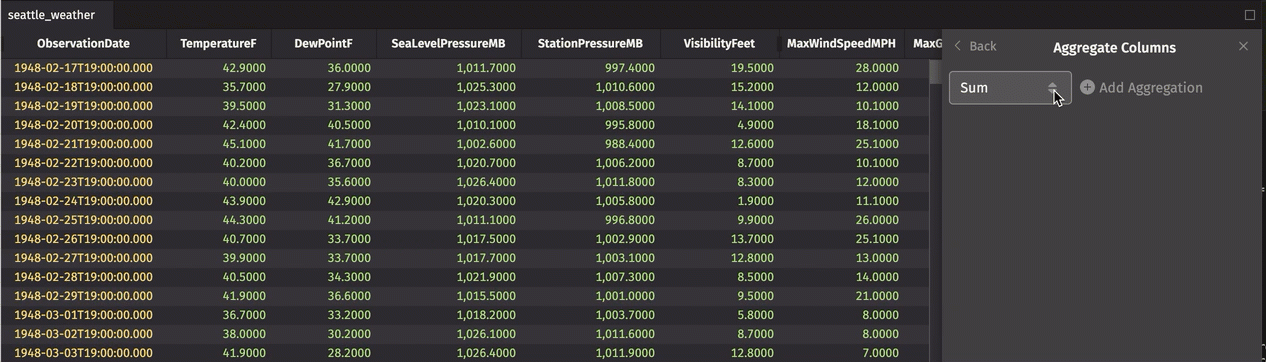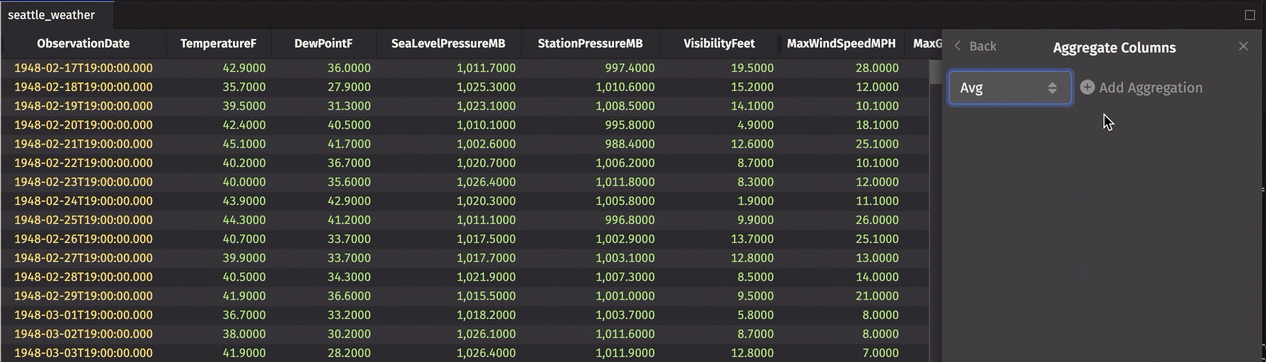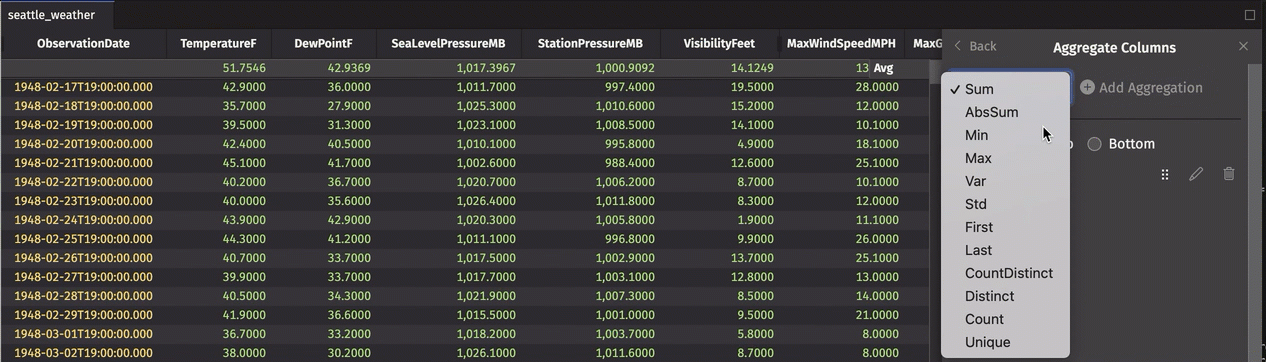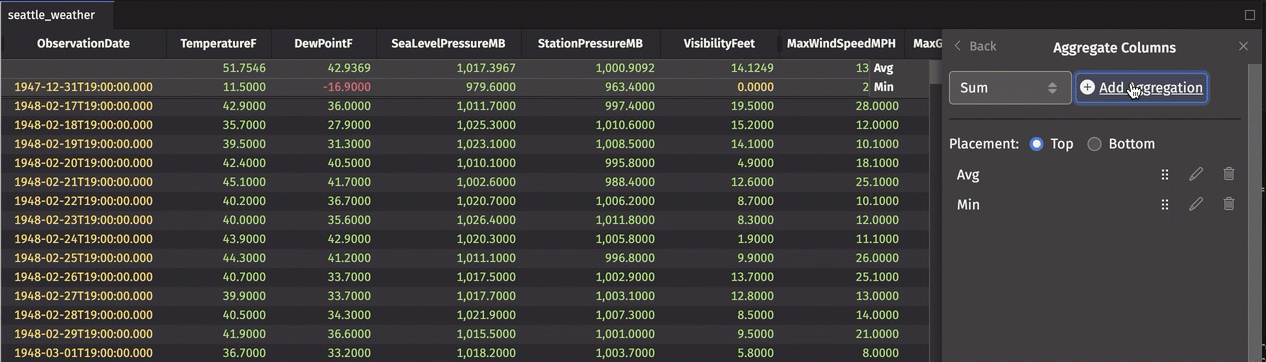
You can reorder, edit, or delete these aggregations in the Aggregate Columns dialog.